# Deploy your first service
By the end of this guide you will have a real application running on the internet: a Next.js feedback board, backed by a PostgreSQL database and an object storage bucket, reachable over HTTPS on a domain of its own.
It takes about fifteen minutes, most of it spent waiting for a build, and you will not write a Dockerfile, a pipeline config, or a line of YAML along the way.
You need a GitHub account. If you don't have one, [sign up here](https://github.com/signup) first. Everything else happens in the Lucity dashboard.
::steps{level="2"}
## Create your Lucity account
Head to [lucity.cloud/app/login](https://lucity.cloud/app/login) and click **Continue with GitHub**.
Signing in also installs the Lucity GitHub App, which is how Lucity reads your source code. GitHub will ask which repositories to grant access to. You can pick **All repositories** or select them one by one. Either way you can change it later, and Lucity only ever reads: it never writes to your repository.
:::note
The first 14 days are free, up to €5 of usage, whichever runs out first. No credit card needed to get started. The badge in the dashboard header tracks what's left.
:::
## Fork the example app
The app we're deploying is called [Vouch](https://github.com/zeitlos/vouch): a small feedback board where people post ideas, vote on them, and optionally attach a screenshot.
It's worth a quick look at the code before you deploy it. Vouch is a Next.js 15 app that talks to PostgreSQL through `pg` and to any S3-compatible store through the AWS SDK. What it does *not* have is a Dockerfile, and that's the point. Lucity [builds container images straight from source](https://lucity.cloud/docs/builds), detecting the language, framework, build command, and start command on its own.
Click **Fork** on the repository page to get your own copy. The rest of this guide assumes you're working from your fork.
:fork-button
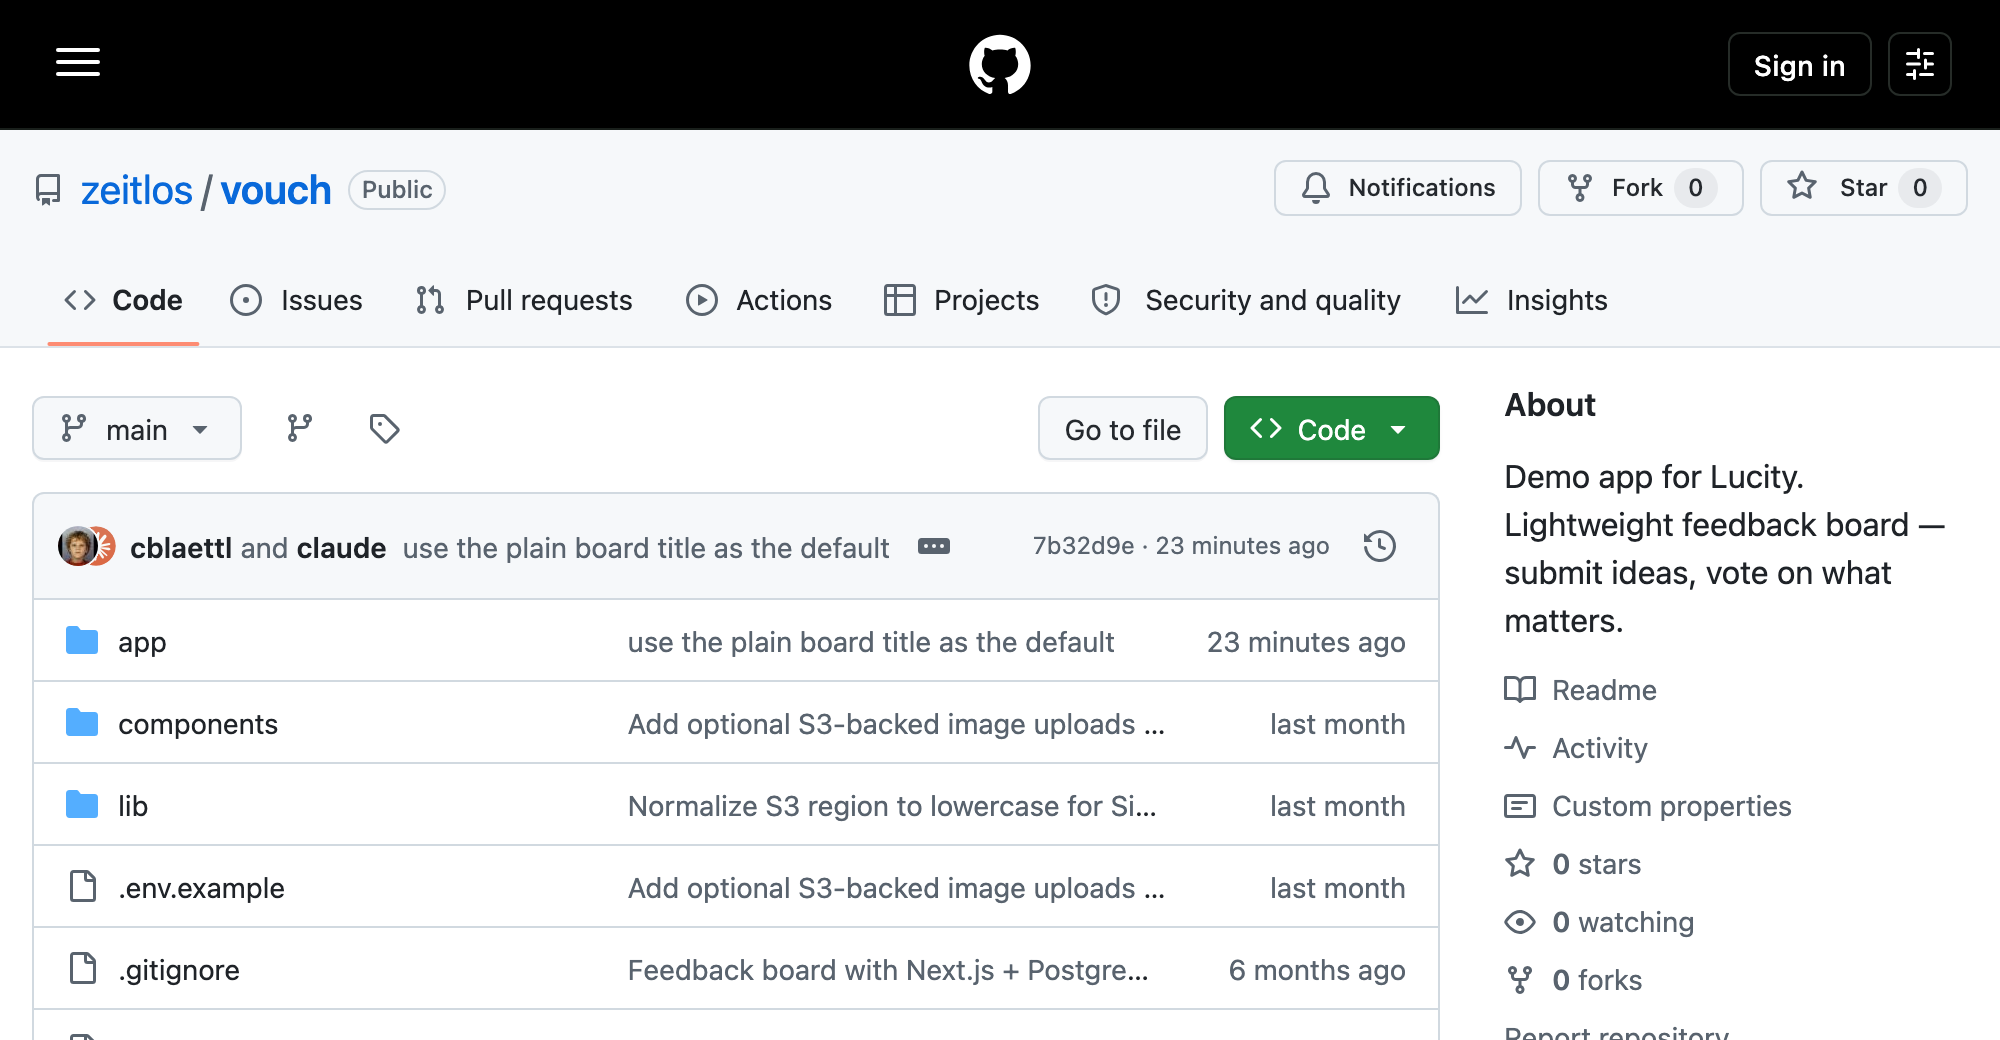
*Your own copy of the repository. Everything after this points at the fork.*
## Create a project
Signing in drops you on the Projects page, which lists every project in your workspace and is empty on a fresh account. Click **New** in the top right and a command palette opens. Choose **GitHub Repository**, pick the account or organization that holds your fork, then search for `vouch` and select it.
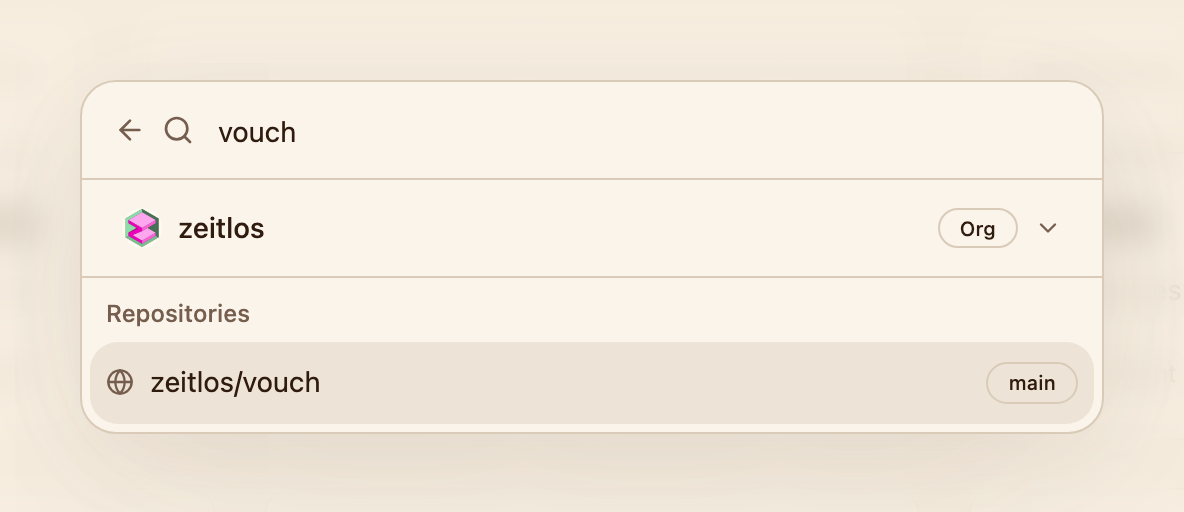
*The palette lists the repositories the Lucity GitHub App can see.*
Lucity inspects the repository, recognizes a Next.js app, and proposes a project and service name. Confirm those and you land on the project canvas, where your new service is already building.
A [project](https://lucity.cloud/docs/projects) is the container for everything your application needs. The canvas is where you see it: services, databases, buckets, and how they're wired together. Every project starts with a **development** [environment](https://lucity.cloud/docs/environments), and you can add more later.
## Watch it build
Click the service node on the canvas to open the service panel, then stay on the **Deployments** tab. You'll see [the deployment move through its phases](https://lucity.cloud/docs/deployments), and **Logs** gives you [the raw build output](https://lucity.cloud/docs/logs) as it streams in.
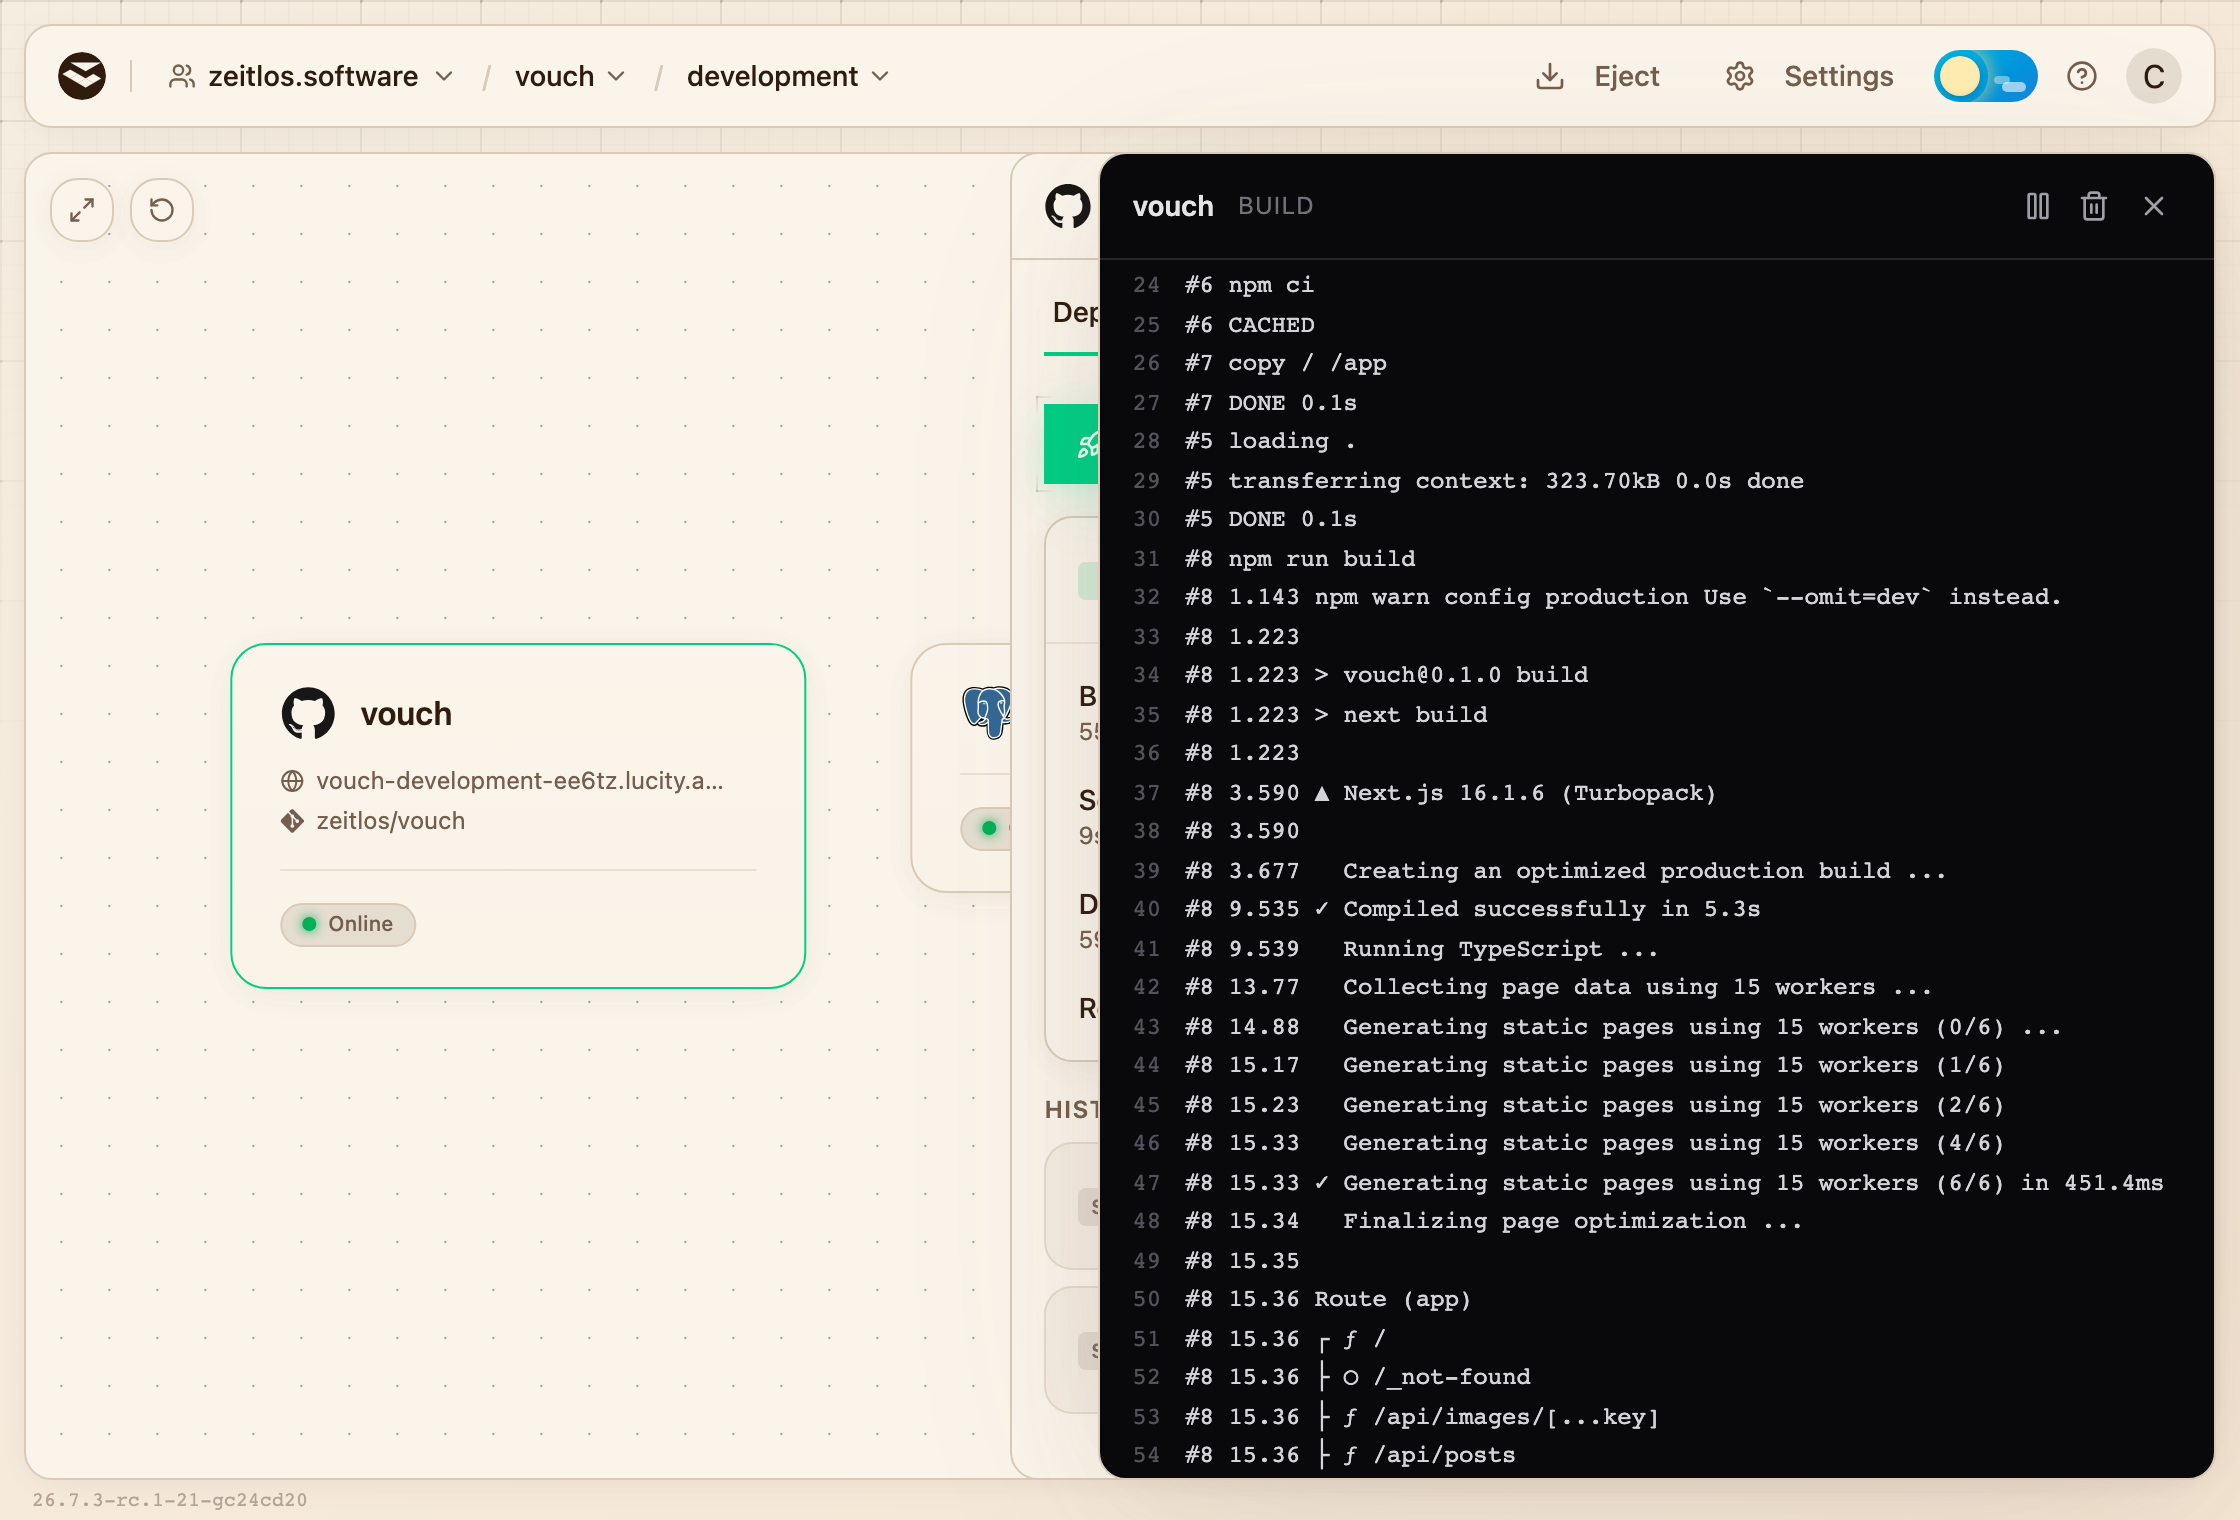
*Build logs stream live: dependency install, framework build, image push.*
First builds usually take two to three minutes, because there is no dependency cache to reuse yet. Later builds are faster.
When the image is built and the container is running, the service reports **Online**. Your app is up. It just has no way to reach it yet.
## Put it on the internet
Open the **Settings** tab in the service panel and scroll to **Platform Domain**, then click **Generate Domain**.
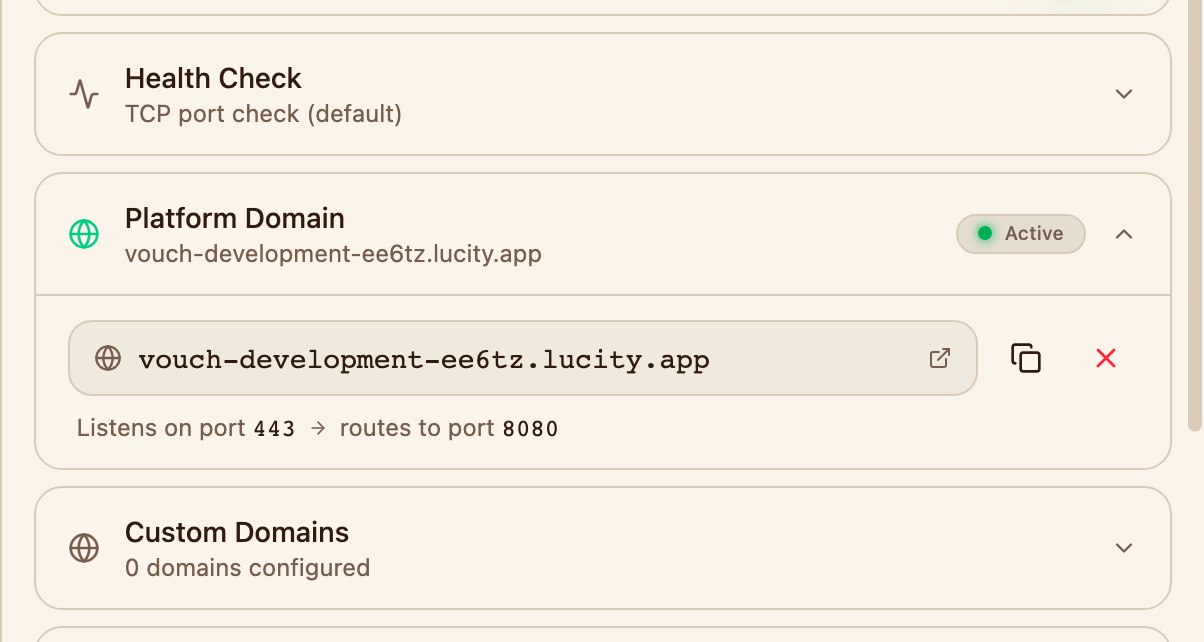
*One click issues the hostname, certificate included.*
A few seconds later you have something like `vouch-development-a1b2c3.lucity.app`, with a valid certificate and HTTPS already in place. Click it.
When you are ready to put this on a hostname you own, the **Custom Domains** section right below works the same way. See [domains](https://lucity.cloud/docs/domains) for what that involves.
There's your feedback board, live on the internet. It also says **Database not connected**, which is fair, because it isn't. Let's fix that.
## Add a PostgreSQL database
Back on the canvas, click **Create** in the top right and choose **PostgreSQL**. Name it `feedback` and confirm. A [database](https://lucity.cloud/docs/postgres) node appears next to your service and starts provisioning.
Now connect the two. Click the service node, open the **Variables** tab, and click **Add Variable**:
1. Enter `DATABASE_URL` as the key.
2. Click the link icon in the value field.
3. Pick `fqdn-uri` from the **Postgres: feedback** group.
4. Save.
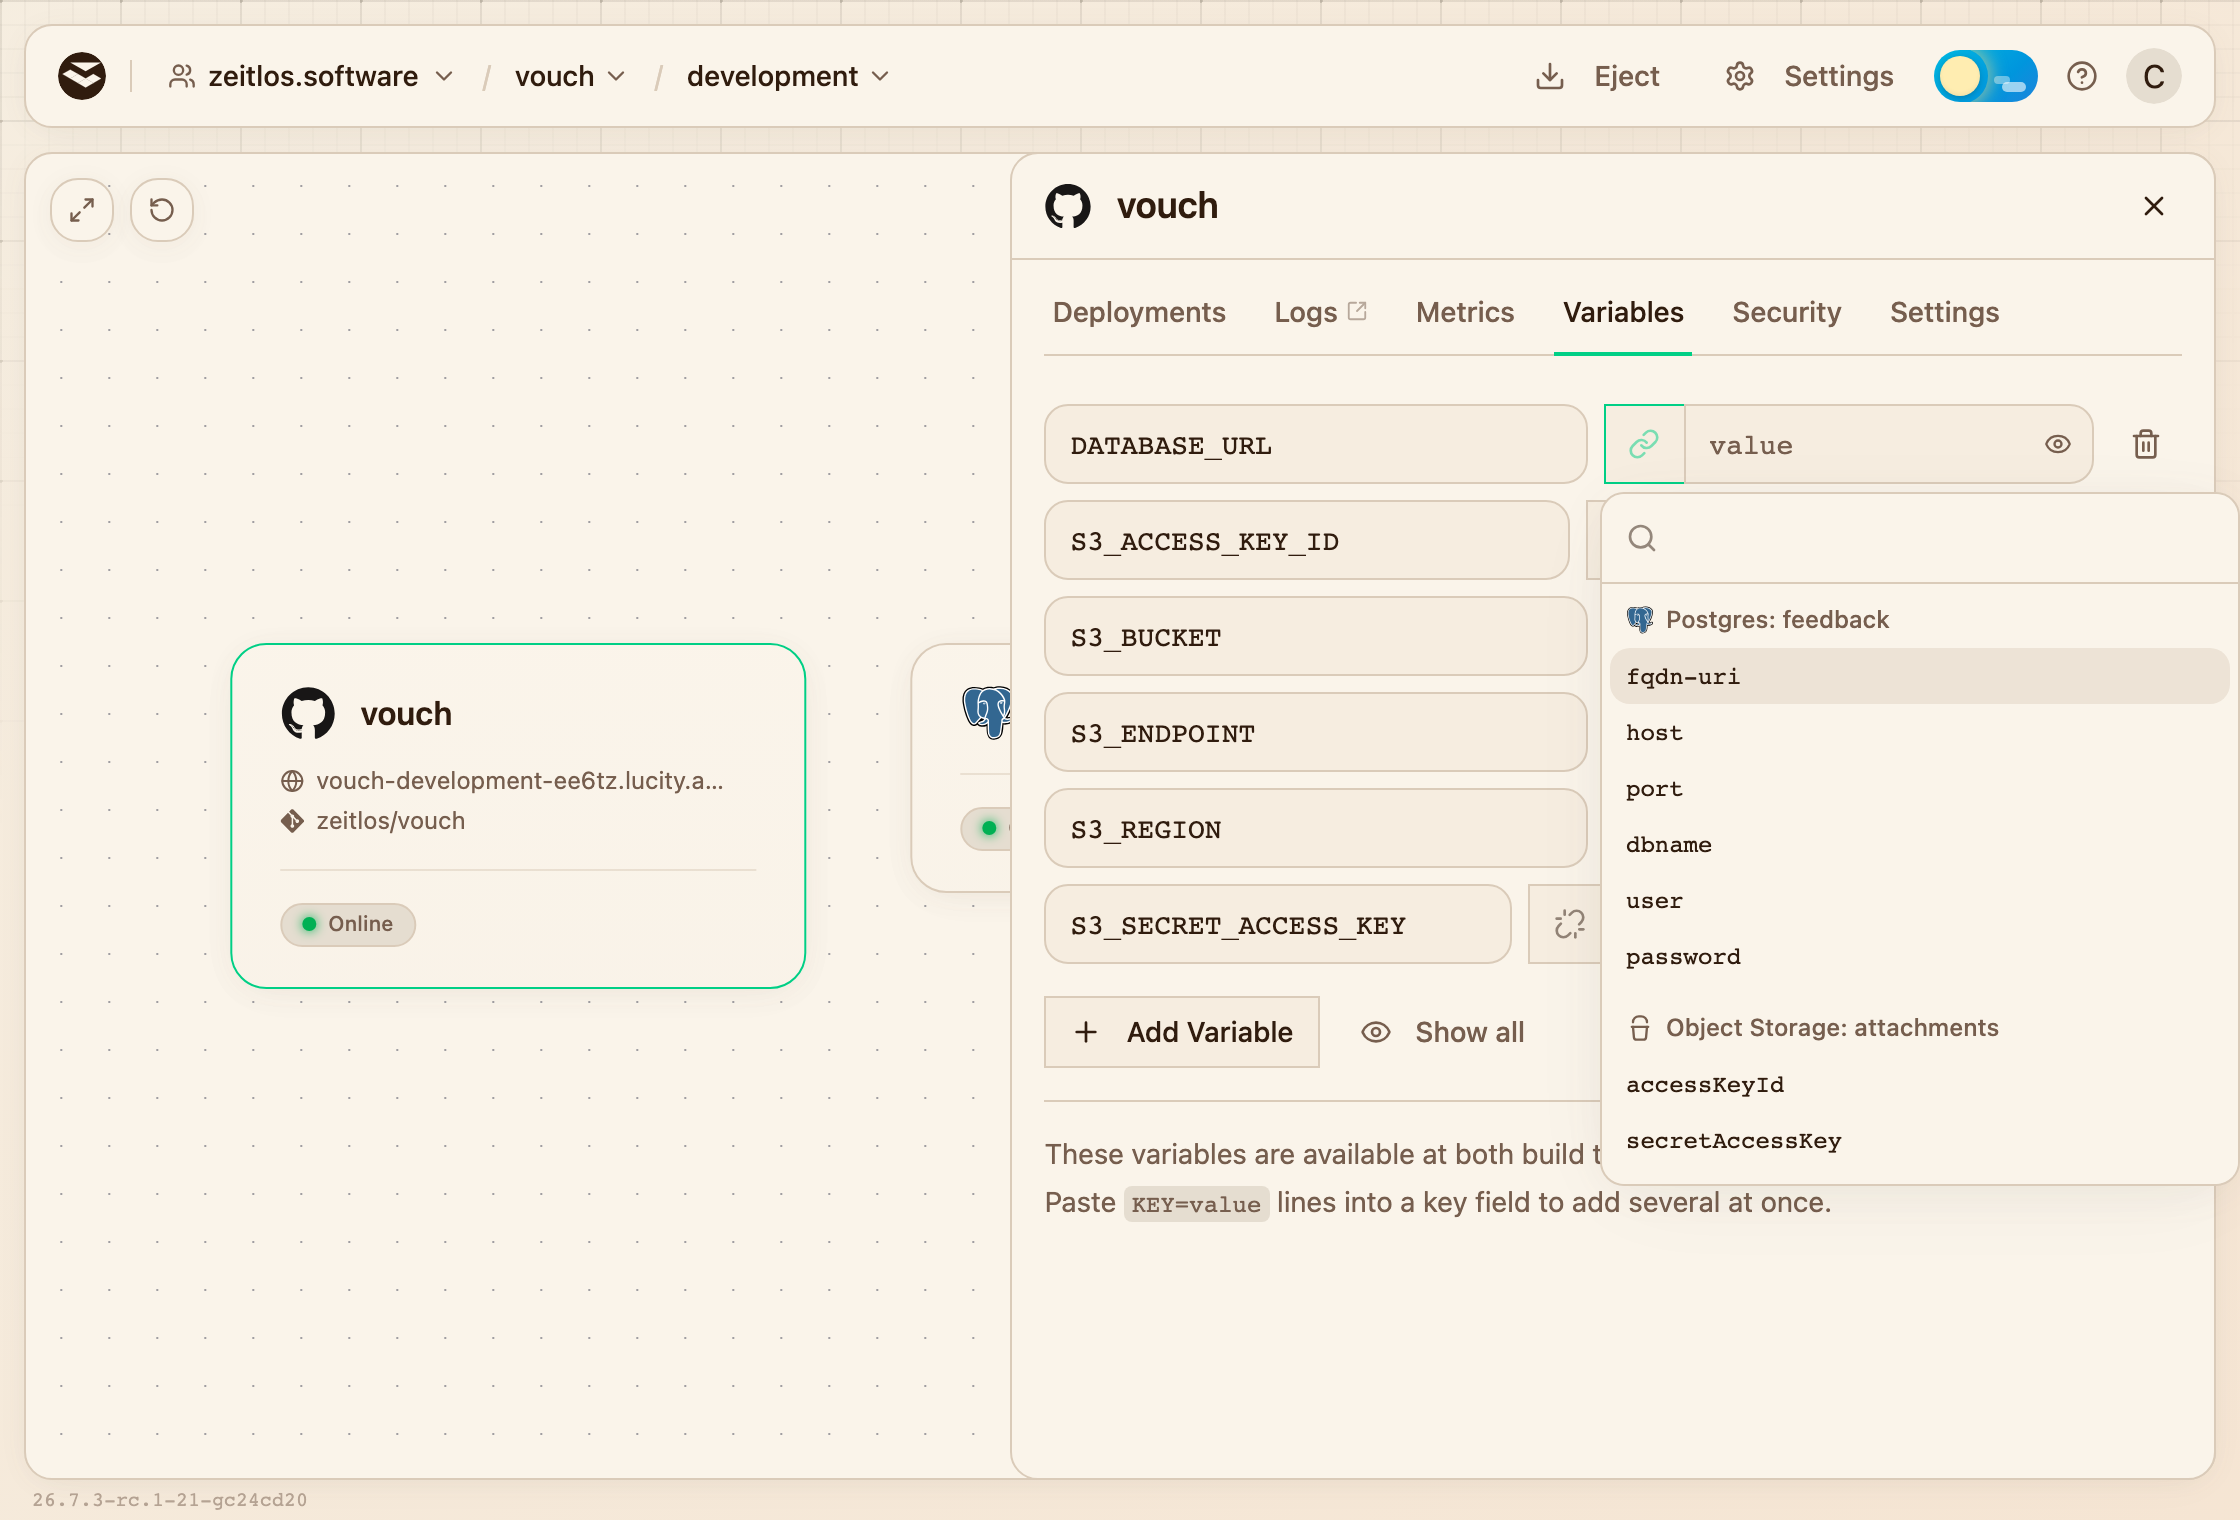
*Linking `DATABASE_URL` to a value the platform owns, instead of pasting a connection string.*
That's a [dynamic variable](https://lucity.cloud/docs/variables): instead of pasting a connection string, you point at a value the platform owns. Lucity keeps it current, the credentials never sit in your repository or in your clipboard, and if the database is ever rebuilt or rotated the variable still resolves.
Saving variables rolls the service out again with the same image, so it's live in seconds. Only a source change triggers a new build.
Reload the app. The warning is gone, and the board is now writing to a real database. Add a few posts so there is something to look at.
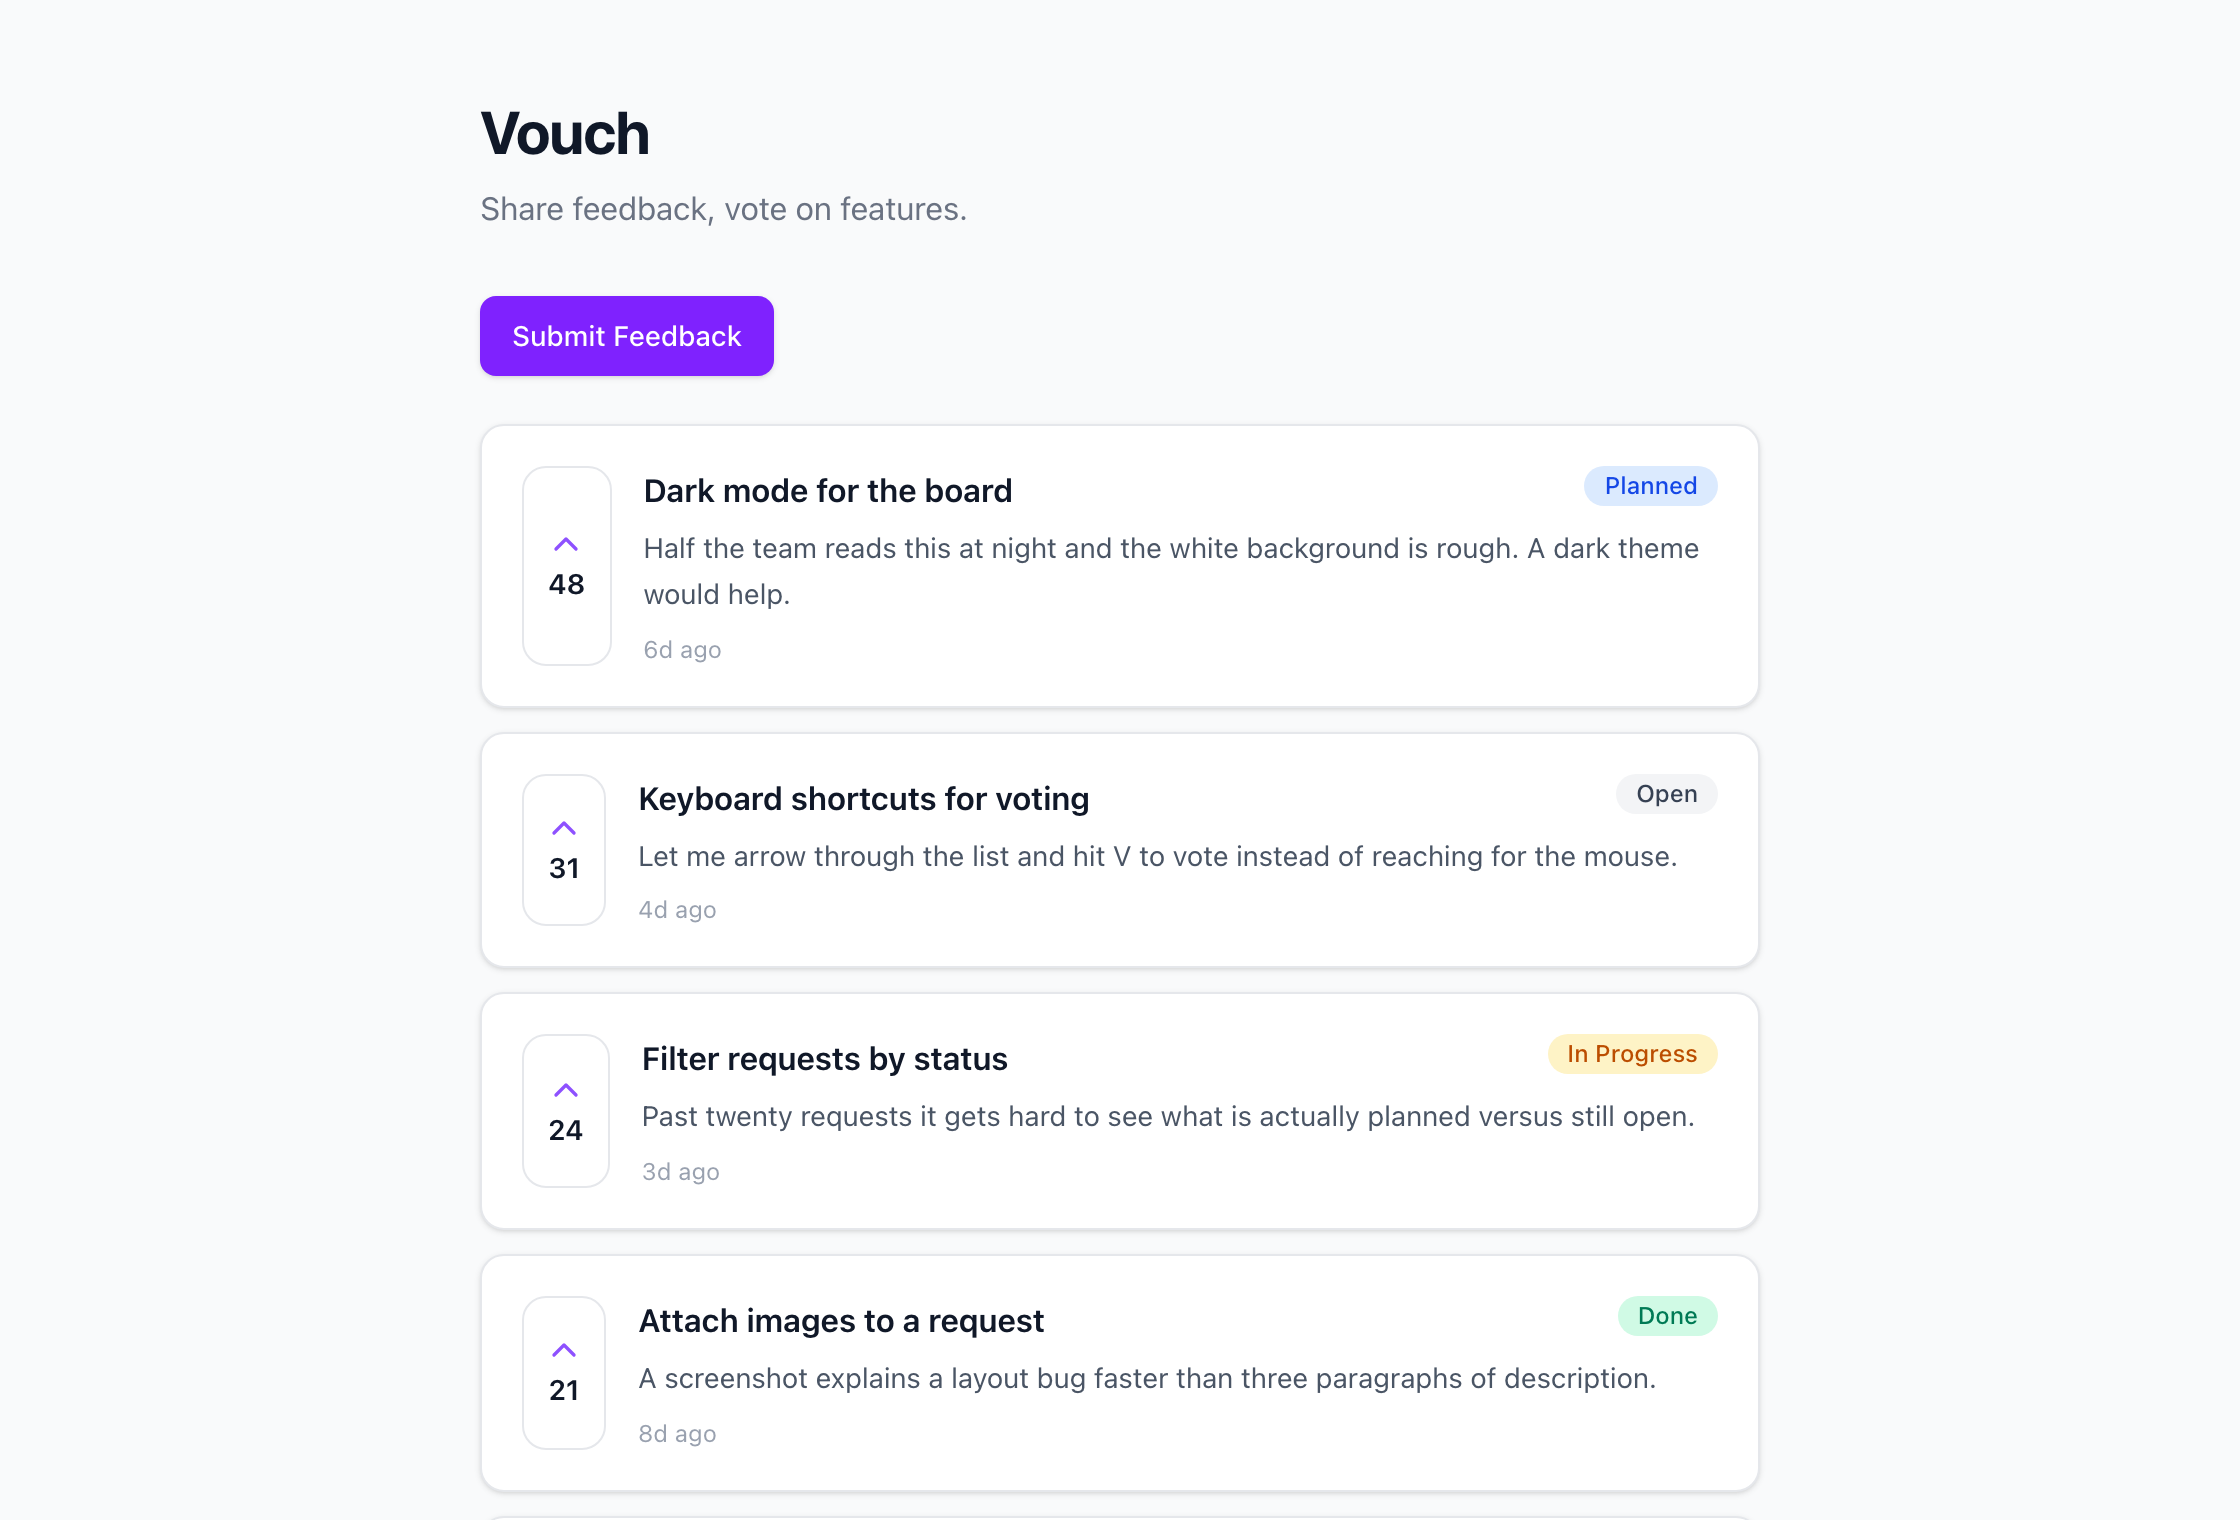
*The board on its own domain, with the posts stored in the linked database.*
Now click the database node on the canvas and open the **Tables** tab. Select `posts` and you're looking at the rows you just created, straight from the dashboard.
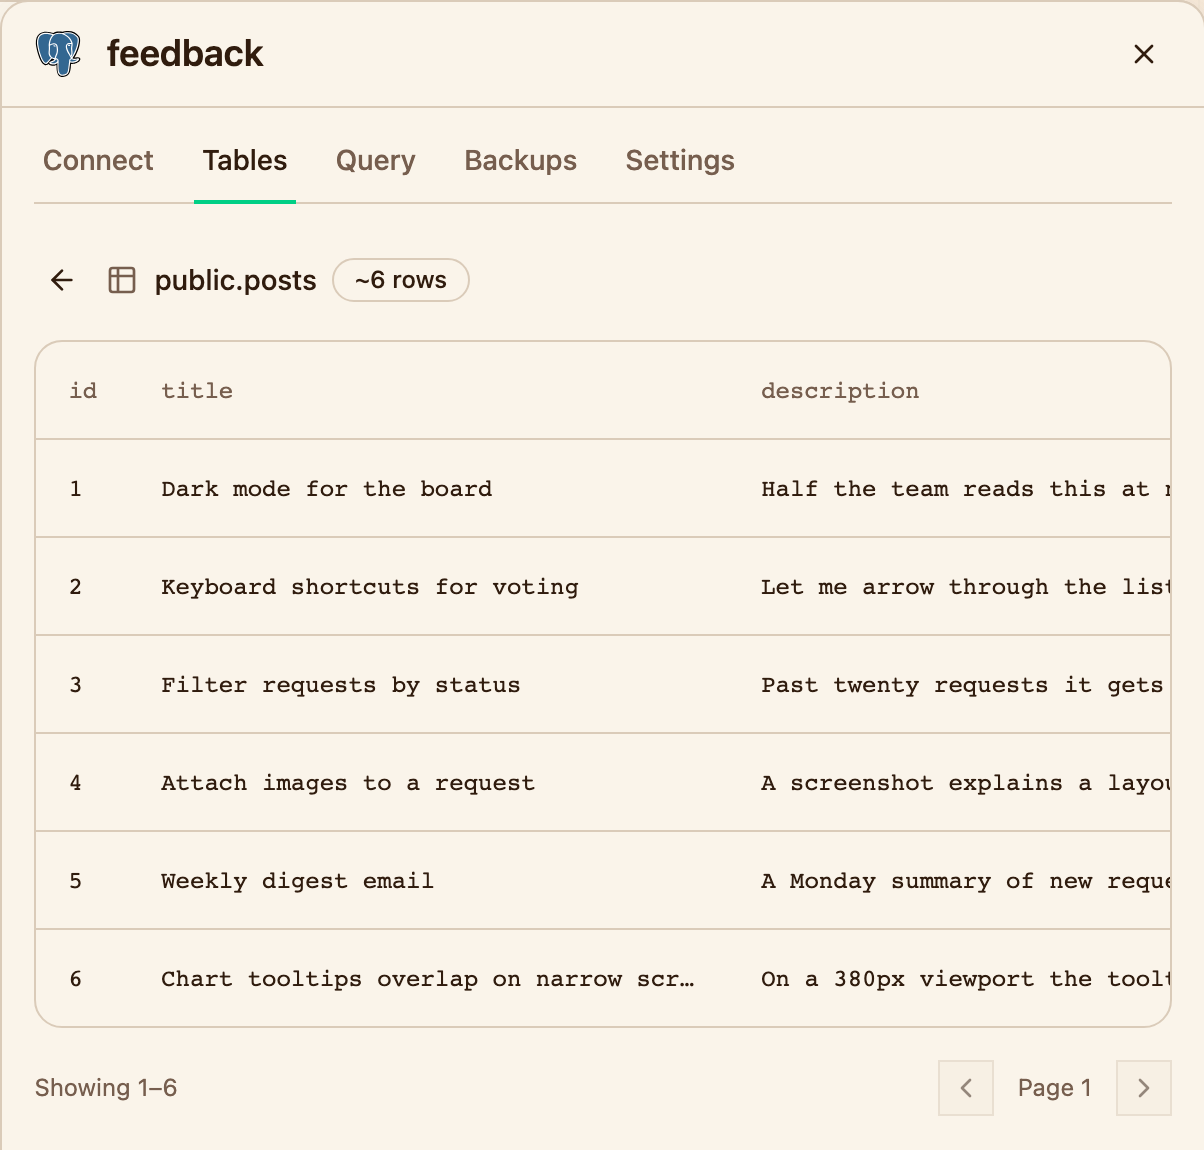
*The Tables tab reads straight from the running database.*
:::note
Vouch creates its table on the first request, so there's nothing to migrate here. Your own app can run its migrations at startup or as part of its start command.
:::
## Add an object storage bucket
Vouch can attach images to posts once it has somewhere to put them. On the canvas, click **Create**, choose **Bucket**, and name it `attachments`. That is an [object storage bucket](https://lucity.cloud/docs/object-storage): S3-compatible, private by default.
Back in the service's **Variables** tab, add five more variables, each linked to the **Object Storage: attachments** group:
| Variable | Linked to |
| ---------------------- | ----------------- |
| `S3_BUCKET` | `bucket` |
| `S3_ACCESS_KEY_ID` | `accessKeyId` |
| `S3_SECRET_ACCESS_KEY` | `secretAccessKey` |
| `S3_ENDPOINT` | `endpoint` |
| `S3_REGION` | `region` |
Save and reload the app. The feedback form now has an **Attach image** control. Submit a post with an image, then open the bucket node on the canvas and go to the **Files** tab. Your upload is sitting there under `uploads/`.
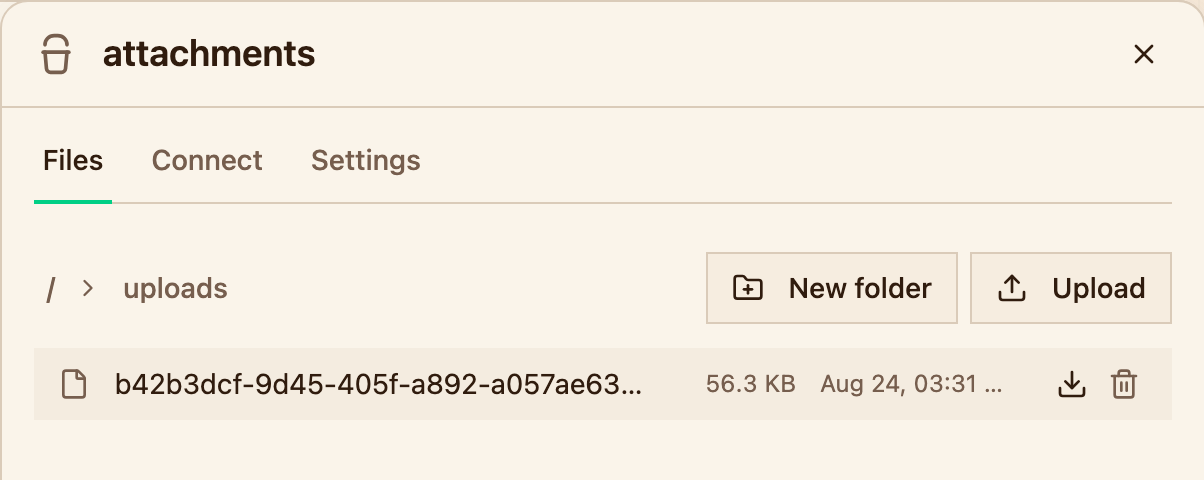
*Uploads land in the bucket under the `uploads/` prefix.*
::
## What you just built
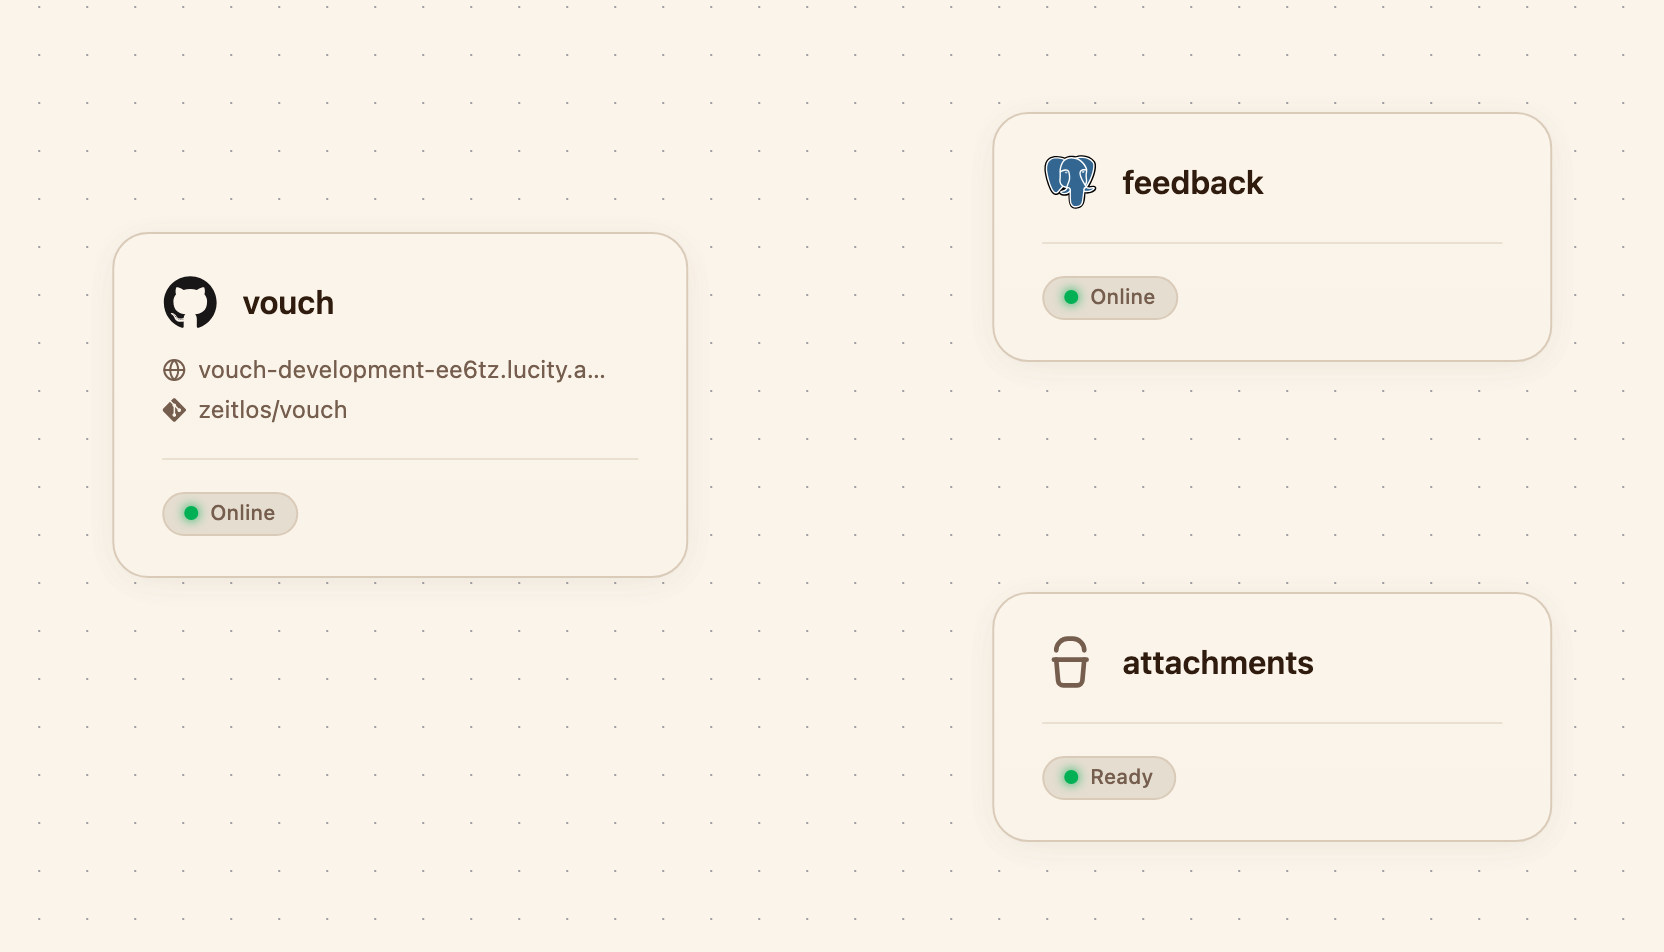
*One service, one database, one bucket, all in the development environment.*
Three resources, wired together:
- A Next.js service, built from source and served over HTTPS on its own domain
- A PostgreSQL database, provisioned and connected through a dynamic variable
- An S3-compatible bucket, holding user uploads
The service is the only piece with a public address. The database answers on a private hostname that exists inside the environment and nowhere else, and the bucket only opens up to the scoped credentials Lucity injects into the service. Nothing behind the app is reachable from the internet unless you decide to expose it.
You wrote no Dockerfile, no Helm values, and no CI config. And none of it is trapped here: everything above is a standard Helm release, a standard PostgreSQL cluster, and a standard bucket. If you ever want to run it yourself, [eject](https://lucity.cloud/docs/eject) hands you the whole setup.
# Deploy a Next.js app
Next.js needs no configuration to deploy here. Point Lucity at the repository and it recognizes the framework, runs your build script, and starts the server the way `next start` expects. What follows is the short list of things that are worth knowing anyway.
## Start from a fresh app
If you want something to try this on:
```bash
npx create-next-app@latest my-app
```
Push it to GitHub, then follow the [quickstart](https://lucity.cloud/docs/quickstart) to connect the repository. Nothing in the generated project needs changing first.
## What the builder does with it
The [build](https://lucity.cloud/docs/builds) runs `npm run build` and the service starts with `npm run start`, which is `next start` in a stock project. Two details follow from that:
- **Your `start` script is the contract.** Change it and Lucity uses whatever you changed it to. Delete it and detection falls back to the `main` field, then `index.js`.
- **The port comes from us.** Lucity sets `PORT` in the container and `next start` reads it, which is why the default project works untouched. If you define your own `PORT` [variable](https://lucity.cloud/docs/variables), yours wins and the service must listen on it.
Telemetry is switched off during the build, so you will not see the Next.js notice in your build logs.
You do not need `output: "standalone"`. That mode exists to shrink Docker images, and there is no Dockerfile here to shrink.
## Static exports are a different deployment
Set `output: "export"` in `next.config.ts` and the shape of the deployment changes: the build produces static files and Lucity serves them from a static web server instead of running Node. Faster, cheaper, and no server runtime, but API routes, server actions and anything else that runs per request stop working. Choose deliberately.
## Which variables are frozen
Anything prefixed `NEXT_PUBLIC_` is inlined into the JavaScript bundle when the build runs. Everything else is read at runtime by the server.
That difference matters here because [variables](https://lucity.cloud/docs/variables) normally take effect without a rebuild: change one, the service rolls out in seconds with the same image. A `NEXT_PUBLIC_` value is already baked into that image, so it will not change until the next build. Set public values before you build, and treat editing one as a code change.
Server-side variables have no such catch. A rotated database password reaches the running app on the next rollout.
## Reading a database from server components
Add a [PostgreSQL database](https://lucity.cloud/docs/postgres) and link `DATABASE_URL` to its `fqdn-uri`. From there it is ordinary Next.js: `pg`, Prisma, Drizzle, whichever client you like.
```ts
// app/page.tsx
import { Pool } from 'pg';
const pool = new Pool({ connectionString: process.env.DATABASE_URL });
export default async function Page() {
const { rows } = await pool.query('SELECT title FROM posts ORDER BY votes DESC');
return {rows.map(row => - {row.title}
)}
;
}
```
One thing to watch: pages that hit the database while being statically generated need that database reachable at build time. Either mark those routes dynamic, or fetch on the client.
For uploads, add a [bucket](https://lucity.cloud/docs/object-storage) and use the AWS SDK against the credentials Lucity injects. The local filesystem is not the place: it disappears with the container.
## When the build runs out of memory
`next build` is the memory-hungry part of a Next.js deployment. A large app can exhaust what the
build environment has, and the logs end abruptly with a killed process rather than an error.
Raising the service's memory does not help: that setting applies to the running container, while
builds run in a shared build environment with its own fixed ceiling. Reduce what the build needs
instead:
- Cap the Node heap so V8 collects rather than grows: set `NODE_OPTIONS` to
`--max-old-space-size=3072` as a [variable](https://lucity.cloud/docs/variables).
- Turn off production source maps in `next.config.ts` if you have them on.
- Split the work: precompute large data at request time or in a background job rather than
generating thousands of pages at build time.
## Next steps
- [Variables](https://lucity.cloud/docs/variables) for the build-time and runtime split
- [Domains](https://lucity.cloud/docs/domains) to put the app on a hostname you own
- [Deployments](https://lucity.cloud/docs/deployments) for what happens on each push
# Deploy a Nuxt app
Nuxt is the easiest of the JavaScript frameworks to deploy here, because its default build output is already a plain Node server. There is no platform preset to choose and no adapter to install.
```bash
npx nuxi@latest init my-app
```
Push that to GitHub, connect it as described in the [quickstart](https://lucity.cloud/docs/quickstart), and it runs. If you would rather not scaffold your own, [zeitlos/nuxt-example](https://github.com/zeitlos/nuxt-example) is exactly the above, deployed.
## The start command, and where it comes from
The [build](https://lucity.cloud/docs/builds) runs `npm run build`, which produces `.output/`. For the start command, detection looks for a `start` script first. A stock Nuxt project has none, so it falls through to the Nitro default:
```bash
node .output/server/index.mjs
```
That is the same command `nuxt preview` wraps, and it reads the `PORT` Lucity injects. Nothing to configure.
Add a `start` script and it wins. That is the hook to use if you want to run migrations before the server, or pass Node flags:
```json
{
"scripts": {
"start": "node --max-old-space-size=1024 .output/server/index.mjs"
}
}
```
::note
Commit your
`package-lock.json`
. A Nuxt project without one failed in our own build with
`npm error Cannot read properties of null (reading 'edgesOut')`
, an npm resolution failure that
never shows up locally because your
`node_modules`
is already there. The lockfile also makes the
build reproducible, which is the real reason to commit it.
::
## Leave the Nitro preset alone
Nitro can target Vercel, Netlify, Cloudflare Workers and a dozen other hosts, and every one of those presets produces output that only runs on that host. The default preset produces a Node server, which is what a container wants.
So: do not set `nitro.preset` in `nuxt.config.ts`, and remove it if you inherited a config that has one. That single line is the difference between a deployment that works anywhere and one that is pinned to a vendor. Lucity has nothing to add here, and that is the point.
## Runtime config and variables
Nuxt splits configuration in a way that maps neatly onto how [variables](https://lucity.cloud/docs/variables) behave.
`runtimeConfig` values are read at runtime, so they behave like any other variable: change one, the service rolls out in seconds with the same image and the new value is live.
`runtimeConfig.public` values are exposed to the browser and inlined during the build. Changing one needs a new build, not just a rollout. If a public value differs between environments, that means one build per environment, which is worth knowing before you rely on it.
The environment variable names follow Nuxt's convention: `NUXT_API_SECRET` fills `runtimeConfig.apiSecret`, and `NUXT_PUBLIC_SITE_URL` fills `runtimeConfig.public.siteUrl`.
## Server routes and a database
Nuxt server routes run in the same container, so a [PostgreSQL database](https://lucity.cloud/docs/postgres) is just a connection away. Link `DATABASE_URL` to the database's `fqdn-uri`, then use it from `server/api/`:
```ts
// server/api/posts.get.ts
import { Pool } from 'pg';
const pool = new Pool({ connectionString: process.env.DATABASE_URL });
export default defineEventHandler(async () => {
const { rows } = await pool.query('SELECT id, title FROM posts ORDER BY id DESC LIMIT 20');
return rows;
});
```
Uploads belong in a [bucket](https://lucity.cloud/docs/object-storage) rather than on the container's disk, which resets on every rollout.
## If you are building a static site
`nuxt generate` produces a static site instead of a server, and Lucity will happily serve it, but detection keys on the `build` script. Point your `build` script at `nuxt generate` and set a `start` script that serves `.output/public`, or keep the server build. Mixing the two, generating in the build and then starting a server, gives you the costs of both.
## Next steps
- [Variables](https://lucity.cloud/docs/variables) for the runtime and build-time split
- [PostgreSQL](https://lucity.cloud/docs/postgres) for the database behind your server routes
- [Deployments](https://lucity.cloud/docs/deployments) for what happens on each push
# Deploy a SvelteKit app
SvelteKit is the one framework in this list where a brand new project will not deploy as-is. Not because of anything Lucity does, but because the scaffold ships with `adapter-auto`, which produces nothing runnable outside the four hosts it knows about. Two small changes fix it permanently.
## The two changes
```bash
npx sv create my-app
cd my-app
npm install -D @sveltejs/adapter-node
```
Then swap the adapter. In current SvelteKit the adapter lives in `vite.config.ts`, not in `svelte.config.js` as older guides say:
```ts
// vite.config.ts
import adapter from '@sveltejs/adapter-node';
import { sveltekit } from '@sveltejs/kit/vite';
import { defineConfig } from 'vite';
export default defineConfig({
plugins: [sveltekit({ adapter: adapter() })],
});
```
And add a `start` script, because the adapter writes a server to `build/` but nothing runs it for you:
```json
{
"scripts": {
"start": "node build"
}
}
```
That is the whole setup. [zeitlos/sveltekit-example](https://github.com/zeitlos/sveltekit-example) is a minimal project with exactly these changes applied.
## Why it fails without them
Worth understanding, because the failure is quiet. With `adapter-auto` and no `start` script, the [build](https://lucity.cloud/docs/builds) succeeds: `npm run build` runs, files are produced, the image is pushed. Detection then looks for a way to start the app, finds no `start` script, no `main` field and no `index.js`, and derives an empty start command. The deployment has nothing to run.
You get a service that built cleanly and never becomes healthy, which is a more confusing outcome than a failed build. If you see that, this is almost always why.
With the two changes above, detection resolves the start command to `npm run start`, and `adapter-node` reads the `PORT` Lucity provides without further configuration.
## Environment variables
SvelteKit is strict about the difference, and the strictness is useful:
- `$env/static/private` is inlined at build time. Changing one of these values needs a rebuild.
- `$env/dynamic/private` is read at runtime from `process.env`. Changing one of these takes effect on the next rollout, in seconds.
- The `PUBLIC_` prefixed variants of both are exposed to the browser.
For anything that comes from a Lucity [dynamic variable](https://lucity.cloud/docs/variables), a database URL or bucket credentials, use `$env/dynamic/private`. Those values can change without your code changing, and a build-time import would freeze whatever was true when the image was made.
```ts
// src/routes/+page.server.ts
import { env } from '$env/dynamic/private';
import { Pool } from 'pg';
const pool = new Pool({ connectionString: env.DATABASE_URL });
export async function load() {
const { rows } = await pool.query('SELECT title FROM posts ORDER BY votes DESC LIMIT 10');
return { posts: rows };
}
```
## Prerendered routes need their data at build time
If a route is prerendered and it queries a [database](https://lucity.cloud/docs/postgres), that database has to be reachable while the build runs, not just at runtime. Either drop the prerender on those routes or load their data from a source available during the build.
## Next steps
- [Builds](https://lucity.cloud/docs/builds) for what the builder detects and how to override it
- [Services](https://lucity.cloud/docs/services) for health checks, resources and replicas
- [Variables](https://lucity.cloud/docs/variables) for the static and dynamic split
# Deploy an Astro site
An Astro project deploys as one of two quite different things, and your config decides which. Knowing which one you are getting is most of what there is to know.
```bash
npm create astro@latest my-site
```
Push it to GitHub and connect it as in the [quickstart](https://lucity.cloud/docs/quickstart), or fork [zeitlos/astro-example](https://github.com/zeitlos/astro-example), which is the minimal template unchanged.
## Static by default
A stock Astro project has no adapter and no `output: 'server'`. The [build](https://lucity.cloud/docs/builds) runs `npm run build`, produces `dist/`, and Lucity serves those files from a small static web server. No Node process runs at all.
That is the cheapest way to run a site here. It also means anything that executes per request is unavailable: no API endpoints, no server islands, no session handling, no reading a database on page load. Content is fixed at build time, so publishing new content means a new build.
If your `astro.config.mjs` sets `outDir`, the builder reads it rather than assuming `dist/`.
## Server rendering when you need it
Add the Node adapter and the deployment changes shape:
```bash
npx astro add node
```
That writes an adapter into your config and switches the build to produce a server. Detection then starts it through your `start` script, so make sure you have one:
```json
{
"scripts": {
"start": "node ./dist/server/entry.mjs"
}
}
```
The adapter reads the `PORT` Lucity injects. From that point on you have API routes, per-request rendering and everything else a server can do, and you are paying for a running container.
Use `output: 'static'` with selected pages marked `export const prerender = false`, or `output: 'server'` with the reverse, depending on which side the majority of your pages fall on.
::note
Adapters for other hosts,
`@astrojs/vercel`
and friends, produce output shaped for those platforms. On Lucity use
`@astrojs/node`
, which produces a plain Node server that runs anywhere.
::
## Content, images and data
A static Astro build talks to APIs at build time, so any database or CMS it reads must be reachable from the build. For a [PostgreSQL database](https://lucity.cloud/docs/postgres) on Lucity, that means the static path will not work: the database is only reachable from inside the environment at runtime. Use the Node adapter if your pages need live data.
Images processed by `astro:assets` are optimized during the build, which is memory-hungry on large sites. If a build dies without an error message, that is usually why.
User uploads belong in a [bucket](https://lucity.cloud/docs/object-storage) regardless of which mode you choose, since neither a static server nor a container keeps files between rollouts.
## Next steps
- [Builds](https://lucity.cloud/docs/builds) for detection and build caching
- [Domains](https://lucity.cloud/docs/domains) to put the site on your own hostname
- [Object storage](https://lucity.cloud/docs/object-storage) for anything users upload
# Deploy an Express API
Express has no build step, no framework conventions and no opinions about deployment, which means the platform has less to detect. Three things make an Express app deployable here, and all three are things you would want anyway.
## One: a start script
Detection looks for a `start` script in `package.json`, then a `main` field, then `index.js`. A project with none of those produces no start command, and the service will build but never run.
```json
{
"scripts": {
"start": "node index.js"
}
}
```
## Two: listen on the port you are given
Lucity sets `PORT` in the container. Read it, and keep a local default so `npm run dev` still works:
```js
import express from 'express';
const app = express();
const port = process.env.PORT || 3000;
app.get('/', (request, response) => {
response.json({ message: 'Deployed on Lucity' });
});
app.listen(port, () => console.log(`listening on ${port}`));
```
A hardcoded port is the single most common reason an Express service never becomes healthy: the process runs, the platform checks the port it assigned, nothing answers.
## Three: a health check that means something
By default the platform opens a TCP connection to your port and calls that healthy. That catches a crashed process, but not an app that is up and failing every request.
Add a route that answers cheaply, then point the service's health check at it in [service settings](https://lucity.cloud/docs/services):
```js
app.get('/healthz', (request, response) => response.status(200).send('ok'));
```
Keep it honest but light. Checking the database on every probe turns a slow query into a restart loop; checking nothing at all means a broken app stays in rotation.
[zeitlos/express-example](https://github.com/zeitlos/express-example) is these three things and nothing else.
## Connecting a database
Add a [PostgreSQL database](https://lucity.cloud/docs/postgres) and link `DATABASE_URL` to its `fqdn-uri`:
```js
import { Pool } from 'pg';
const pool = new Pool({ connectionString: process.env.DATABASE_URL });
```
One pool per process, created at startup, not per request. With more than one replica, remember that each has its own pool: the connection limit that matters is pool size times replicas.
Sessions and rate limiting want a [key-value store](https://lucity.cloud/docs/redis) rather than in-memory state, for the same reason. Anything held in memory belongs to one replica and disappears when it rolls.
## Migrations
There is no framework convention here, so pick one and put it in the start script:
```json
{
"scripts": {
"start": "node migrate.js && node index.js"
}
}
```
Running with every start means every replica attempts it, so the tool you use has to be safe to run concurrently. Most are; check yours.
## Next steps
- [Services](https://lucity.cloud/docs/services) for health checks, resources and replicas
- [Key-value store](https://lucity.cloud/docs/redis) for sessions, caching and queues
- [Logs](https://lucity.cloud/docs/logs) for what your app prints in production
# Deploy a FastAPI service
FastAPI deploys here without configuration when your project matches the layout detection expects, and needs exactly one setting when it does not. Most real projects do not match, so this guide starts there.
## What detection looks for
Three things have to be true for a start command to be derived automatically:
1. `requirements.txt` (or a `pyproject.toml`) exists, so the project reads as Python.
2. `uvicorn` is among the dependencies.
3. `main.py` sits at the repository root, with the FastAPI instance named `app`.
When all three hold, the [build](https://lucity.cloud/docs/builds) produces this:
```bash
uvicorn main:app --host 0.0.0.0 --port ${PORT:-8000}
```
[zeitlos/fastapi-example](https://github.com/zeitlos/fastapi-example) is that layout in three files:
```bash
mkdir my-api && cd my-api
printf 'fastapi\nuvicorn[standard]\n' > requirements.txt
```
```python
# main.py
from fastapi import FastAPI
app = FastAPI()
@app.get("/")
def read_root():
return {"message": "Deployed on Lucity"}
```
## When your app is not at the root
The common production layout puts the app in a package, `app/main.py` or `src/api/main.py`, and adds a `create_app()` factory. Detection does not find `main.py` at the root, so it derives nothing and the service has no command to run.
Set the start command yourself in the service settings, and it is used verbatim:
```bash
uvicorn app.main:app --host 0.0.0.0 --port ${PORT:-8000}
```
That is not a workaround. Once you have set it, it survives every future build, and you control the worker count, the log level and everything else uvicorn accepts.
## Workers, and when to add them
Uvicorn runs a single process by default. That is usually the right choice here: to add capacity, raise the replica count on the [service](https://lucity.cloud/docs/services) and let the platform spread traffic across containers that can be scheduled on different nodes.
Workers inside one container still make sense when your app is CPU-bound in Python and you want to use a container's full CPU allocation:
```bash
uvicorn app.main:app --host 0.0.0.0 --port ${PORT:-8000} --workers 4
```
Match the worker count to the CPU you allocated, not to the node's core count.
## Async database access
Add a [PostgreSQL database](https://lucity.cloud/docs/postgres) and link `DATABASE_URL` to its `fqdn-uri`. FastAPI's concurrency model means an async driver is worth having:
```python
import os
from sqlalchemy.ext.asyncio import async_sessionmaker, create_async_engine
url = os.environ["DATABASE_URL"].replace("postgresql://", "postgresql+asyncpg://", 1)
engine = create_async_engine(url, pool_size=5, max_overflow=5)
session = async_sessionmaker(engine, expire_on_commit=False)
```
The dynamic variable gives you a `postgresql://` URL, which SQLAlchemy reads as the sync driver, hence the rewrite. Keep the pool small and remember it is per replica.
## Migrations belong in the start command
Nothing runs Alembic for you. Chain it ahead of the server so a rollout cannot serve traffic against an old schema:
```bash
alembic upgrade head && uvicorn app.main:app --host 0.0.0.0 --port ${PORT:-8000}
```
Every replica will run it on start. Alembic handles that safely, but a long migration delays every start, so run big ones separately.
## Next steps
- [Services](https://lucity.cloud/docs/services) for replicas, resources and health checks
- [PostgreSQL](https://lucity.cloud/docs/postgres) for connection details and backups
- [Variables](https://lucity.cloud/docs/variables) for configuration and secrets
# Deploy a Django project
Django deploys here with one command derived automatically and two things you have to decide yourself: where static files come from, and which hostnames the project trusts. Everything else is the framework working as it always does.
## Start from a fresh project
```bash
python -m venv .venv && source .venv/bin/activate
pip install django gunicorn
django-admin startproject liftoff .
pip freeze > requirements.txt
```
`requirements.txt` matters more than it looks: it is how the [builder](https://lucity.cloud/docs/builds) recognizes the project as Python and finds `gunicorn`. Push the result to GitHub and connect it as described in the [quickstart](https://lucity.cloud/docs/quickstart).
## The command Lucity derives
Detection keys on `manage.py` plus Django in your dependencies. The start command it writes reads your `WSGI_APPLICATION` setting and comes out as:
```bash
python manage.py migrate && gunicorn --bind 0.0.0.0:${PORT:-8000} liftoff.wsgi:application
```
Read that literally, because two consequences catch people out.
**Migrations run on every start.** Not on every deploy: on every container start, including a restart and each replica coming up. Django's migrate is safe to repeat, so this is usually what you want. It also means a broken migration blocks the rollout instead of quietly leaving the schema behind.
**No `WSGI_APPLICATION`, no start command.** Remove or rename that setting and detection produces nothing, and the service has nowhere to start from. Either keep the setting, or set your own start command in the service settings.
If you want something else entirely, a worker pool tuned differently or `collectstatic` in the chain, override the start command and Lucity uses yours verbatim.
## Static files are not handled for you
Nothing runs `collectstatic`. A project deployed as-is serves its own views correctly and 404s on `/static/*` in production, which is a confusing failure because it works locally with `DEBUG = True`.
The simplest fix is WhiteNoise, which serves static files from the app process:
```bash
pip install whitenoise
```
```python
# settings.py
MIDDLEWARE = [
'django.middleware.security.SecurityMiddleware',
'whitenoise.middleware.WhiteNoiseMiddleware',
# ...
]
STATIC_ROOT = BASE_DIR / 'staticfiles'
STORAGES = {
'staticfiles': {'BACKEND': 'whitenoise.storage.CompressedManifestStaticFilesStorage'},
}
```
Then put the collection step in your start command, before gunicorn:
```bash
python manage.py migrate && python manage.py collectstatic --noinput && gunicorn --bind 0.0.0.0:${PORT:-8000} liftoff.wsgi:application
```
For user uploads, WhiteNoise is the wrong tool. Those belong in a [bucket](https://lucity.cloud/docs/object-storage), configured through `django-storages` with the S3 credentials Lucity injects. The container filesystem does not survive a rollout.
## Let Django accept its own domain
Generate a [domain](https://lucity.cloud/docs/domains) and Django will reject requests to it until the hostname is in `ALLOWED_HOSTS`. Forms will also fail CSRF validation until the origin is trusted.
Read both from the environment rather than hardcoding, so the same image works in every environment:
```python
ALLOWED_HOSTS = os.environ.get('ALLOWED_HOSTS', '').split(',')
CSRF_TRUSTED_ORIGINS = [f'https://{host}' for host in ALLOWED_HOSTS if host]
```
Then set `ALLOWED_HOSTS` to your generated hostname. Add the custom domain to the same variable when you point one at the service.
## Connecting the database
Add a [PostgreSQL database](https://lucity.cloud/docs/postgres), then link `DATABASE_URL` to its `fqdn-uri` and let `dj-database-url` do the parsing:
```python
import dj_database_url
DATABASES = {'default': dj_database_url.config(conn_max_age=600)}
```
`psycopg[binary]` belongs in your requirements alongside it. Because the value is a [dynamic variable](https://lucity.cloud/docs/variables) rather than a pasted string, a rotated password reaches the app without you editing anything.
## Before you call it production
- `DEBUG` should read from the environment and default to off. A stack trace on a public URL is a bad day.
- `SECRET_KEY` belongs in a variable, not in `settings.py`.
- `SESSION_COOKIE_SECURE` and `CSRF_COOKIE_SECURE` should be on. Everything Lucity serves is HTTPS, so there is no cost to it. Run `python manage.py check --deploy` to see the rest of the list.
- Long migrations block the rollout. For a big one, run it once against the database and deploy after.
## Next steps
- [PostgreSQL](https://lucity.cloud/docs/postgres) for backups, the query console and connection details
- [Object storage](https://lucity.cloud/docs/object-storage) for media uploads
- [Services](https://lucity.cloud/docs/services) for resources, health checks and replicas
# Deploy a Laravel application
A Laravel deployment does more work on your behalf than most. Composer and npm both run, the framework caches get warmed, migrations run, and a web server is configured and started. This guide walks through that lifecycle so you know which parts are yours to control.
## Start from a fresh app
```bash
composer create-project laravel/laravel my-app
```
Push it to GitHub and connect it as in the [quickstart](https://lucity.cloud/docs/quickstart). A stock Laravel app needs no changes to build, though it will not boot until it has an `APP_KEY`, which is the first variable below.
## During the build
The [build](https://lucity.cloud/docs/builds) recognizes the project from `composer.json` and runs, in order:
1. `composer install --optimize-autoloader`, with the Composer cache reused between builds.
2. Your frontend build, if there is a `package.json`. Laravel's default Vite setup is picked up without configuration.
3. `mkdir` for the `storage/` and `bootstrap/cache` directories, so a clean checkout has somewhere to write.
4. `php artisan config:cache`, `event:cache`, `route:cache` and `view:cache`.
Anything requiring PHP extensions beyond the defaults belongs in `composer.json`, where the builder reads them.
## When the container starts
The image starts a script rather than a bare server, and that script does three things before serving traffic:
```bash
php artisan migrate --force
php artisan storage:link
php artisan optimize:clear && php artisan optimize
```
**Migrations run on every start**, not just on deploy. Repeat runs are harmless, but a failing migration keeps the container from serving. Set `RAILPACK_SKIP_MIGRATIONS` to `true` as a [variable](https://lucity.cloud/docs/variables) if you would rather run them yourself.
**The caches are rebuilt at boot**, which is the detail that saves you. Config was cached during the build, when your runtime variables were not necessarily final. Because the start script clears and re-optimizes, the values that end up in the running app are the ones set on the service.
Then FrankenPHP serves the application on the port Lucity provides. There is no nginx config, no php-fpm pool and no `Procfile` to write.
## The variables it needs
| Variable | Value |
| ----------------------------------------------------------------- | ------------------------------------------------------------------------------------- |
| `APP_KEY` | `base64:...` from `php artisan key:generate --show`. Set it once and keep it. |
| `APP_URL` | Your generated or custom [domain](https://lucity.cloud/docs/domains). |
| `APP_ENV` / `APP_DEBUG` | `production` and `false`. |
| `DB_CONNECTION` | `pgsql` |
| `DB_HOST`, `DB_PORT`, `DB_DATABASE`, `DB_USERNAME`, `DB_PASSWORD` | Linked to the matching values on your [database](https://lucity.cloud/docs/postgres). |
`APP_KEY` deserves two warnings. It encrypts sessions and anything you have encrypted at rest, so generating a fresh one on each deploy logs everyone out and makes old ciphertext unreadable. Generate it once, store it as a variable, leave it alone.
The second warning is about how its absence looks. On this stack a missing `APP_KEY` does not produce Laravel's familiar key screen. The request returns a 500 and the log shows `Cannot modify header information: headers already sent` from Symfony's response handling, because the exception page fails while rendering itself. If you see that error on a fresh deployment, check the variable before you go looking for a header bug.
The database values map one to one onto the values a Lucity database exposes: `host`, `port`, `dbname`, `user`, `password`. Link each rather than pasting, and credential rotation stops being an incident.
## Files go in a bucket, not on disk
`storage:link` runs at boot, which makes `public/storage` work, but that disk is part of the container and disappears with it. Uploads that need to survive a deploy belong in a [bucket](https://lucity.cloud/docs/object-storage):
```text
FILESYSTEM_DISK=s3
AWS_ACCESS_KEY_ID -> accessKeyId
AWS_SECRET_ACCESS_KEY -> secretAccessKey
AWS_BUCKET -> bucket
AWS_ENDPOINT -> endpoint
AWS_DEFAULT_REGION -> region
AWS_USE_PATH_STYLE_ENDPOINT=true
```
Install `league/flysystem-aws-s3-v3` and `Storage::disk('s3')` behaves as usual.
## Queues get their own service
A queue worker is a long-running process with a different command, so it is a second [service](https://lucity.cloud/docs/services) in the same project, pointed at the same repository, with its start command set to:
```bash
php artisan queue:work --tries=3 --max-time=3600
```
Give it the same variables as the web service so it reaches the same database and the same [key-value store](https://lucity.cloud/docs/redis), and leave its port unset: it serves no traffic and needs no domain. Scale it by raising replicas on that service alone.
The scheduler works the same way, with `php artisan schedule:work` as its command.
## Next steps
- [Key-value store](https://lucity.cloud/docs/redis) for queues, cache and sessions
- [Object storage](https://lucity.cloud/docs/object-storage) for uploads
- [Deployments](https://lucity.cloud/docs/deployments) for rollout behavior and rollbacks
# Deploy a Go service
Go is the least eventful deployment on the platform. The [build](https://lucity.cloud/docs/builds) compiles your module and the image runs the resulting binary. There is no runtime to install, no package manager at boot and no framework conventions to satisfy.
```bash
mkdir my-service && cd my-service
go mod init github.com/you/my-service
```
Write a `main.go` that reads `PORT`, push it, and connect the repository as in the [quickstart](https://lucity.cloud/docs/quickstart). [zeitlos/go-example](https://github.com/zeitlos/go-example) is the whole thing in one file:
```go
package main
import (
"log"
"net/http"
"os"
)
func main() {
port := os.Getenv("PORT")
if port == "" {
port = "8080"
}
http.HandleFunc("/", func(w http.ResponseWriter, r *http.Request) {
w.Write([]byte("Deployed on Lucity"))
})
log.Fatal(http.ListenAndServe(":"+port, nil))
}
```
## What the build does
Detection keys on `go.mod`, a Go workspace, or a `main.go` at the root. The build compiles with `go build` and the service starts the binary it produced. The Go toolchain version comes from the `go` directive in your `go.mod`, so bumping Go is a one-line change in the file that already declares it.
Because the runtime image carries a binary rather than a toolchain, Go services start fast and use very little memory. A service that idles at 300MB in a JavaScript runtime often idles under 20MB here, which is worth remembering when you set resources.
## Repositories with more than one binary
A `cmd/` directory with several programs is the common case that needs a decision, because only one of them is your service. There is no build command field in the dashboard, but [variables](https://lucity.cloud/docs/variables) reach the builder, and the builder reads one that replaces the compile step:
| Variable | Value |
| -------------------- | --------------------------- |
| `RAILPACK_BUILD_CMD` | `go build -o out ./cmd/api` |
Keep the output name as `out`: the derived start command runs `./out`, so a different name leaves nothing to start. Set that variable and the build compiles the package you named instead of guessing.
Deploy the other binaries as their own [services](https://lucity.cloud/docs/services) from the same repository, each with its own `RAILPACK_BUILD_CMD`. A worker and an API sharing a module, deployed separately and scaled separately, is a natural fit for the way projects work here.
## Health checks earn their keep
The default check opens a TCP connection to your port. A Go service that has crashed stops accepting connections, so this catches the obvious failure. It does not catch a service whose database pool is exhausted while the listener stays open.
Add an endpoint that answers what you actually care about, then point the [service](https://lucity.cloud/docs/services) health check at it:
```go
http.HandleFunc("/healthz", func(w http.ResponseWriter, r *http.Request) {
if err := db.PingContext(r.Context()); err != nil {
http.Error(w, "database unreachable", http.StatusServiceUnavailable)
return
}
w.Write([]byte("ok"))
})
```
Keep the check cheap. It runs on a schedule, and a slow check under load turns into a restart under load.
## Connecting a database
Add a [PostgreSQL database](https://lucity.cloud/docs/postgres) and link `DATABASE_URL` to its `fqdn-uri`:
```go
pool, err := pgxpool.New(ctx, os.Getenv("DATABASE_URL"))
```
Set `MaxConns` deliberately. The limit that matters is per replica, so four replicas with a pool of 25 each is 100 connections against a database that may allow fewer.
## Shutting down cleanly
Rollouts send `SIGTERM` and then wait before killing the container. Handling it means in-flight requests finish instead of failing:
```go
ctx, stop := signal.NotifyContext(context.Background(), os.Interrupt, syscall.SIGTERM)
defer stop()
go func() { log.Fatal(server.ListenAndServe()) }()
<-ctx.Done()
shutdownCtx, cancel := context.WithTimeout(context.Background(), 10*time.Second)
defer cancel()
server.Shutdown(shutdownCtx)
```
Without it, every deploy drops whatever was in flight. With it, deploys are invisible to users.
## Next steps
- [Services](https://lucity.cloud/docs/services) for resources, replicas and health checks
- [Deployments](https://lucity.cloud/docs/deployments) for rollout and rollback behavior
- [Metrics](https://lucity.cloud/docs/metrics) to see how little memory it actually uses
# Deploy your framework
Lucity builds from source, so most apps deploy without a Dockerfile and without any framework-specific configuration. These guides cover the parts that are worth knowing per framework: what the builder detects, the start command it derives, and how to wire a database or a bucket into it.
:guide-cards
Working with something that isn't here? The [quickstart](https://lucity.cloud/docs/quickstart) applies to any language Railpack supports, and a [prebuilt container image](https://lucity.cloud/docs/services) works when you would rather build it yourself.
# Services
A service is one running program. This can be a web app, an API, a background worker, a queue consumer, or a self-hosted piece of software you didn't write. It lives in exactly one [environment](https://lucity.cloud/docs/environments) and consists of its own image, its own variables, and its own compute allocation.
Services are the core of Lucity: everything else in a project exists to be used by services. Databases, buckets, key-value stores and volumes are all things you connect to a service.
Each service has a name consisting of 2 to 16 characters, lowercase letters, digits and hyphens. That name shows up in the private hostname, the generated domain, and the logs, so pick something you'll still recognize in six months. You cannot change it later.
## Source builds and prebuilt images
Every service is either built from a repository or pulled from a registry. You choose which one when you create the service, and that choice determines most of what follows.
| | From a repository | From an image |
| --------------------------------------- | ---------------------------------------------------------------- | ------------------------------------- |
| Where the image comes from | Lucity [builds it from source](https://lucity.cloud/docs/builds) | Pulled from a public registry |
| Tracked branch, auto-deploy, CI deploys | Yes | No |
| Rebuild and redeploy | Yes | No |
| Default port | 8080 | Lowest TCP `EXPOSE` port in the image |
| Default start command | Detected by the builder | The image's entrypoint and command |
| Run-as user | Image default | Configurable |
| Vulnerability scanning | Yes | No |
Building from a repository is the common case, and the one the [quickstart](https://lucity.cloud/docs/quickstart) walks through. Lucity reads the repository, works out what it is, builds a container image, and deploys it. When you push to the tracked branch, all of that happens again.
Deploying an image is for software you are not building yourself, such as Ghost, MySQL, Grafana, or an internal image someone else publishes. You can pick one from the Docker Hub search in the dashboard, or type any public image reference such as `ghcr.io/owner/thing:1.4`.
Be aware that an image reference without a tag is treated as `latest`, which is commonly used as a moving tag. That means the service might pull a newer image when an instance starts, if the maintainer has published one in the meantime. Lucity only pulls an image when the machine running the instance does not already have it, so this happens when an instance lands somewhere new rather than on every restart. Pin an exact version when you want to know what is running.
::note
The image reference is fixed when the service is created. There is no way to change the tag afterwards, so moving to a new version means adding a service on the new image and removing the old one. Images from private registries are not supported yet.
::
## Ports
A service can expose a port. If it does, the service is reachable inside its environment by default, and it can optionally also be assigned a domain. Some services, such as internal APIs, don't need a public domain at all, since their clients reach them from within the environment.
A service with no port configured can be the right choice for something like a worker that only reads from a queue or an external API.
Services built from a repository default to port **8080**, and Lucity sets two variables in the container to match:
| Variable | Value |
| -------- | ---------------- |
| `PORT` | The service port |
| `HOST` | `0.0.0.0` |
Most frameworks read `PORT` without being asked, which is why a stock application usually works untouched. Binding to `localhost` instead of `0.0.0.0` is the classic way to end up with a container that looks healthy while nothing can actually reach it.
::note
If you define
`PORT`
or
`HOST`
yourself as a
[variable](https://lucity.cloud/docs/variables)
, your value wins and Lucity stops injecting its own.
::
Services created from an image take the lowest TCP port that the image declares with `EXPOSE`. Ghost lands on 2368, MySQL on 3306, and an image that exposes nothing at all gets no port.
You can change the port under **Settings** → **Networking** → **Port**. Clearing the field turns the service into a service without a port, which removes its cluster address, its domains, and its health checks.
## Start command
Services built from a repository get a start command from the builder, derived from the same signals it used to detect the framework: an npm `start` script, a Python entrypoint, or the binary it just compiled. Services created from an image use that image's entrypoint and command.
You can override it under **Settings** → **Deploy** → **Custom Start Command**. The placeholder shows the detected default, so you can always see what you are replacing.
The command runs through `/bin/sh -c`, so shell syntax works: variable expansion, `&&`, and semicolons all behave as you would expect.
## Graceful shutdown
When a [deployment](https://lucity.cloud/docs/deployments) replaces an instance, the old one is asked to stop rather than killed outright. Your process receives `SIGTERM` and has [about twenty seconds](https://lucity.cloud/docs/deployments#rollouts) to finish what it is doing and exit on its own. Ignore the signal and it is killed when the time runs out, dropping whatever was still in flight.
Most frameworks handle this for you. A custom start command is what usually gets in the way, since the command runs through a shell and the shell is the process that receives the signal. Prefix the real process with `exec` so that it replaces the shell:
```bash
npx prisma migrate deploy && exec node server.js
```
Without `exec`, the shell takes the signal and your application only finds out when it is killed. With it, the application gets the full grace period.
## Health checks
By default, Lucity opens a TCP connection to the service port every 5 seconds with a 3 second timeout. An instance is considered ready after one success, and taken out of rotation after three consecutive failures. This needs no configuration and it is the right answer for most services: if the socket accepts a connection, the application is listening.
It is the wrong answer when your application accepts connections before it can actually serve them. An application that binds its port and then spends 40 seconds warming a cache will receive traffic it cannot answer. That is what the HTTP check is for, and you can turn it on under **Settings** → **Networking** → **Health Check**:
| Field | Default | What it does |
| -------------- | ------------ | -------------------------------------------------------- |
| Path | Required | The path to request, for example `/health/ready` |
| Port | Service port | Useful when health lives on a separate admin port |
| Delay | 0s | How long to wait before the first check |
| Period | 5s | How often to check |
| Timeout | 3s | How long to wait for a response |
| Failures | 3 | Consecutive failures before the instance leaves rotation |
| Startup budget | 0 | Extra failures tolerated while the instance is starting |
Any response from 200 to 399 counts as healthy.
The startup budget is the setting worth understanding. The steady-state values have to stay tight, because that is how a wedged instance gets pulled out of rotation quickly, but a slow boot needs the opposite. The startup budget separates the two concerns: a period of 5 seconds with a startup budget of 24 gives a new instance two minutes to come up, and as soon as it passes once, the strict steady-state rules take over.
::note
Lucity uses readiness checks rather than liveness checks. A failing check takes an instance out of rotation, it does not kill the container.
::
If a new instance never passes its check, the rollout is reported as failed and the old instance keeps serving. See [deployments](https://lucity.cloud/docs/deployments) for what that looks like and what to do about it.
## CPU and memory
Giving a service more CPU and memory is what is commonly called vertical scaling: the instances you already run each get more room to work in.
Under **Settings** → **Compute** you pick a CPU and a memory size, and both apply per instance:
- **CPU**: 0.25, 0.5, 1, 2 or 4 vCPU, defaulting to 0.5.
- **Memory**: 256 MB up to 16 GB, defaulting to 512 MB.
Both values are limits, and the two behave differently once you hit the ceiling. Exceeding the CPU limit means your process is throttled and simply gets slower. Exceeding the memory limit means the kernel kills it, and the instance restarts with `OOM killed` recorded on the deployment. If a service dies at exactly the same point in its workload every time, that is the first thing to check.
Saving new values rolls the service out without a rebuild. See [configuration changes](https://lucity.cloud/docs/deployments#configuration-changes).
::note
Each environment has a total budget of 32 vCPU and 64 GB across everything inside it. That is plenty of room for a normal project, and a backstop against a runaway autoscaler.
::
## Replicas and autoscaling
Running several copies of a service is what is commonly called horizontal scaling. Each replica is its own container and gets the full [CPU and memory](https://lucity.cloud/#cpu-and-memory) limits you picked, so four replicas at 1 vCPU each have a vCPU to themselves.
A service runs between 1 and 20 instances. You can set the number yourself under **Settings** → **Scaling** → **Replicas**, or hand the decision to the autoscaler.
Adding or removing replicas does not touch the instances that are already running. Existing instances keep serving, new ones join them, and traffic spreads across whatever is ready.
Autoscaling watches CPU usage and adjusts the count for you. You set a minimum, a maximum, and a CPU percentage to aim for, and the autoscaler stays inside that range.
Scaling up reacts within about 30 seconds. Scaling down waits for 5 minutes of sustained calm and then removes at most one instance per minute, so that a short dip in traffic does not take away capacity you are about to need again.
Running more than one instance assumes that the service is stateless: no session state held in process memory, no uploads written to the container filesystem, and no assumption that a scheduled job runs on one particular machine. Move that state into [PostgreSQL](https://lucity.cloud/docs/postgres), a [key-value store](https://lucity.cloud/docs/redis) or a [bucket](https://lucity.cloud/docs/object-storage) before you scale out. Otherwise the requests that reach the instance holding the state work, and the rest do not.
::note
This is also why a service with a mounted volume is pinned to a single replica. A volume is one disk and can only be attached to one machine at a time, so instances cannot share it. See
[one volume, one service](https://lucity.cloud/docs/volumes#one-volume-one-service)
.
::
## Networking
Every service with a port gets a private DNS name inside its environment, reachable on the same port the container listens on. From another service in the same environment the short name `lucity-app-` is enough, so a [variable](https://lucity.cloud/docs/variables) pointing one service at another can be as short as `http://lucity-app-api:8080`.
The full name is shown, ready to copy, under **Settings** → **Networking** → **Private Networking**, and it has this shape:
```text
lucity-app-..svc.cluster.local
```
This address is not reachable from the internet, and nothing outside the environment can reach it either. Your production database is not reachable from your staging application, in the same way that it is not reachable from someone else's workspace.
All services can reach the public internet, call third-party APIs, and pull from package registries.
To expose a service to the world, give it a domain. That is one click for a platform domain with a certificate included, or a few DNS records for a hostname you own. See [domains](https://lucity.cloud/docs/domains).
## Volume mounts
Lucity service containers are temporary. When you deploy a new version of your app, the old containers are deleted once the new one is ready. This means that files written to the filesystem are gone after a rollout.
Most of the time that is fine, and the answer is a [bucket](https://lucity.cloud/docs/object-storage) for uploads and a [database](https://lucity.cloud/docs/postgres) for data. Sometimes it is not, and you need a disk that outlives the container: software that insists on a data directory, a self-hosted tool with a content folder, or a database you are running yourself.
To get one, create a [volume](https://lucity.cloud/docs/volumes) in the environment and mount it on a service at a path. Attaching a volume constrains the service in two ways: it runs as a single instance and cannot autoscale, because [a disk belongs to one instance](https://lucity.cloud/docs/volumes#one-volume-one-service), and every deploy stops it before starting the replacement instead of handing over cleanly, so there is a [short gap each time](https://lucity.cloud/docs/volumes#rollout-downtime).
## Under the hood
Under the hood, each Lucity service is a Kubernetes Deployment, a Service, an optional HTTPRoute, and a Secret holding its variables, all rendered from Helm values that Lucity computes for you. Containers run with no privilege escalation, all capabilities dropped, a seccomp profile applied, and no service account token mounted.
There is no proprietary runtime object anywhere in that list, which is what makes [ejecting](https://lucity.cloud/docs/eject) work. You get the chart and the values, and the same service keeps running on your own infrastructure.
## Next steps
- [Variables](https://lucity.cloud/docs/variables) to configure a service and connect it to a database or bucket
- [Deployments](https://lucity.cloud/docs/deployments) for what happens on each deploy
- [Domains](https://lucity.cloud/docs/domains) to put a service on a hostname you own
- [Metrics](https://lucity.cloud/docs/metrics) to see what a service actually uses before you resize it
# Deployments
A deployment is everything that happens between a commit and a running container: Lucity builds an image from your source, points the service at that image, and replaces the running instances with new ones.
You can watch all of it from the **Deployments** tab of a service, which lists every deployment with its current state and its logs.
## Deployment steps
Every deployment moves through the same four steps, and the dashboard shows them in order:
| Step | What happens |
| ----------- | -------------------------------------------------------------------------------------------------------------------- |
| **Build** | Your source is turned into a container image. See [builds](https://lucity.cloud/docs/builds) for what that involves. |
| **Secrets** | The commit is scanned for leaked credentials. |
| **Deploy** | Once the build succeeds, the service is pointed at the new image. |
| **Rollout** | The new instances start and the old ones are retired. |
Build and Secrets run at the same time. The secret scan never blocks a deployment: it reports what it found and the deploy carries on regardless. Findings are still worth acting on, because a credential that reached git history stays there until you rotate it.
Deploy waits for the build. If the build fails, the deploy stops and nothing changes, so the version that was already running keeps running. The same is true of every failure before the rollout starts: a broken deployment cannot take down a working service.
A build gets 30 minutes and is not retried. If it runs out of time, the deployment fails and you try again.
## Triggering a deployment
There are different ways to start a deployment.
Each service tracks one branch, set under **Settings** → **Source**. Unless you say otherwise, a deployment builds the latest commit on that branch.
::tabs
:::tabs-item{label="Dashboard"}
Open the service, go to the **Deployments** tab, and click **Deploy**. That builds the latest commit on the tracked branch, and the dashboard offers no way to pick a different one, so change the tracked branch first if you need another.
Each of the four steps has its own logs, streaming while the step runs, so you can watch a build compile and a rollout come up without leaving the panel.
:::
:::tabs-item{label="Git push"}
Every push to the tracked branch deploys the service. There is no workflow file and nothing to configure: this is auto-deploy, and services created in the development environment start with it switched on. You can toggle it under **Settings** → **Source**. Pushes to any other branch are ignored.
One push deploys every service that builds from that repository and tracks that branch with auto-deploy enabled, so a single commit can roll out several services at once. That is what you want when the same codebase runs as more than one service, such as a web service and a worker started with different commands.
:::
:::tabs-item{label="CLI"}
Install the CLI and sign in first: see [CLI](https://lucity.cloud/docs/cli) for both.
```bash
lucity deploy myproject/production/web --ref main --wait --timeout 30m
```
Only the service is required. The rest are optional:
- `--ref` builds a specific commit, branch or tag instead of the tracked branch. It can be anything in the repository, not just something on the branch the service tracks.
- `--wait` blocks until the deployment is live or failed, and exits non-zero on failure, which is what makes it usable in a script. Without it the command returns as soon as the deployment has started.
- `--timeout` caps that wait. It defaults to 20 minutes and only applies with `--wait`.
See the [deploy command reference](https://lucity.cloud/docs/cli#deploy) for the full list.
To check the status of a service's current deployment:
```bash
lucity status myproject/production/web
```
That exits non-zero when the rollout is failed or degraded, so a pipeline can gate on it.
In CI, set `LUCITY_API_TOKEN` to a workspace API token instead of signing in interactively. The CLI picks it up from the environment.
:::
:::tabs-item{label="GitHub Actions"}
Lucity can deploy from a GitHub Actions workflow without you configuring a token anywhere, which is useful when the deploy should wait for something else first, such as a test suite. Turn on **CI Deploys** for the service under **Settings** → **Source**, then give the job an OIDC identity:
```yaml
name: Deploy
on:
push:
branches: [main]
jobs:
deploy:
runs-on: ubuntu-latest
permissions:
id-token: write
steps:
- name: Install the Lucity CLI
env:
GH_TOKEN: ${{ github.token }}
run: |
gh release download --repo zeitlos/lucity \
--pattern 'lucity_*_linux_amd64.tar.gz' --output - | tar xz
sudo install lucity /usr/local/bin/lucity
- name: Deploy
run: lucity deploy myproject/production/web --ref "$GITHUB_SHA" --wait
```
The `id-token: write` permission is what makes this keyless. The CLI exchanges the job's OIDC token for a short-lived session that can only deploy services built from that same repository with CI deploys enabled.
:::
:::tabs-item{label="API"}
To deploy through the [GraphQL API](https://lucity.cloud/docs/api), get an access token as described under [authentication](https://lucity.cloud/docs/api#authentication). Deploying is then a single mutation:
```bash
curl https://lucity.cloud/graphql \
-H "Authorization: Bearer $(lucity token)" \
-H "Content-Type: application/json" \
-d '{"query":"mutation { deploy(service: \"acme/myproject/production/web\") { id status } }"}'
```
The service id starts with the workspace here, because the API always takes the full id. Pass `gitRef` alongside `service` to build something other than the tracked branch.
:::
::
## Configuration changes
Not every change needs a new image. Editing [variables](https://lucity.cloud/docs/variables), CPU and memory, the port, the start command, the health check or a volume mount reuses the image the service is already running, and applies within seconds. The new instance starts, passes its health check, and takes over before the old one goes away, so a running service does not go dark while you change it. The exception is a service with a volume attached, which [stops before the replacement starts](https://lucity.cloud/docs/volumes#rollout-downtime).
Changing the replica count is the one change that is not a rollout at all. Existing instances keep serving and new ones simply join them.
## Rollouts
The rollout is the part where running containers are replaced, and it is arranged so that the service keeps answering throughout.
A new instance starts alongside the old one and receives no traffic until its [health check](https://lucity.cloud/docs/services#health-checks) passes. Once it does, the old instance is taken out of rotation and given ten seconds to finish requests that are already in flight before it is asked to shut down. The whole shutdown has a 30 second budget, so roughly 20 seconds are left for your process to exit on its own before it is killed. That is why [handling the shutdown signal](https://lucity.cloud/docs/services#graceful-shutdown) matters if you care about the last few requests.
The count never dips below what you asked for. Lucity adds an instance before removing one, rather than the other way around, so a single-replica service is covered too.
Two cases work differently:
- **A service with a [volume](https://lucity.cloud/docs/volumes)** cannot overlap, because the disk is still attached to the instance being replaced. It stops first and starts again, which means [a short gap on every deploy](https://lucity.cloud/docs/volumes#rollout-downtime).
- **A service with no port** has nothing to health check, so a new instance counts as ready as soon as its container is up.
## Rollout failures
If the new instance never becomes healthy, the old one keeps serving and the deployment is marked failed. Nothing is lost and there is no rush: you can take as long as you need to work out what went wrong.
The deployment shows a reason, which is usually one of these:
| Reason | What it usually means |
| ----------------- | ---------------------------------------------------------------------------------------------------------------------------------------- |
| Crash loop | The container starts and exits repeatedly. The exit code is shown with it, and the [logs](https://lucity.cloud/docs/logs) have the rest. |
| Out of memory | The container exceeded its memory limit. Raise it, or find out what is holding the memory. |
| Image pull failed | The image could not be fetched. Most common on services built from a public image reference that no longer resolves. |
| Config error | The container could not be created from its configuration at all. |
| Quota exceeded | The environment ran out of its [resource budget](https://lucity.cloud/docs/environments#resource-quotas). |
| Unschedulable | There is no capacity to place the instance right now. |
| Not ready | The container runs fine but the health check never passes. |
| Deadline exceeded | The rollout made no progress within the time allowed. |
A deployment is **degraded** when some of its new instances came up and others did not, and **failed** when none of them did.
The service is a separate reading, and usually the one you care about. While the previous version is still serving, a service with a failed deployment shows as **Degraded**: your users are fine, the new version is not. It only shows as **Failed** once nothing healthy is left, which happens on a first deployment that never worked, or on a service whose old instance had to be stopped before the new one could start, such as one with a [volume](https://lucity.cloud/docs/volumes#rollout-downtime) attached.
## Rollbacks
Reverting the change in git and pushing is always available, and with auto-deploy on it is often the first thing to reach for. That rebuilds, so it takes as long as any other deployment, but it leaves your repository and what is running in agreement.
When you want the previous version back without waiting for a build, Lucity can point the service straight at an image it already ran. Every deployment keeps its image, so this is live in seconds.
::tabs
:::tabs-item{label="Dashboard"}
Rolling back is not exposed in the dashboard yet. Until it is, use the Claude plugin or the API, or revert in git and let the service rebuild.
:::
:::tabs-item{label="Claude plugin"}
Install the [Claude plugin](https://lucity.cloud/docs/claude-plugin) and ask for it in your own words: "Payments have been failing in production since this morning. Find the commit that touched the payment flow and roll the api service back to whatever was deployed before it."
Run from your local checkout, the agent has your git history and the service's deployment history in front of it at the same time, so it can work out which deployment predates the change and put the service back on that image. No rebuild happens, because the image is still there.
:::
:::tabs-item{label="API"}
Call the `rollback` mutation with the id of a previous deployment, which you can read off the service in the [API](https://lucity.cloud/docs/api):
```bash
curl https://lucity.cloud/graphql \
-H "Authorization: Bearer $(lucity token)" \
-H "Content-Type: application/json" \
-d '{"query":"mutation { rollback(deployment: \"acme/myproject/production/web/bd6597fcb\") }"}'
```
:::
::
## One deployment at a time
Deployments queue rather than running all at once. At most one is active per [environment](https://lucity.cloud/docs/environments), so two pushes in quick succession cannot race each other into conflicting states. Queued deployments are admitted oldest first as the ones ahead of them finish.
There is also a limit on how many deployments a workspace can have waiting. Past that, a deploy is rejected with a message saying the queue is full, and you try again once something has drained.
## Next steps
- [Builds](https://lucity.cloud/docs/builds) for how a repository becomes an image
- [Services](https://lucity.cloud/docs/services) for health checks, replicas and resources
- [Logs](https://lucity.cloud/docs/logs) for what a failing container printed on its way down
- [Environments](https://lucity.cloud/docs/environments) for keeping production separate from everything else
# Builds
A build takes a commit from your repository and produces a container image that Lucity can run. You do not describe how: the builder reads your project, works out what language and framework it is, installs the right toolchain, installs your dependencies, runs your build script, and assembles an image around the result.
This happens on every [deployment](https://lucity.cloud/docs/deployments) of a service built from a repository. Services created from an existing image skip all of it.
## Detection
Detection runs against the files already in your project. A `package.json` makes it a Node project, a `go.mod` a Go project, a `requirements.txt` or `pyproject.toml` a Python one. The same goes for Bun, Deno, PHP, Ruby, Rust, Java, .NET, Elixir, Gleam and C++, and a repository with none of those still builds if it has a `Procfile`, a shell script, or a directory of static files.
Frameworks get their own handling on top of the language. Next.js, Astro, Vite, Angular, React Router and Expo are recognized on the Node side, Django on the Python side, Laravel on the PHP side, each with the build and start commands that framework expects. The [guides](https://lucity.cloud/docs/guides) cover the ones people ship most.
Toolchain versions come from wherever your project already declares them: the `go` directive in `go.mod`, `engines` in `package.json`, a `.python-version` file. If nothing says, you get a current stable version, and you can pin one explicitly with a variable.
The start command is derived the same way, from your `start` script, your entrypoint, or the binary that was just compiled. You can [override it on the service](https://lucity.cloud/docs/services#start-command) afterwards.
## Build steps
Every step shows up in the build log, which you find in the service's **Deployments** tab, under the **Build** step of the deployment. It streams while the build runs.
1. **Clone.** The repository is fetched at the commit being deployed.
2. **Detect.** The builder inspects the repository and produces a plan containing the toolchain to install, the commands to run, and how to assemble the image.
3. **Install.** The toolchain goes in first, then your dependencies. Your lockfile and manifest are copied in on their own before the install command runs, without the rest of the project.
4. **Copy the source.** The rest of your project goes in after the dependencies are already there.
5. **Build.** Your build command runs. This is the step where `next build`, `vite build`, `go build` or `mix compile` happens.
6. **Assemble and push.** The toolchain, your dependencies and your built application are combined into a runtime image, which is pushed to the platform registry and tagged with the short commit hash.
Installing dependencies before the rest of your source is copied in is what makes rebuilds fast. Change application code without touching your lockfile and the dependency install is cached.
## Build-time variables
Every [variable](https://lucity.cloud/docs/variables) on the service is available while it builds, not just while it runs. That is what makes `NEXT_PUBLIC_*`, `VITE_*` and friends work, and it is also how you configure the builder itself.
It cuts both ways. A variable that is read at build time is baked into the image, so changing it does not take effect until the next build, even though saving it rolls the service out. Anything read at runtime picks up the new value on that rollout.
::note
Keep secrets out of the parts of your build that write to the image. An API key inlined into a JavaScript bundle ships to every visitor, and one baked into an image layer stays readable to anyone who can pull that image. Read secrets at runtime instead, where a rotation reaches the service on the next rollout.
::
## Build configuration
The builder reads `RAILPACK_`-prefixed variables as instructions. Set them like any other [variable](https://lucity.cloud/docs/variables) on the service:
| Variable | What it does |
| ------------------------------ | ------------------------------------------------------------------ |
| `RAILPACK_INSTALL_CMD` | Replaces the detected dependency install |
| `RAILPACK_BUILD_CMD` | Replaces the detected build command |
| `RAILPACK_START_CMD` | Replaces the detected start command |
| `RAILPACK_PACKAGES` | Extra toolchain packages, for example `python@3.12` alongside Node |
| `RAILPACK_BUILD_APT_PACKAGES` | System packages available while building |
| `RAILPACK_DEPLOY_APT_PACKAGES` | System packages present in the final image |
Versions get their own variables per language: `RAILPACK_NODE_VERSION`, `RAILPACK_PYTHON_VERSION`, `RAILPACK_GO_VERSION`, `RAILPACK_RUBY_VERSION`, `RAILPACK_RUST_VERSION`, `RAILPACK_JDK_VERSION`, and so on.
Some providers add their own. Go reads `RAILPACK_GO_BIN` when a repository has several binaries under `cmd/`, Angular reads `RAILPACK_ANGULAR_PROJECT`, PHP reads `RAILPACK_PHP_ROOT_DIR`. Railpack's [environment variables reference](https://railpack.com/config/environment-variables) has the full list.
## Custom build plans
For anything the variables cannot express, put a `railpack.json` at the root of your build directory. It is read as configuration and gives you direct control over the plan: the packages to install, the steps to run, what each step depends on, and what ends up in the final image.
Railpack's [configuration file reference](https://railpack.com/config/file/) documents the format.
## Root directory
A service does not have to build from the top of the repository. Each one has a root directory, and pointing each service at its own folder is how a monorepo works here: `apps/api` for the API, `apps/web` for the web app, one service each.
Everything resolves relative to that directory: detection, the install and build commands, and any [`railpack.json`](https://lucity.cloud/#custom-build-plans). The clone still covers the whole repository, so shared packages outside the root directory are on disk, but whether your tooling can reach them is down to your package manager rather than to Lucity.
The root directory is set when the service is created and cannot be changed afterwards. The dashboard does not offer the field yet, so today it is set through the [API](https://lucity.cloud/docs/api):
```bash
curl https://lucity.cloud/graphql \
-H "Authorization: Bearer $(lucity token)" \
-H "Content-Type: application/json" \
-d '{"query":"mutation { addService(environment: \"acme/shop/production\", input: { name: \"api\", repository: \"acme/shop\", contextPath: \"apps/api\" }) { id } }"}'
```
Asking the [Claude plugin](https://lucity.cloud/docs/claude-plugin) to add the service does the same thing without the GraphQL, since its `add_service` tool takes the root directory as `context_path`.
::note
A push to the tracked branch deploys every service that tracks it, whether or not anything under its directory changed. There is no path filtering, so in a busy repository turn off auto-deploy and
[deploy from a workflow](https://lucity.cloud/docs/deployments#triggering-a-deployment)
instead, where the
`paths`
filter in GitHub Actions decides which services a commit should touch.
::
## Caching
Every service has a build cache. Each successful build fills it, and the next one starts from it, which is why a first build takes minutes and the ones after it usually take far less.
What gets reused follows the order of the steps:
- Changing your **lockfile** reinstalls dependencies, and everything after that runs again.
- Changing **application code** reuses the dependency install and reruns the build command.
- Changing a **variable** invalidates the build from the point where variables are read onwards.
- The **toolchain install** is reused until you change the version.
The very first build for a service has nothing to import, and the log says so with a line that looks alarming and is not:
```text
#1 importing cache manifest from ...:buildcache
#1 ERROR: failed to configure registry cache importer: ...:buildcache: not found
```
That is the cache being absent on a first build. The build carries on and populates it.
## Troubleshooting
If a build fails, start with the build log. You find it in the service's **Deployments** tab, under the **Build** step of the deployment that failed. Nothing is deployed when a build fails, so the version that was already running keeps running and there is no rush.
Most failures are ordinary and the log says so plainly: a dependency that will not install, a type error, a script that does not exist. Two are worth knowing about because the log is less forthcoming. A build that stops mid-command without printing an error has usually run out of memory, and deploying again is worth trying before you go hunting for a cause. A build still running after 30 minutes is cancelled, and builds are never retried automatically.
If the log does not make it obvious, hand it to the [Claude plugin](https://lucity.cloud/docs/claude-plugin). It can read the failing build's log alongside your local checkout, work out which change broke it, and usually fix it and deploy again.
Deploying a commit that is already building joins the build in progress rather than starting a second one.
::note
A
`Dockerfile`
in your repository is ignored. The builder works from your project files rather than from build instructions you write. When you need exact control over the image, build it yourself, publish it, and add it as a
[service from an image](https://lucity.cloud/docs/services#source-builds-and-prebuilt-images)
instead.
::
## Under the hood
Detection and the build plan come from [Railpack](https://railpack.com). The Railway team open-sourced the one part of their platform that felt like magic, and we took them up on it. The plan is compiled into a [BuildKit](https://github.com/moby/buildkit) build graph and solved by a shared BuildKit daemon, which is what does the layer caching and the parallelism you can see in the log.
What comes out is an ordinary OCI image in the platform's registry. There is nothing Lucity-specific inside it, so the same image runs under any container runtime, which is part of what makes [ejecting](https://lucity.cloud/docs/eject) work.
## Next steps
- [Deployments](https://lucity.cloud/docs/deployments) for what happens once the image exists
- [Variables](https://lucity.cloud/docs/variables) for the build-time and runtime split
- [Services](https://lucity.cloud/docs/services) for ports, health checks and resources
- [Guides](https://lucity.cloud/docs/guides) for what the builder does with your particular framework
# Variables
Variables are how a service is configured without changing its code. Each one is a key and a value, and the service reads them as ordinary environment variables. Which database to connect to, which API to call, which feature to switch on: all of it lives here rather than in the repository.
A variable belongs to one service. Development and production are separate services in separate [environments](https://lucity.cloud/docs/environments), so they keep separate variables, which is what lets them point at different databases while running identical code.
## Service variables
Open a service and go to its **Variables** tab. Add a key, give it a value, and save.
Keys start with a letter or an underscore and continue with letters, digits and underscores. `DATABASE_URL` and `_internal` are fine, `2fast` and `my-key` are not.
Two conveniences worth knowing about:
- **Paste several at once.** Drop `KEY=value` lines straight into a key field and each line becomes its own variable, so moving a `.env` file across is one paste rather than twenty.
- **Values are hidden by default.** Saved values show as dots until you reveal them, individually or all at once, so a variables tab is safe to have open while screensharing.
## Dynamic variables
Databases, key-value stores and buckets each expose a set of variables, such as their hostname, port and credentials. Any service in the same environment can consume them directly.
This means you never have to copy sensitive credentials by hand. You pick the one you want from a dropdown in the dashboard instead, and if a database credential is ever rotated, every service consuming it follows along with no changes on your side.
To create a dynamic variable, open the service's **Variables** tab, click the link icon in the value field, and pick from the list. Each resource exposes its own set:
| Resource | Variables it exposes |
| -------------------------------------------------- | ---------------------------------------------------------------- |
| [PostgreSQL](https://lucity.cloud/docs/postgres) | `fqdn-uri`, `host`, `port`, `dbname`, `user`, `password` |
| [Key-value store](https://lucity.cloud/docs/redis) | `uri`, `host`, `port`, `password` |
| [Bucket](https://lucity.cloud/docs/object-storage) | `bucket`, `endpoint`, `region`, `accessKeyId`, `secretAccessKey` |
`fqdn-uri` and `uri` are complete connection strings, which is usually all you need. You can consume one as `DATABASE_URL` or `REDIS_URL` and are done. The individual parts are there for libraries that insist on being handed a host and a port separately.
A service can only consume variables exposed in its own environment. A production service cannot reach into development for a value, which is deliberate.
::note
A dynamic variable is read when an instance starts, so a rotated credential reaches the service on its next rollout rather than instantly.
::
## Shared variables
Some values belong to a whole environment rather than one service: an API key three services all need, a log level you want to change in one place.
Set those under the project's **Settings**, in the **Variables** section. They belong to the environment you are looking at, so development and production keep separate sets.
A service consumes a shared variable from its own **Variables** tab, the same way it consumes a dynamic variable. They appear in the picker under **Shared**.
## Build time and runtime
Service variables are available while the service [builds](https://lucity.cloud/docs/builds) as well as while it runs, so anything your build reads, such as `NEXT_PUBLIC_*` or `VITE_*` values, is there.
A value read during the build is baked into the image and stays there until the next build. A value read at runtime is picked up on the next rollout, which [saving a variable](https://lucity.cloud/#what-happens-when-you-save) triggers on its own. Editing a build-time variable therefore needs a rebuild before it takes effect.
::note
Keep secrets out of build-time variables that end up in the image. Anything inlined into a client-side bundle ships to every visitor, and anything baked into an image layer is readable by anyone who can pull that image. Read secrets at runtime instead.
::
## What happens when you save
Saving variables restarts the service on the image it is already running. The new instance starts with the new values and only takes over once it passes its health check, so the service keeps answering throughout with no downtime. See [rollouts](https://lucity.cloud/docs/deployments#rollouts) for how that works, and for the exceptions.
Changing configuration never triggers a build. A new image is only made when you deploy, whether that is a push to the tracked branch, the **Deploy** button in the dashboard, or the CLI. See [configuration changes](https://lucity.cloud/docs/deployments#configuration-changes) for everything else that behaves this way.
## Next steps
- [Services](https://lucity.cloud/docs/services) for the ports, health checks and resources that variables sit alongside
- [PostgreSQL](https://lucity.cloud/docs/postgres), [key-value stores](https://lucity.cloud/docs/redis) and [object storage](https://lucity.cloud/docs/object-storage) for the resources that expose them
- [Builds](https://lucity.cloud/docs/builds) for what the builder does with a `RAILPACK_` variable
- [Deployments](https://lucity.cloud/docs/deployments) for what a rollout actually does
# Domains
A service is private by default. It answers inside its [environment](https://lucity.cloud/docs/environments) and nowhere else. A domain is what changes that: it gives the service a public hostname, terminates HTTPS in front of it, and routes traffic to the port it listens on.
There are two kinds of domains. A platform domain is one click and works immediately, and a service has one of them. A custom domain is a hostname you own, which takes two DNS records and a few minutes, and a service can have as many as it needs.
Both need the service to have a [port](https://lucity.cloud/docs/services#ports). A service that does not listen on one has nothing to route to.
## Platform domains
Open the service, go to **Settings** → **Networking** → **Platform Domain**, and click **Generate Domain**. You get something like:
```text
vouch-development-ee6tz.lucity.app
```
The name is built from the service, the environment, and a short random suffix that keeps it unique across the platform. DNS resolution and HTTPS both work pretty much instantly: there are no records to add and no certificate to wait for.
This is the right choice for development environments, for previews, and for anything internal where the URL does not need to be memorable. When you want a hostname of your own, add a custom domain alongside it: the platform domain keeps working, so nothing breaks while you set the other one up.
## Custom domains
Under **Settings** → **Networking** → **Custom Domains**, enter the hostname you want and Lucity shows you the DNS records to add at your provider, with the exact values ready to copy.
Every custom domain needs two records: one that proves you control the domain, and one that points traffic at the platform. Which routing record you add depends on whether you are pointing a subdomain or the domain itself.
### Subdomain
For `api.example.com`, `www.example.com`, or anything else below the domain:
| Type | Host | Value |
| ------- | ---------------------------- | ------------------------------------------------------ |
| `TXT` | `_lucity-verify.example.com` | A challenge string unique to your workspace and domain |
| `CNAME` | `api.example.com` | `lb.lucity.app` |
### Apex domain
For `example.com` itself, with nothing in front of it:
| Type | Host | Value |
| ----- | ---------------------------- | ------------------------------------------------------ |
| `TXT` | `_lucity-verify.example.com` | A challenge string unique to your workspace and domain |
| `A` | `example.com` | The platform's IP address, shown with the record |
An apex domain uses an `A` record because DNS does not allow a `CNAME` at the root of a zone. Everything else about it works the same way.
Notice that the `TXT` record is identical in both cases: it goes on the domain, not on the hostname you are adding. One of them covers every hostname under that domain, so the second and third you add need only their own routing record.
## Verification and certificates
Lucity picks up a record as soon as your DNS provider is serving it, without waiting for caches elsewhere to expire. The check runs every couple of minutes on its own, and the **Check** button next to the domain runs it immediately.
Once both records verify, two things happen. The route goes live, so the hostname reaches your service. And a certificate is requested from Let's Encrypt, which usually takes a few seconds and occasionally a minute. HTTPS starts working on that hostname when the certificate is issued, and renews itself from then on.
## Troubleshooting
Each domain shows a DNS state and a TLS state, and between them they say what is holding things up.
| State | What it means |
| --------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------- |
| DNS **pending** | Neither record has been seen yet. Normal for the first few minutes after you add them. |
| DNS **misconfigured** | One record is right and the other is not. Almost always the TXT record on the wrong name, or a routing record that does not resolve to the expected target. |
| DNS **error** | The lookup itself failed, usually a nameserver problem on the domain rather than a wrong record. |
| TLS **provisioning** | The certificate has been requested and is not issued yet. |
| TLS **error** | Issuance failed. Check that the domain still resolves to the platform, and that a `CAA` record is not blocking Let's Encrypt. |
The most common cause of a domain that never verifies is a **proxying DNS provider**. If your provider hides the target behind its own network, such as Cloudflare with the orange cloud switched on, a lookup of your hostname returns their addresses instead of the CNAME target, and the check cannot confirm that traffic reaches Lucity. Set the record to DNS-only.
## Removing a domain
The X next to a domain removes it. The route disappears straight away and the hostname stops reaching your service, though whatever you put in DNS stays there until you delete it too.
Removing a custom domain also removes its certificate. Add the same hostname again later and a fresh one is issued, so there is no benefit to leaving a domain attached to a service you are no longer serving from it.
## Under the hood
Domains are [Gateway API](https://gateway-api.sigs.k8s.io) objects. Each custom domain gets its own listener and its own [cert-manager](https://cert-manager.io) certificate in your environment's namespace, with an HTTPRoute pointing at your service. Platform domains attach to a shared listener with a wildcard certificate already in place, which is why they need no issuance step.
That is all standard Kubernetes, so an [ejected](https://lucity.cloud/docs/eject) project keeps its routing and its certificates without Lucity in the picture.
## Next steps
- [Services](https://lucity.cloud/docs/services) for the port a domain routes to
- [Environments](https://lucity.cloud/docs/environments) for keeping production hostnames separate from development ones
- [Deployments](https://lucity.cloud/docs/deployments) for what happens to traffic during a release
# PostgreSQL
Lucity gives you fully managed PostgreSQL. Provision a database in a couple of clicks, connect a service to it without handling credentials, and leave the running of it to the platform.
Every database comes with high availability and automatic failover, continuous backups with point-in-time recovery across the last 30 days, and encrypted connections. Rather than splitting those across plans, every Lucity database gets all of them. What you configure is the CPU, memory and storage it needs, so the database fits your workload rather than a tier.
## Provisioning
On the project canvas, click **Create** and choose **PostgreSQL**. Give it a name between 2 and 16 characters and confirm.
A database belongs to one [environment](https://lucity.cloud/docs/environments), so development and production each get their own. Provisioning takes a minute or two, after which the node on the canvas turns healthy and the credentials are available.
You get PostgreSQL 17, with a database called `app` owned by a user called `app`. That user owns everything it creates, so migrations, extensions and schema changes all work without asking anyone for permission.
## Connect
Your services reach the database over the private network inside their environment. By default nothing else can, though you can [expose it to the internet](https://lucity.cloud/#public-access) if you need to.
The way to connect a service is a [dynamic variable](https://lucity.cloud/docs/variables#dynamic-variables): open the service's **Variables** tab, add a key such as `DATABASE_URL`, click the link icon, and pick `fqdn-uri` from the database. The connection string is never copied anywhere, so there is nothing to keep in sync.
A database exposes six values:
| Variable | What it is |
| ---------- | ---------------------------------------------------------------------- |
| `fqdn-uri` | The complete connection string, which is usually the only one you need |
| `host` | The private hostname |
| `port` | `5432` |
| `dbname` | `app` |
| `user` | `app` |
| `password` | The generated password |
The **Connect** tab on the database shows the same values if you need to read them yourself.
## Public access
A database is private by default, which is where it should stay. When you need to reach it from an external tool, open the **Connect** tab and switch **Internet access** on.
That gives the database a public hostname on port 5432. The user and password stay the same as on the private network, so only the connection string changes. Traffic is encrypted end to end: TLS terminates at the database itself, not at a proxy in front of it.
Because of that, your client has to use TLS. Connect with `sslmode=require` or stricter, which the connection string shown in the dashboard already does. With TLS off, the connection will not reach the database at all.
::note
Your client also has to be recent enough to send SNI, which means libpq 14 or newer for anything built on it, including
`psql`
. Older clients connect to the right port and get nowhere.
::
### Allowed addresses
Only the addresses you allow can connect over the public hostname, so a freshly exposed database lets nobody in. When you switch **Internet access** on, you can allow the computer you're using right away, and later add more under **Allowed addresses**. Each entry is an IPv4 address like `203.0.113.7` or a range like `203.0.113.0/24`, and a short description helps you remember whose it is.
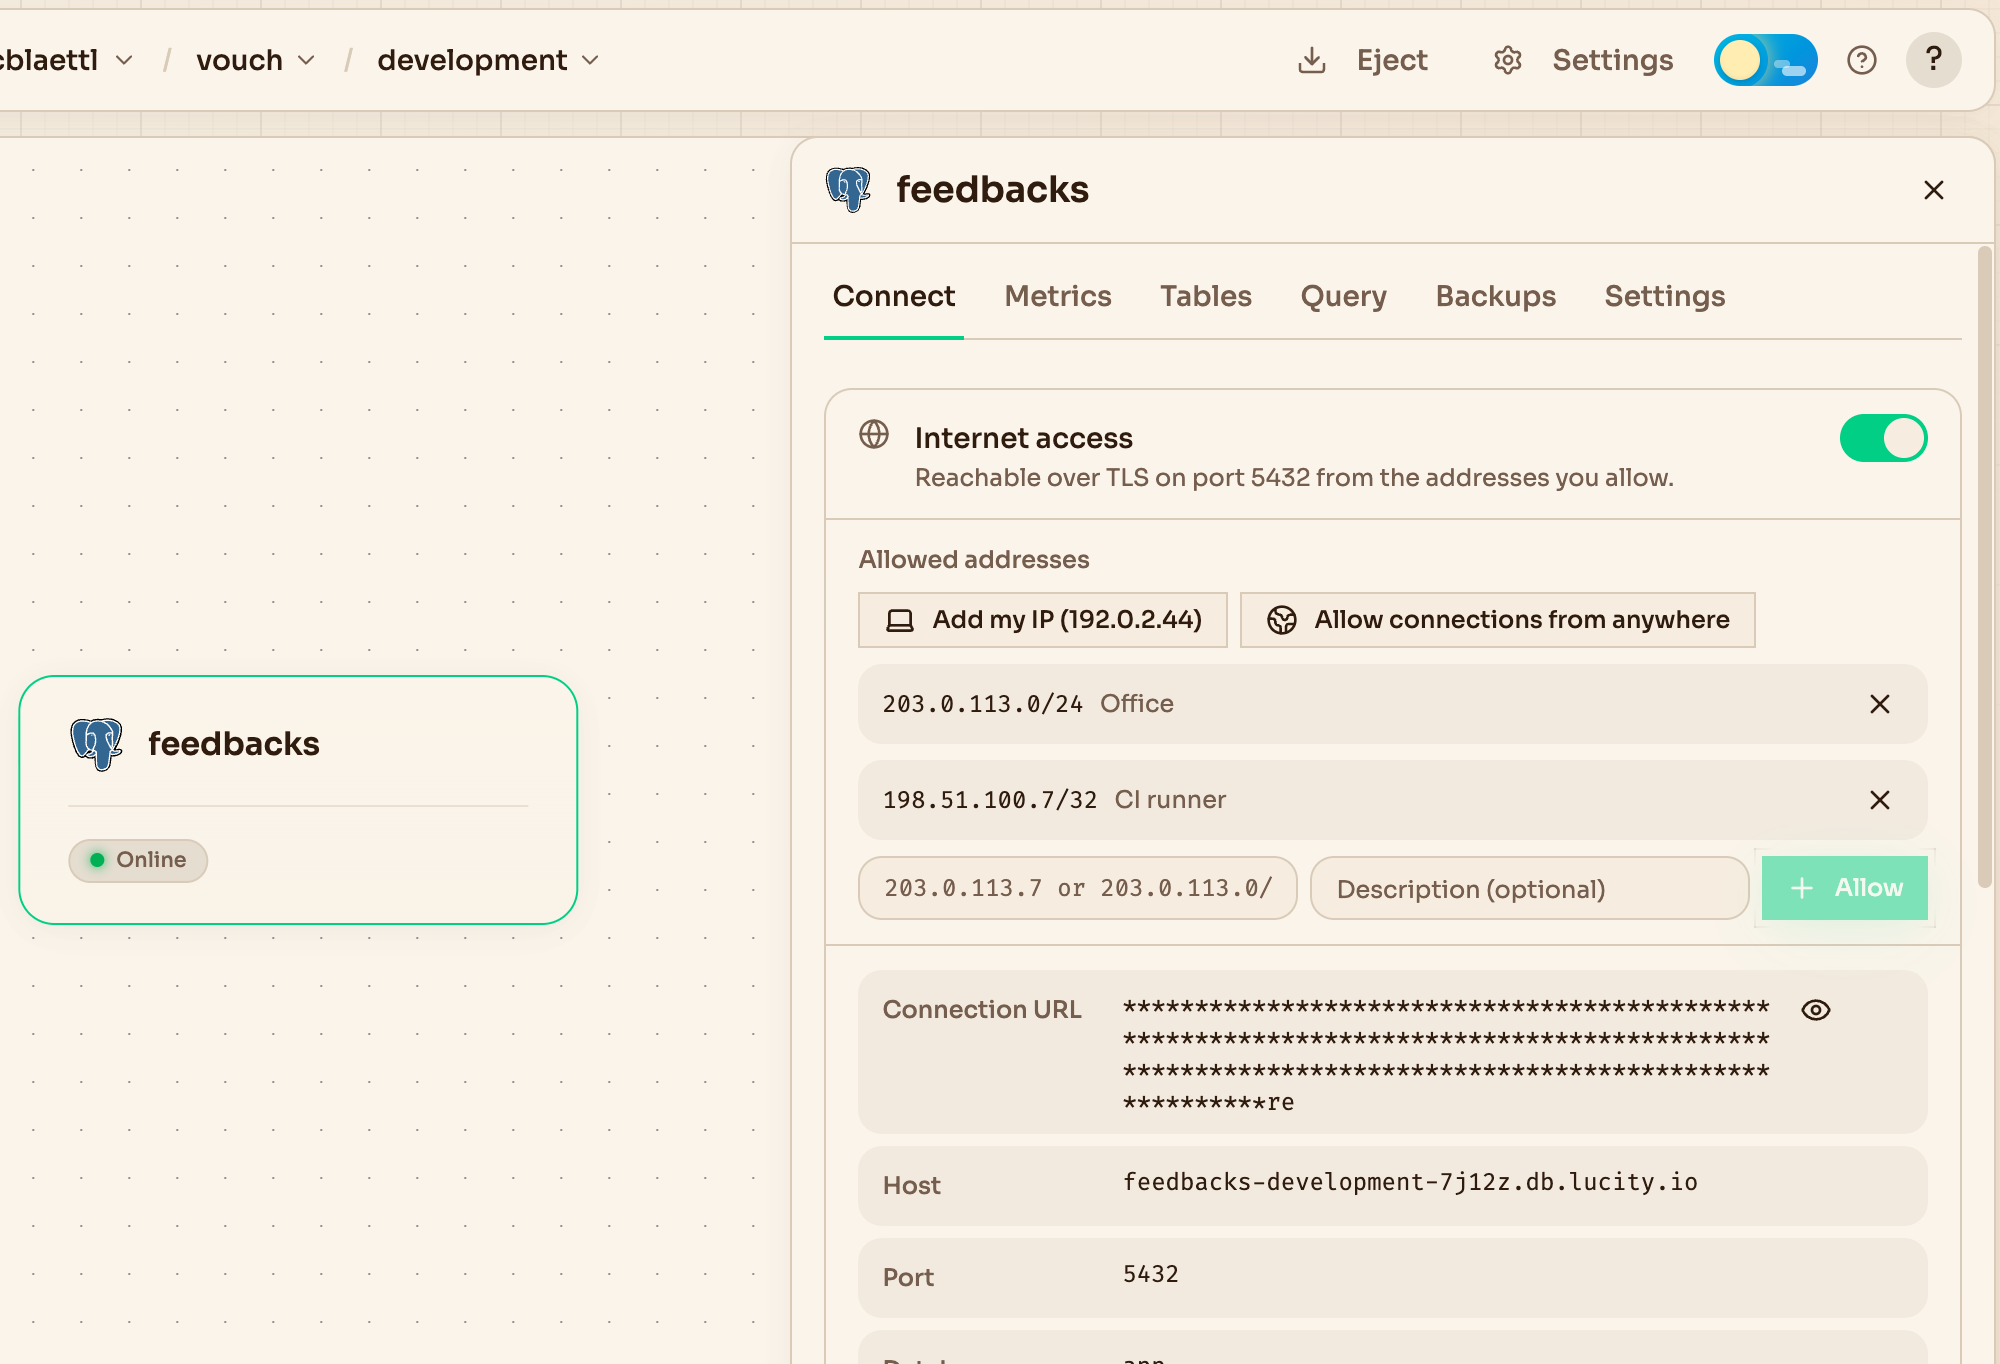
*Only the listed addresses can connect over the public hostname.*
**Allow connections from anywhere** adds `0.0.0.0/0`, which lets every address through. Then only the password protects the database, so prefer listing the addresses you actually connect from. Removing an entry never opens the database up, so once the last one is gone, nobody can connect.
Switching **Internet access** off removes the public hostname together with the allowed addresses. It takes effect immediately, so ideally leave the database unexposed and turn this on only for as long as you need it.
::note
A connection from an address that isn't allowed fails with
`SSL SYSCALL error: EOF detected`
, the same error an old client without SNI gets. If you see it, check that your current address is on the list.
::
## Resources and metrics
Under the database's **Settings** tab you can give it between 0.25 and 4 vCPU and between 256 MB and 16 GB of memory, defaulting to 0.5 vCPU and 512 MB. Changing either restarts the instances one at a time, so the database stays available throughout. Storage starts at 16 GB and grows in place up to 1 TB without downtime, but it never shrinks, so start with what you need and raise it as you go.
The **Metrics** tab shows how close the database is to those limits, next to connections, transactions, the cache hit ratio and how far the replica trails the primary. Below the charts, **Top queries** lists the statements that took the most time, so when the database gets slow you know which query to look at first. [Metrics](https://lucity.cloud/docs/metrics#database-metrics) explains every chart.
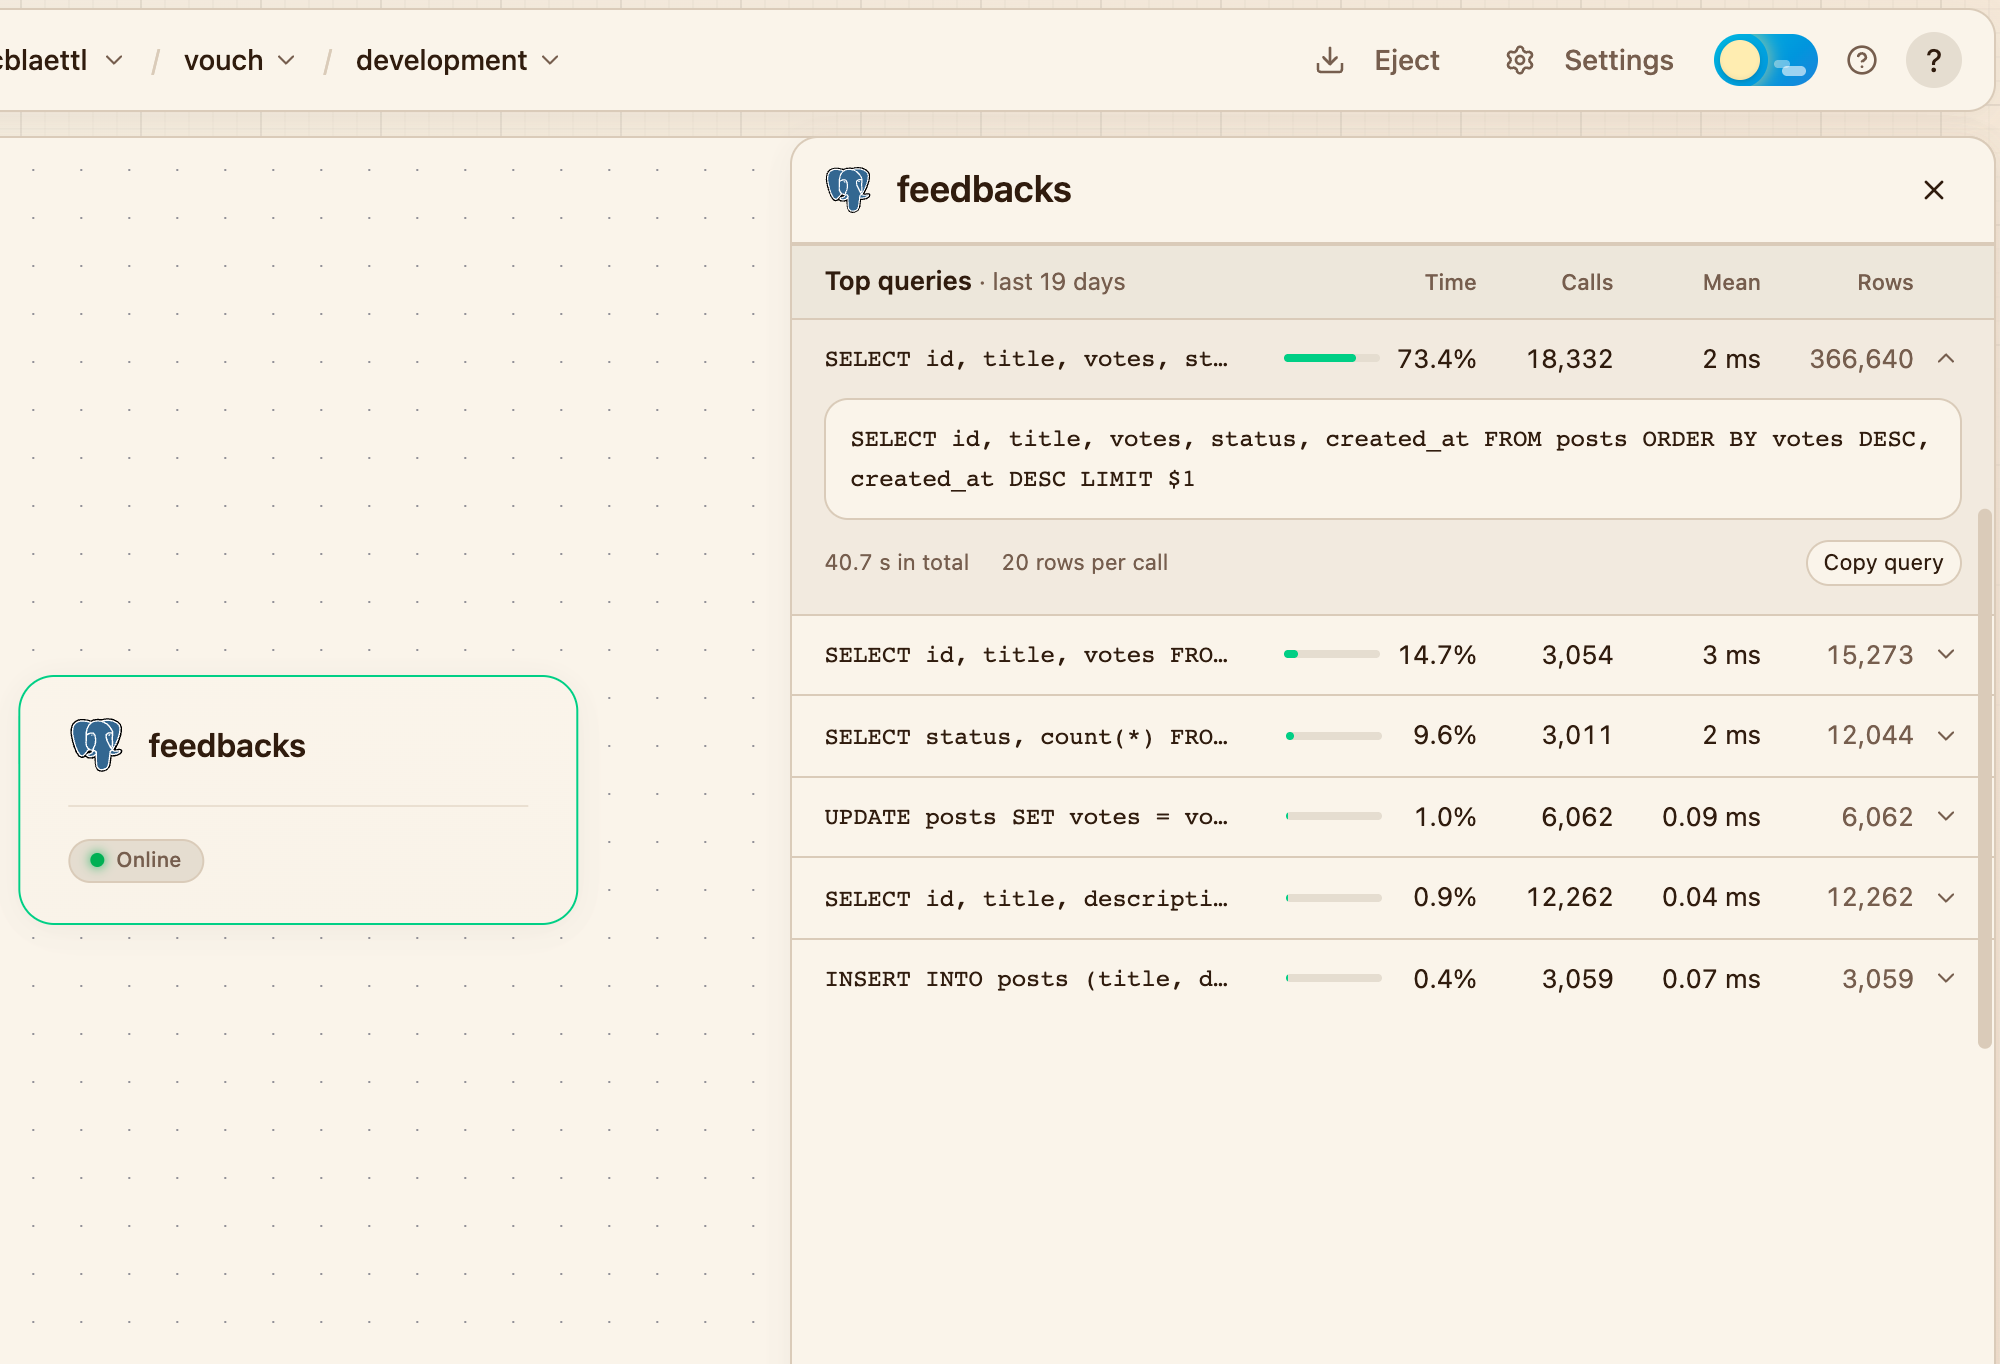
*Open a statement to read it in full and copy it.*
## Database explorer
Lucity gives you basic tools for working with your data straight from the dashboard.
**Tables** lists every table with its columns, types and an estimated row count, and shows the rows themselves a page at a time. It is the fastest way to check that your migration did what you expected.
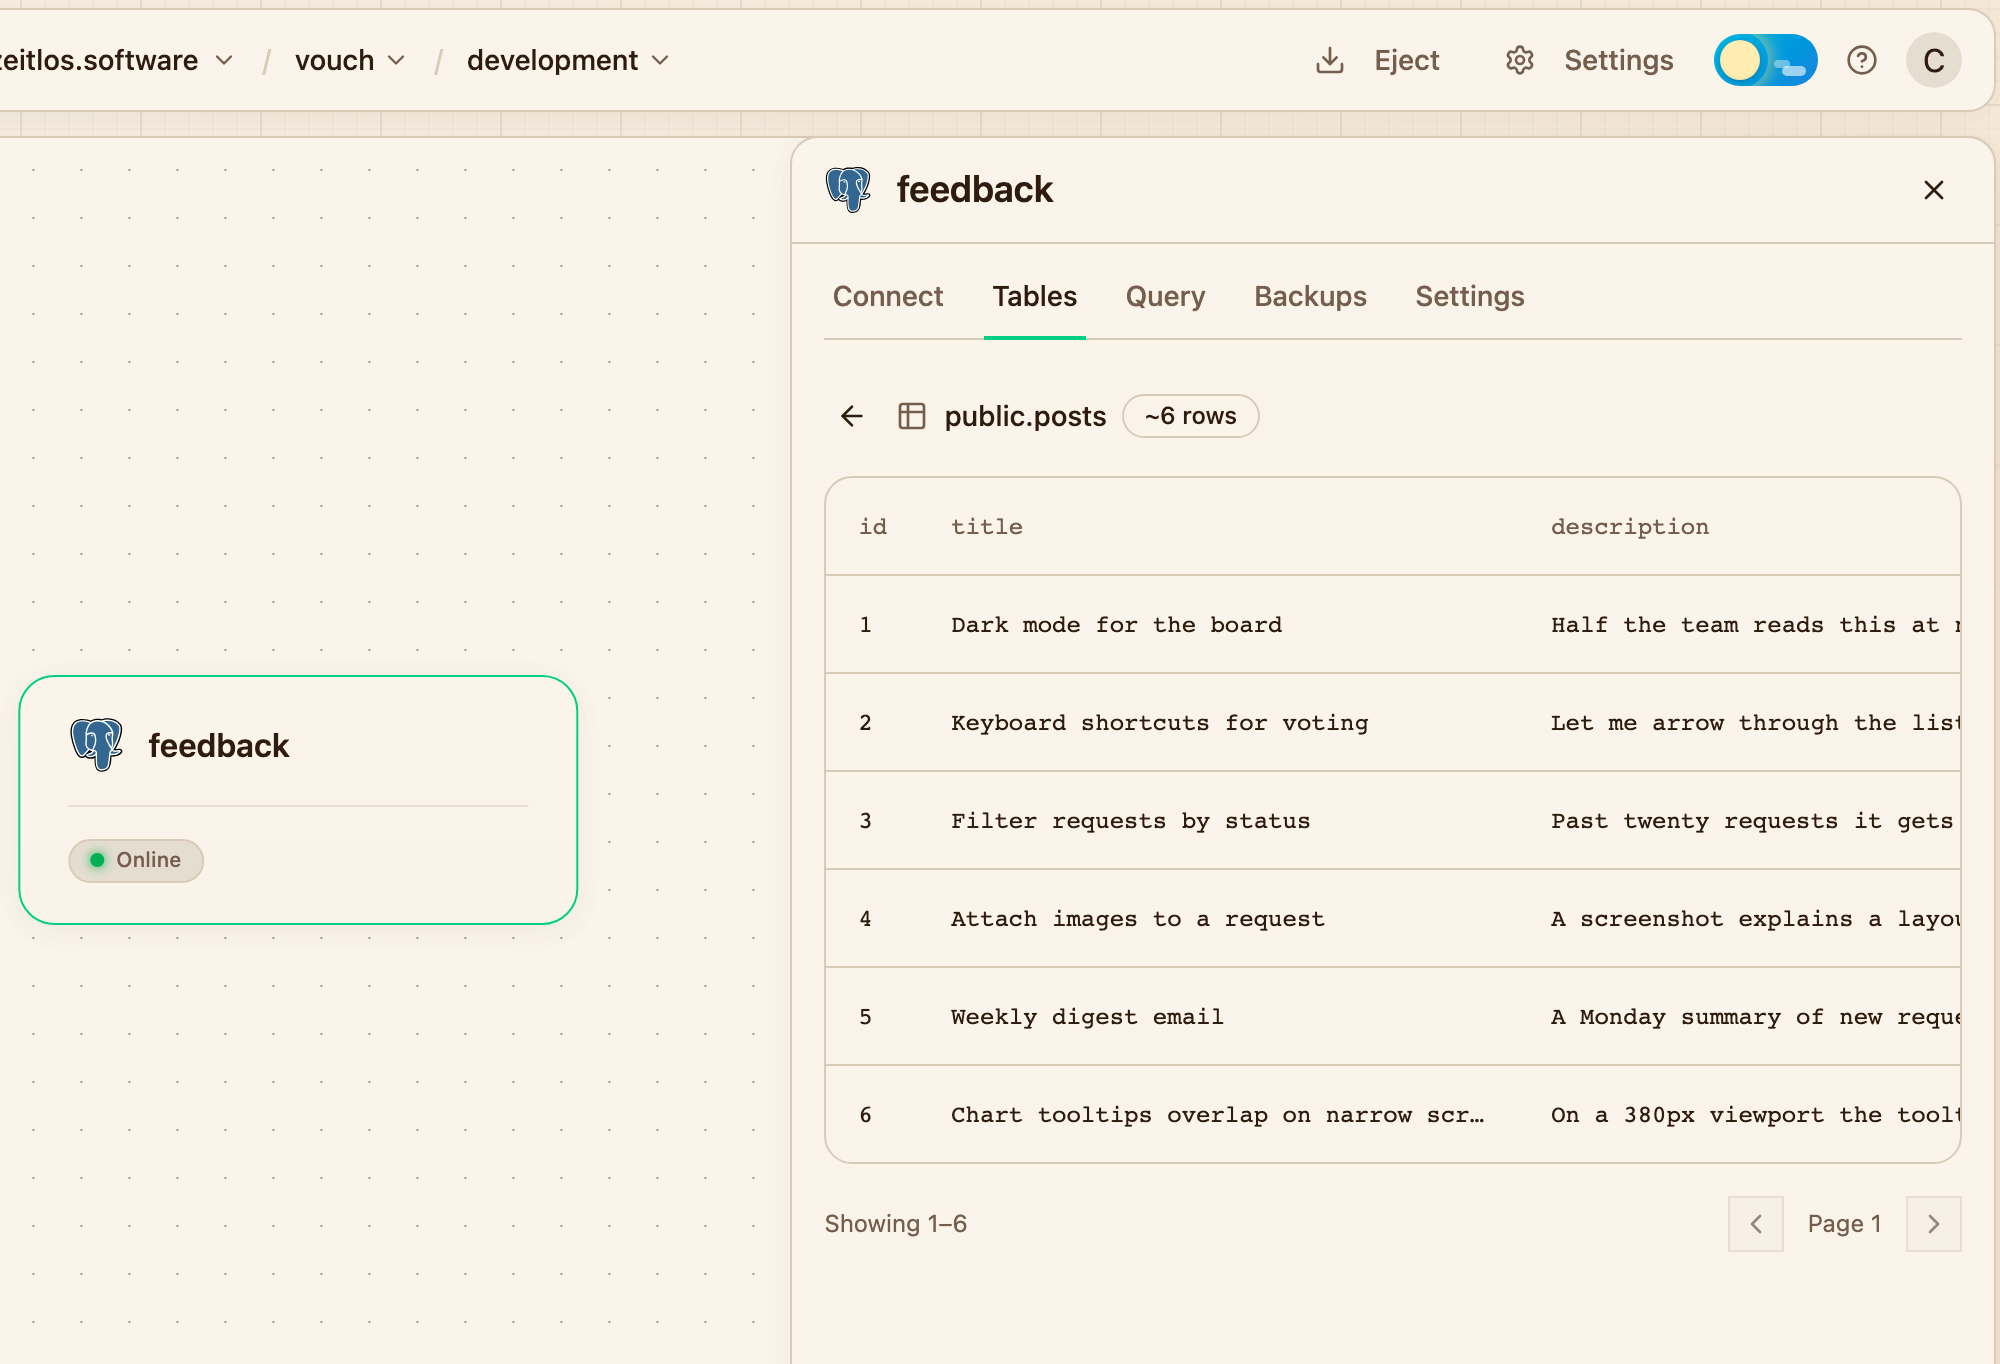
*Pick a table and read its rows without leaving the dashboard.*
**Query** runs SQL. It is a real connection, so it will happily write as well as read: be as careful here as you would be in `psql` against production. Statements are cut off after 30 seconds and results capped at 1000 rows, so use an external tool or a service in the same environment for long-running queries and migrations.
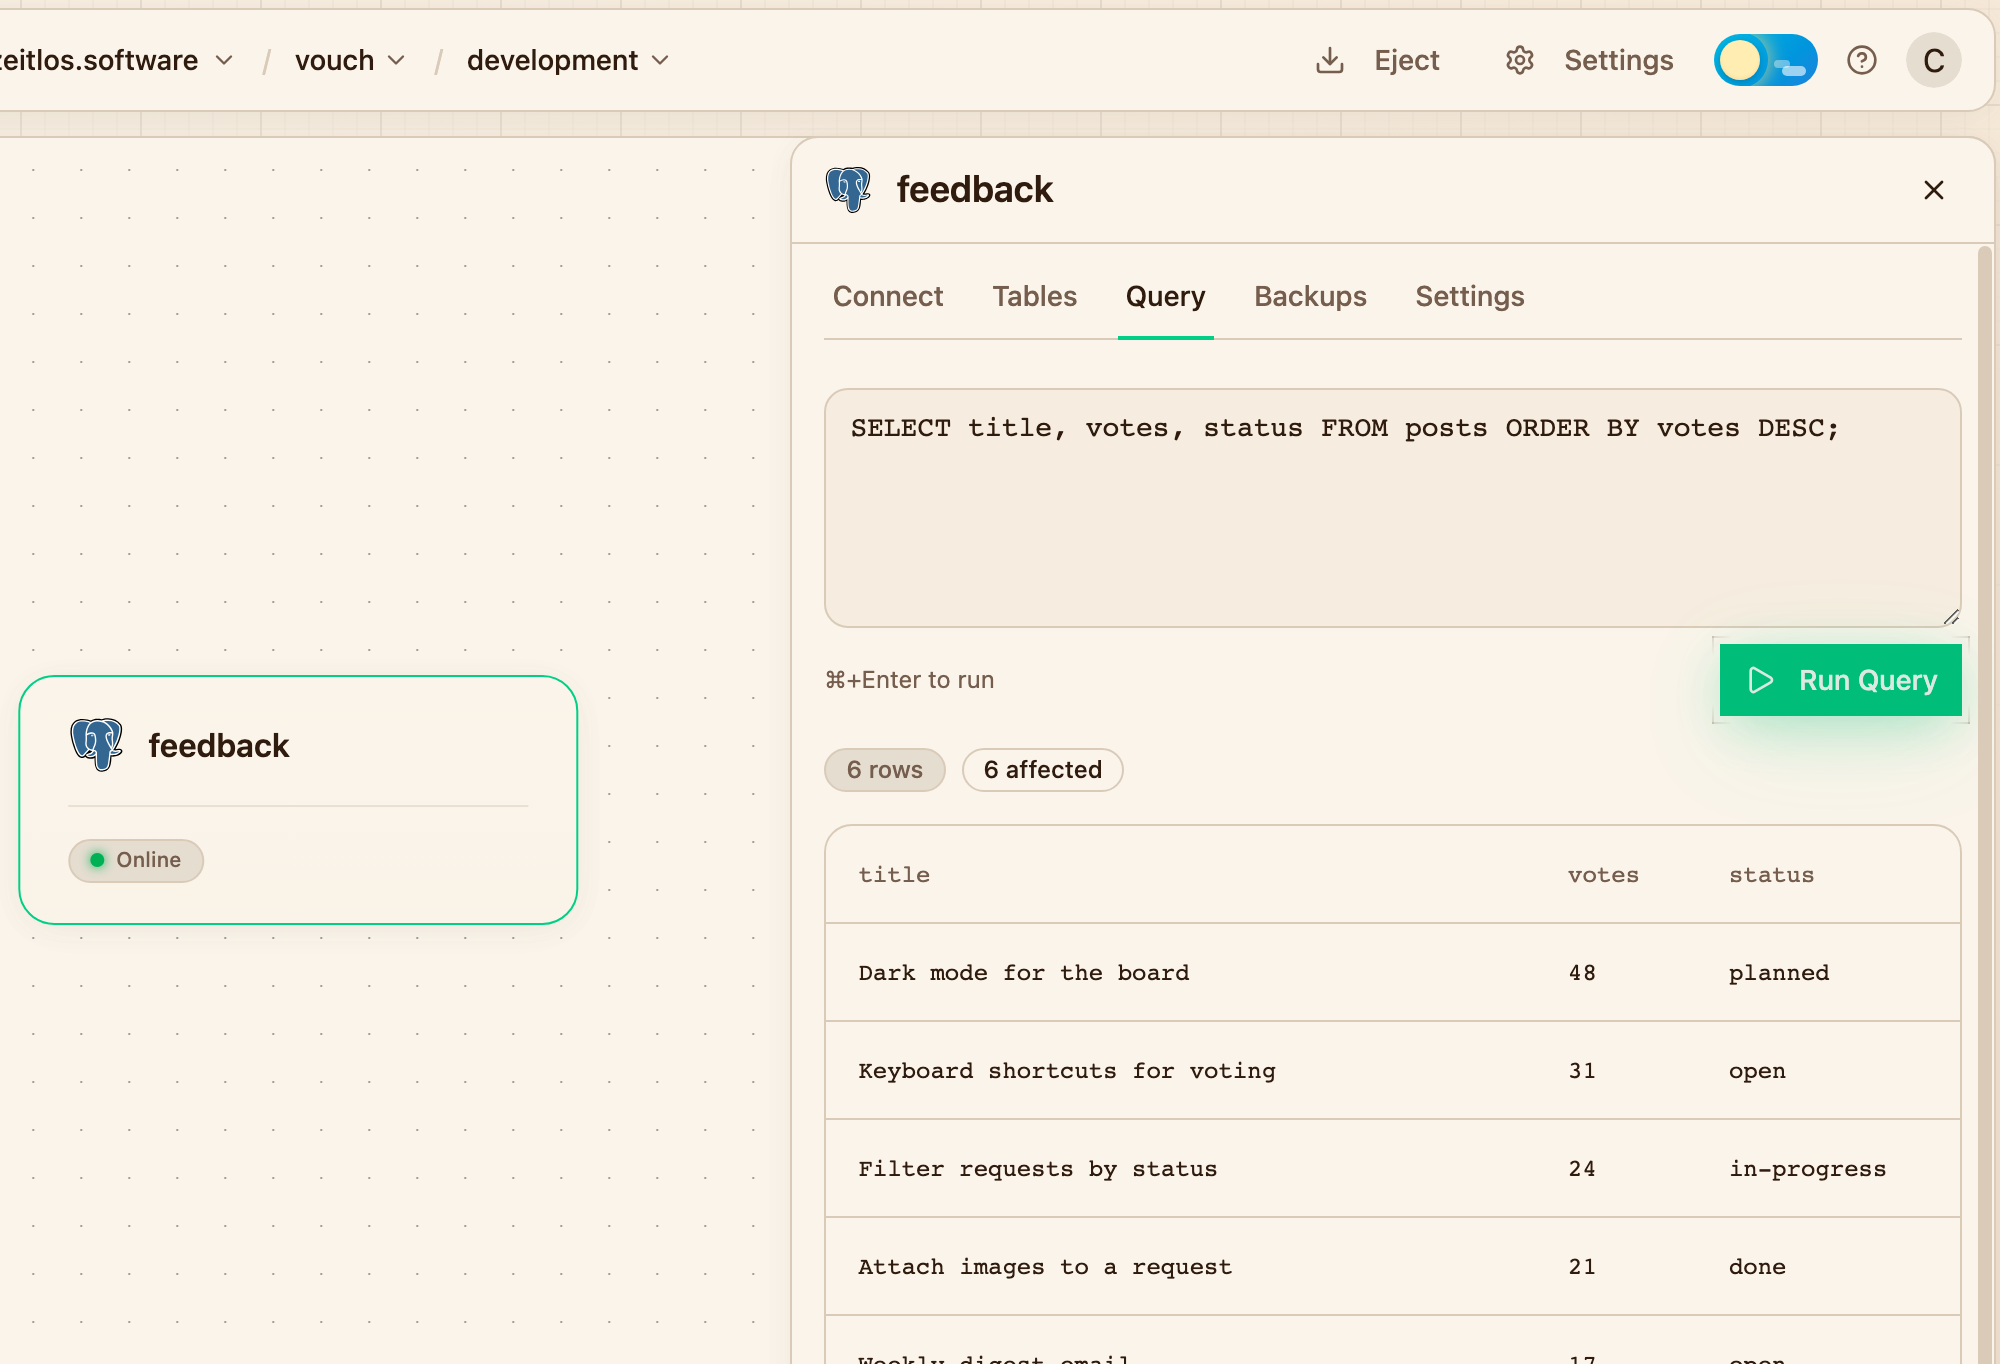
*A query and its result, run against the database from the dashboard.*
`pg_stat_statements` is enabled, and the [Metrics](https://lucity.cloud/#resources-and-metrics) tab already lists the statements costing you the most. Query it directly when you need more than that.
## Backups
Backups are enabled by default, with a retention of 30 days, and there is nothing to configure.
A full base backup runs weekly, on Sunday at 02:00 UTC. Between those, every write is archived continuously as it happens, so the database can be restored to any moment in the window rather than only to the times a backup happened to run.
The **Backups** tab shows how far back you can currently go, when the last backup completed, and the list of base backups with their status. You can also trigger one by hand there, which is worth doing before a migration you are unsure about.
## Point-in-time restores
Because every write is archived as it happens, you can restore to any moment inside the retention window, down to the second. This means you can restore your database to right before the moment something went wrong.
Restores always happen to a fresh database, which avoids any risk of data loss on the source. The original keeps running and serving traffic throughout.
From the **Backups** tab, choose a point in time and give the new database a name. When it comes up you have both, so you can compare them, copy across what you need, or point your service at the restored one by changing its `DATABASE_URL`.
*Any moment on the timeline can be restored. The marks are completed base backups.*
::note
A restored database is a new database with its own storage and its own bill. Delete it once you have what you needed from it.
::
## What's not there yet
Some things you might expect from a managed database are not built yet:
- **Choosing or upgrading the PostgreSQL version.** Every database is PostgreSQL 17.
- **Read replicas.** The standby is there to take over when the primary fails, not to serve reads. Every connection goes to the primary.
- **Extensions beyond the image.** You get the standard contrib set and `pgvector`. Anything else, PostGIS included, cannot be added.
- **Connection pooling.** There is no pooler in front of the database, so pool in your application and remember that the pool size counts per replica.
- **Exports from the dashboard.** Run `pg_dump` yourself, either against a [publicly exposed](https://lucity.cloud/#public-access) database or from a service in the same environment.
## Under the hood
Databases are [CloudNativePG](https://cloudnative-pg.io) clusters, running two instances on separate machines with replication slots and unsupervised failover between them. That is where the high availability and the continuous archiving come from, and it is a project you can run yourself: an [ejected](https://lucity.cloud/docs/eject) environment keeps its databases as ordinary CloudNativePG resources, with the same backups and the same recovery behavior. The charts in the Metrics tab come from the metrics every instance serves on port 9187, which any Prometheus can scrape after ejecting.
## Next steps
- [Variables](https://lucity.cloud/docs/variables#dynamic-variables) for wiring a database into a service
- [Key-value store](https://lucity.cloud/docs/redis) for caching and queues, which do not belong in PostgreSQL
- [Environments](https://lucity.cloud/docs/environments) for keeping production data away from development
# Object storage
Object storage gives your services somewhere to put files, such as user uploads, generated PDFs and exports.
Buckets are S3-compatible, so the SDK you already use works unchanged. They are private by default, they connect to a service without you copying credentials around, and any of them can be switched to a public URL served from a CDN when the files are meant to be read by everyone.
## Provisioning
On the project canvas, click **Create** and choose **Bucket**. Give it a name between 2 and 16 characters and confirm. It is ready as soon as it appears.
A bucket belongs to one [environment](https://lucity.cloud/docs/environments), so development and production keep separate files. An environment can hold up to 10 buckets.
## Connect
A service reaches a bucket with S3 credentials, which you pass in as [dynamic variables](https://lucity.cloud/docs/variables#dynamic-variables) rather than pasting them anywhere. Open the service's **Variables** tab, add a key, click the link icon in the value field, and pick from the bucket's group.
A bucket exposes five values:
| Variable | What it is |
| ----------------- | --------------------------------------- |
| `bucket` | The bucket name to address in API calls |
| `endpoint` | The S3 endpoint to point your client at |
| `region` | The region the bucket lives in |
| `accessKeyId` | Access key |
| `secretAccessKey` | Secret key |
Name the keys whatever your library expects. The [quickstart](https://lucity.cloud/docs/quickstart) wires them up as `S3_BUCKET`, `S3_ENDPOINT`, `S3_REGION`, `S3_ACCESS_KEY_ID` and `S3_SECRET_ACCESS_KEY`.
The credentials are scoped to your [workspace](https://lucity.cloud/docs/workspaces). One access key covers every bucket in it, so a service holding one bucket's variables can reach the workspace's other buckets too, but nothing outside of it.
The bucket's **Connect** tab shows these credentials, along with ready-made configuration for environment variables, the AWS CLI, rclone, Node and Python.
::note
Use path-style addressing in your client. The snippets on the
**Connect**
tab already set it.
::
## Public read
Buckets are private by default. Objects are reachable only with the credentials, which is what you want for anything belonging to a particular user.
For files meant to be served to everyone, such as avatars, product images and downloads, open the **Connect** tab and switch **Public read** on. The bucket gets a public HTTPS URL served from a CDN, shown on the same tab. Its certificate is issued in the background, so the URL can take a few minutes to start answering.
Switching it back off removes the public URL, and the objects go back to being reachable only with the credentials.
## File explorer
The **Files** tab is a browser for the bucket. It lists objects and folders, walks into prefixes, and lets you create folders, upload (dropping files onto it works), download and delete without a client.
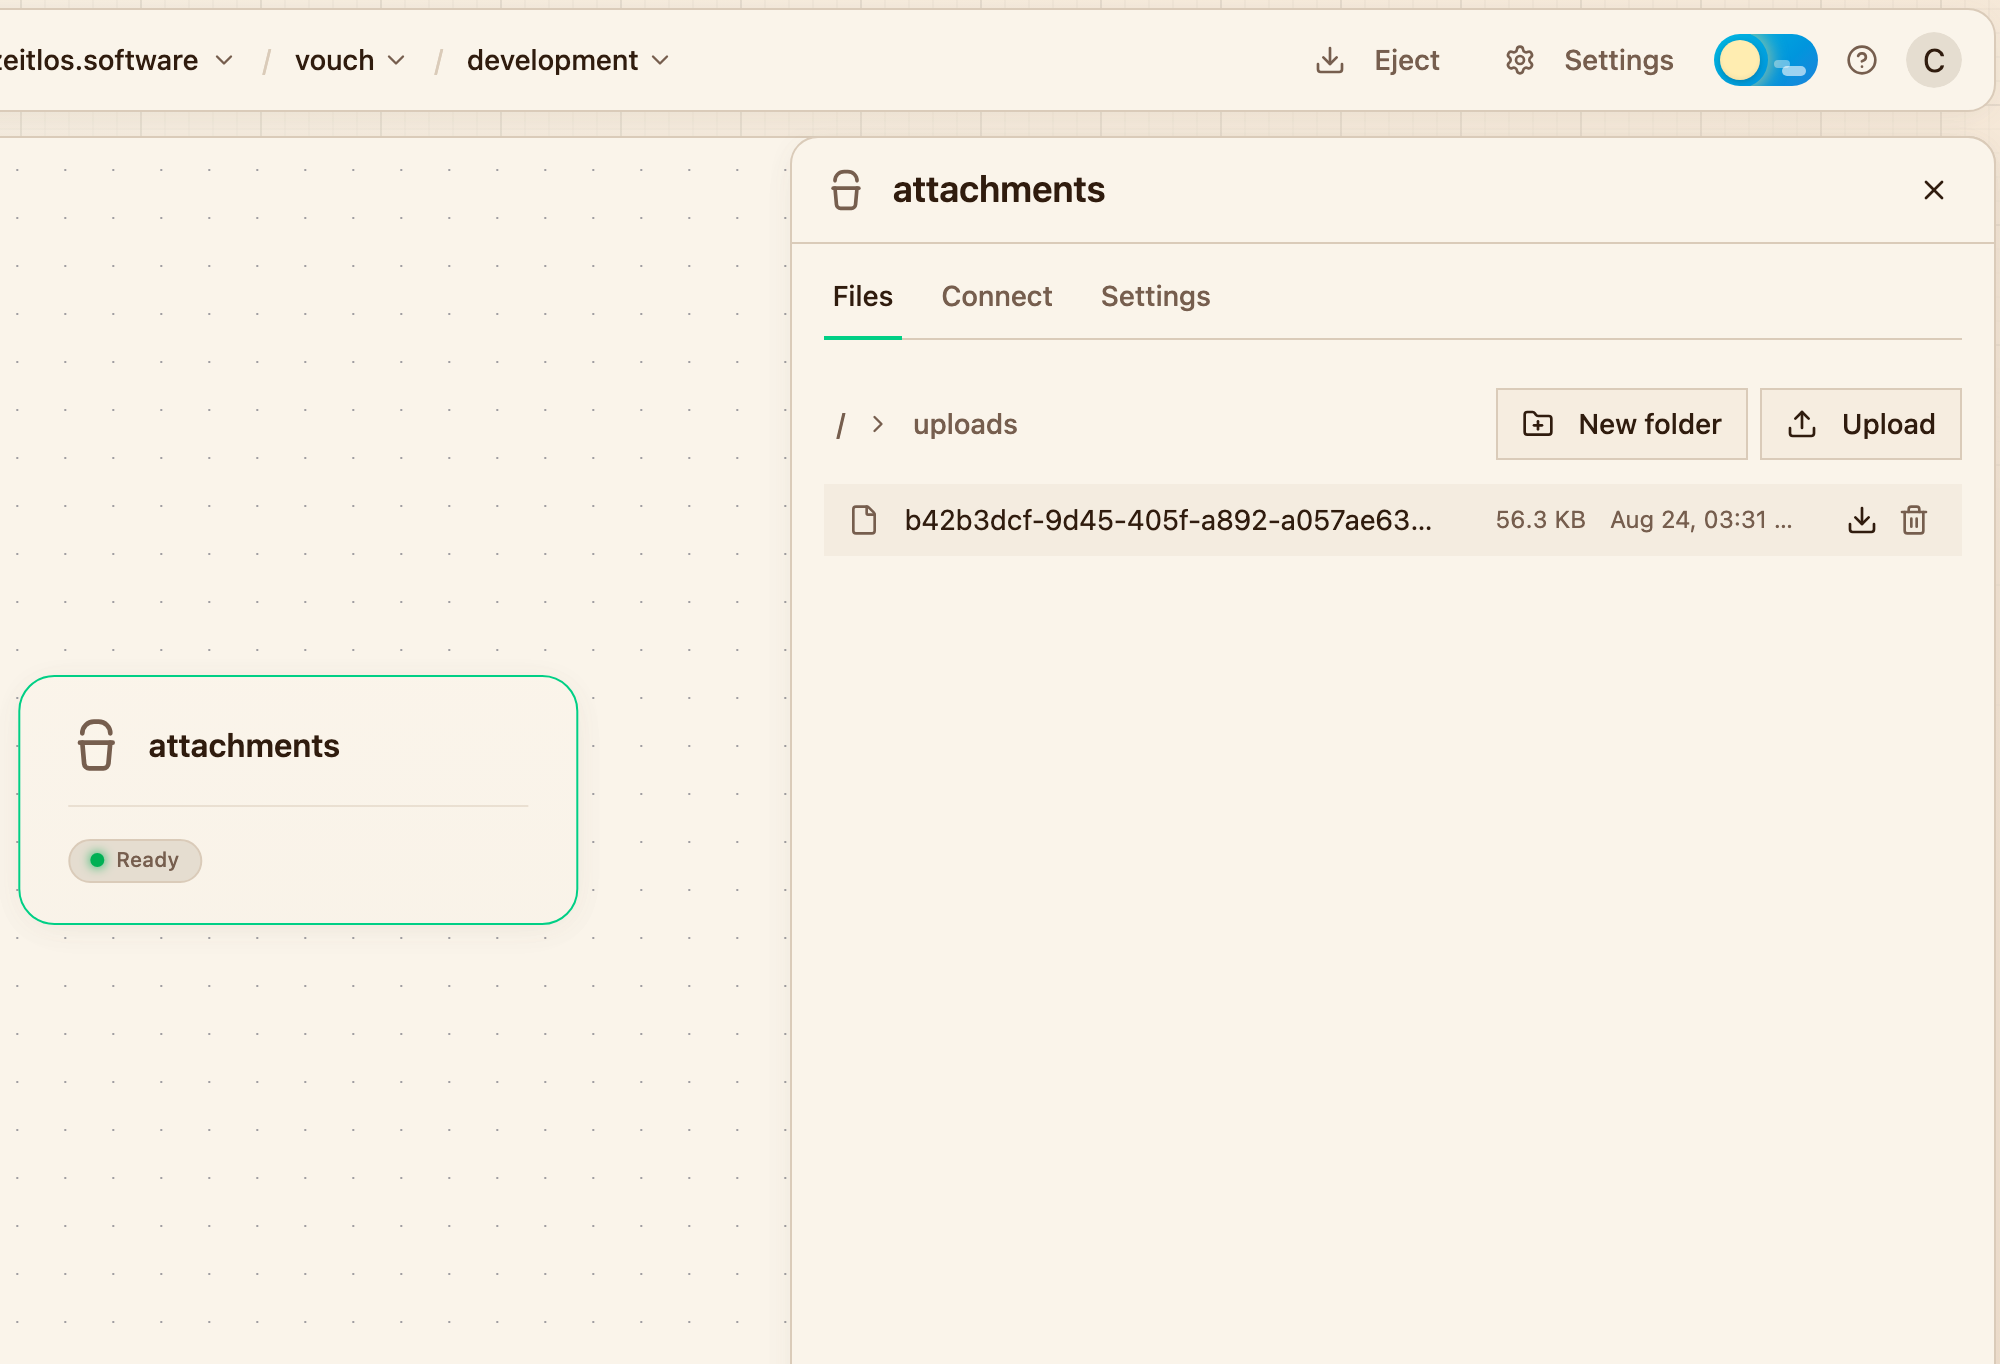
*Browsing a prefix, with upload, download and delete in reach.*
It is meant for checking that an upload landed where you expected, pulling a file out to look at, and seeding a development bucket with a handful of objects. For bulk work, use the credentials with the AWS CLI or rclone.
## Deleting a bucket
Deleting is on the bucket's **Settings** tab, alongside its region, current size and object count. It destroys every object in it and the credentials' access to it, with no restore and no retention window, so a service still consuming its variables will start failing on its next request.
## Under the hood
Buckets are ordinary S3 buckets, currently hosted on OVHcloud object storage in Europe. Running storage hardware is out of scope for Lucity, so the platform provisions buckets from a provider rather than operating its own. The credentials are kept as a Kubernetes Secret in your environment's namespace, which is where dynamic variables read them from, and a public bucket is a CDN pull zone in front of a read-only view of it.
Nothing about that is Lucity-specific: an [ejected](https://lucity.cloud/docs/eject) project keeps its buckets and its credentials exactly as they are. If you would rather host the storage yourself, [Garage](https://garagehq.deuxfleurs.fr) is a good S3-compatible target to move them to.
## Next steps
- [Variables](https://lucity.cloud/docs/variables#dynamic-variables) for wiring a bucket into a service
- [Volumes](https://lucity.cloud/docs/volumes) for when a service needs a real filesystem instead
- [PostgreSQL](https://lucity.cloud/docs/postgres) for the data that does not belong in a bucket
# Volumes
The root filesystem of a Lucity service is ephemeral, and should only be used for temporary files you do not mind losing on the next deploy.
A volume is a disk that outlives the container, and the place to put data you want to keep. It is worth knowing that your application might never need one, because volumes come with limitations that the alternatives do not have. Uploads belong in a [bucket](https://lucity.cloud/docs/object-storage) and data belongs in a [database](https://lucity.cloud/docs/postgres), both of which any number of instances can reach at once. Reach for a volume when something insists on a real filesystem. Typical examples are self-hosted software with a data directory, a search index it rebuilds on disk, or a database you are running yourself.
## Creating and mounting
On the project canvas, click **Create** and choose **Volume**. Give it a name between 2 and 16 characters and a size, and it is ready immediately.
A freshly created volume is unmounted. Open it, and under **Settings** → **Mount**, pick the service and the path to mount it at. The path is where your application expects to find its data, `/var/lib/ghost/content` or `/data` or wherever the software in question insists on. Mounting takes effect immediately and needs no rebuild, like any other [configuration change](https://lucity.cloud/docs/deployments#configuration-changes). It restarts the service so the disk is there when it starts.
Unmounting detaches the disk and restarts the service again. Your data stays on the volume, so you can mount it somewhere else, or back on the same service, later.
A volume and the service it mounts into must be in the same [environment](https://lucity.cloud/docs/environments).
::note
Mounting a volume causes a short downtime, and so does
[every deploy afterwards](https://lucity.cloud/#rollout-downtime)
. The service stops before its replacement starts, because the disk cannot be attached to two instances at once. Unmounting is the exception, since the replacement no longer needs the disk and can take over before the old instance goes.
::
## One volume, one service
A volume is a single disk, and a disk can only be attached to one machine at a time. This means volumes can only be attached to services with a single replica.
That is why we generally recommend keeping your application stateless, writing its state into a [database](https://lucity.cloud/docs/postgres), a [key-value store](https://lucity.cloud/docs/redis) or an [object storage bucket](https://lucity.cloud/docs/object-storage) instead.
## Rollout downtime
Since a volume can only be attached to one instance at a time, services with a mounted volume have a short downtime window on every deploy. The old instance has to release the disk before the new one can claim it, so the service stops and starts again instead of handing over.
Plan for it the way you would plan a restart. It is usually a few seconds, and it is the price of keeping state on a disk rather than in a database or a bucket.
## Size
Volumes run from 10 GB up to 1 TB. You can add space at any time under **Settings** → **Storage**, and the disk grows in place while the service keeps running.
Storage can never be made smaller. Moving to a smaller disk means creating a second volume, copying the data across, and pointing the service at the new one.
The **Usage** tab charts how much of the volume is actually in use over time, which is what to check before deciding you need more.
## File ownership
For [services](https://lucity.cloud/docs/services) created from an image, the run-as user set under **Settings** → **Run as user** also becomes the owner of the mounted volume. That is usually what you need for an image that runs as a non-root user and expects to write to its own data directory.
## What's not there yet
Volumes are not backed up. There are no snapshots and no retention window, and deleting a volume deletes its contents for good. If a volume holds something you cannot lose, copy it somewhere else on a schedule: a periodic dump into a [bucket](https://lucity.cloud/docs/object-storage) from inside the service is the usual answer, and it produces something you can actually restore from.
## Under the hood
A volume is a PersistentVolumeClaim in your environment's namespace, mounted into the service's pod at the path you chose. That is why the constraints look the way they do: a single-writer disk, attached to one pod, expandable but not shrinkable. An [ejected](https://lucity.cloud/docs/eject) project keeps its volumes exactly as they are.
## Next steps
- [Services](https://lucity.cloud/docs/services#volume-mounts) for what mounting a volume does to a service
- [Object storage](https://lucity.cloud/docs/object-storage) for files that do not need a filesystem
- [PostgreSQL](https://lucity.cloud/docs/postgres) for data that belongs in a database
# Key-value store
A key-value store is the fast, in-memory place your services reach for when a database would be overkill. Cached responses, user sessions, rate-limit counters, a queue for background jobs.
Lucity gives you a Redis®-compatible store, so every Redis client and library you already use works against it unchanged.
## Provisioning
On the project canvas, click **Create** and choose **Redis**. Give it a name between 2 and 16 characters and confirm.
A store belongs to one [environment](https://lucity.cloud/docs/environments), so development and production each get their own with separate data and separate passwords.
## Connect
Connect a service with a [dynamic variable](https://lucity.cloud/docs/variables#dynamic-variables). Open the service's **Variables** tab, click the link icon in the value field, and pick from the store's group. It exposes four values:
| Variable | What it is |
| ---------- | ------------------------------------------------------------------- |
| `uri` | The complete connection URL, which is usually the only one you need |
| `host` | The private hostname |
| `port` | `6379` |
| `password` | The generated password |
Most libraries take the URL directly, so linking `uri` to `REDIS_URL` is usually the whole job.
The store's **Connect** tab shows the same values if you need to read them. The store is reachable only from services in its own environment and there is no built-in way to expose it to the internet.
## What it is good for
- **Caching.** Expensive query results, rendered fragments, and responses from APIs that are slower than you would like.
- **Sessions.** Anything held in a service's memory belongs to one instance and disappears when it rolls. A session store here survives deploys and works across [replicas](https://lucity.cloud/docs/services#replicas-and-autoscaling).
- **Rate limiting and counters.** Atomic increments with expiry, which is exactly what the data structures are for.
- **Job queues.** BullMQ, Sidekiq, Celery, RQ and the rest all run on a Redis-compatible store. Point the worker and the producer at the same one.
## Persistence
Writes are appended to disk as they happen, so the data survives a restart or a redeploy. Treat it as durable enough for sessions and queues, and not as the place for anything you cannot lose. It is a single instance with no replica and no backups, so a lost store is a lost store. Anything you would be upset to lose belongs in [PostgreSQL](https://lucity.cloud/docs/postgres).
Each store gets 1 GB of disk. Set your expiries and your eviction accordingly, and remember that a queue with no consumer keeps growing.
## Under the hood
Stores run [Valkey](https://valkey.io), the open-source fork of Redis, as a single instance with append-only persistence and password authentication. The Redis protocol is the interface, which is why your existing clients neither know nor care about the difference. An [ejected](https://lucity.cloud/docs/eject) project keeps the store as a plain StatefulSet.
::note
Redis is a registered trademark of Redis Ltd. Any rights therein are reserved to Redis Ltd. Any use by Lucity is for referential purposes only, and does not indicate any sponsorship, endorsement or affiliation between Redis Ltd. and Lucity.
::
## Next steps
- [Variables](https://lucity.cloud/docs/variables#dynamic-variables) for wiring a store into a service
- [PostgreSQL](https://lucity.cloud/docs/postgres) for data that has to survive
- [Services](https://lucity.cloud/docs/services#replicas-and-autoscaling) for why shared state matters once you run more than one instance
# Workspaces
Workspaces are how organizations are represented within Lucity. One workspace can stand for a whole company, or for a team, a client or a department once an organization is large enough to want them kept apart.
A workspace holds all your projects and everything inside them. Its members have access to every project it contains. Each workspace has its own plan and is invoiced separately.
Signing up gives you a personal workspace to start from and you can always create more.
## Members and roles
Workspace members have one of two roles:
| Role | What it can do |
| ---------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Member** | Everything to do with building and running software: create projects and environments, deploy services, provision databases and buckets, edit variables, add domains. |
| **Admin** | All of that, plus the workspace itself: inviting and removing people, changing roles, editing the workspace name, managing the subscription and API tokens, and deleting the workspace. |
Under **Settings** → **Members**, an admin can invite members by email and configure their role. The same interface can also be used to change the role of an existing member or remove them from the workspace. Removing a member revokes their access immediately, while the projects and services they created are untouched within the workspace.
## API tokens
Under **Settings** → **API tokens**, an admin can create tokens for interacting with the [API](https://lucity.cloud/docs/api).
An API token carries a role in the same way a member does, so a token created as a member can do member things and no more. The token value is shown once, when you create it, and never again. Revoking one takes effect immediately.
::note
A third role,
**deployer**
, exists for
[keyless GitHub Actions deploys](https://lucity.cloud/docs/deployments#triggering-a-deployment)
and cannot be assigned to a person. It can only deploy a service and edit that service's variables.
::
## Switching workspaces
The workspace picker sits at the far left of the header, before the project and environment. Switching moves the whole dashboard, so the projects you see, the resources you can reach and the bill you are looking at all belong to the workspace you have selected.
*Every workspace you belong to, and a way to start another.*
## Personal workspaces
Signing up creates a personal workspace for you, and it cannot be deleted. It is the natural home for experiments and hobby projects, the things that do not belong to a team.
When work does belong to a team, create a workspace for the team rather than growing your personal one into a shared space.
## Deleting a workspace
A workspace can only be deleted once it is empty, so you have to delete each project within it first. See [deleting a project](https://lucity.cloud/docs/projects#deleting-a-project) for what that involves.
Once no projects are left, **Settings** → **Danger Zone** removes the workspace, its members and its subscription.
## Next steps
- [Projects](https://lucity.cloud/docs/projects) for what lives inside a workspace
- [Environments](https://lucity.cloud/docs/environments) for how a project is split up
- [Billing](https://lucity.cloud/docs/billing) for what a workspace costs
# Projects
A project is a group of resources under one name, together with the [environments](https://lucity.cloud/docs/environments) they run in. Services, databases, key-value stores, buckets and volumes all live inside one.
A project usually represents one application or system. A [workspace](https://lucity.cloud/docs/workspaces) holds all your projects.
Every project starts with a development environment and can have as many more as you need.
## Creating a project
Click **New** on the projects page and the create palette opens with three ways to start.
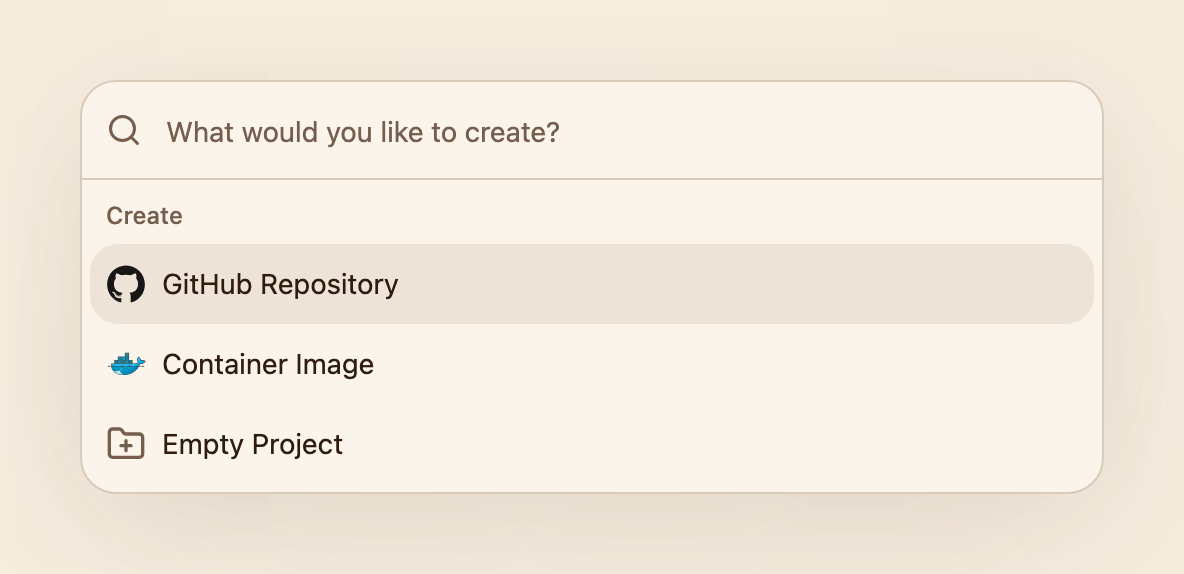
*Every project starts here, from source, from an image or from nothing at all.*
**From a GitHub repository** is the usual one. Pick the account and the repository, and Lucity inspects it, works out what it is, and proposes a project and a service to go with it. The first build starts immediately. This is the path the [quickstart](https://lucity.cloud/docs/quickstart) walks through.
**From a container image** creates the project around a service built elsewhere, whether that is software you are hosting or an image you publish yourself.
**Empty** creates the project and its development environment with nothing in them, ready for you to add services and resources yourself.
A project has a display name of up to 128 characters and an identifier of 2 to 16 lowercase letters, digits and hyphens, derived from the name unless you set it yourself. The identifier is what appears in URLs, hostnames and logs. Neither can be changed afterwards.
## The canvas
Opening a project drops you on the canvas for the current environment. Every resource in that environment is a node: [services](https://lucity.cloud/docs/services), [databases](https://lucity.cloud/docs/postgres), [key-value stores](https://lucity.cloud/docs/redis), [buckets](https://lucity.cloud/docs/object-storage) and [volumes](https://lucity.cloud/docs/volumes), each showing its name and current state.
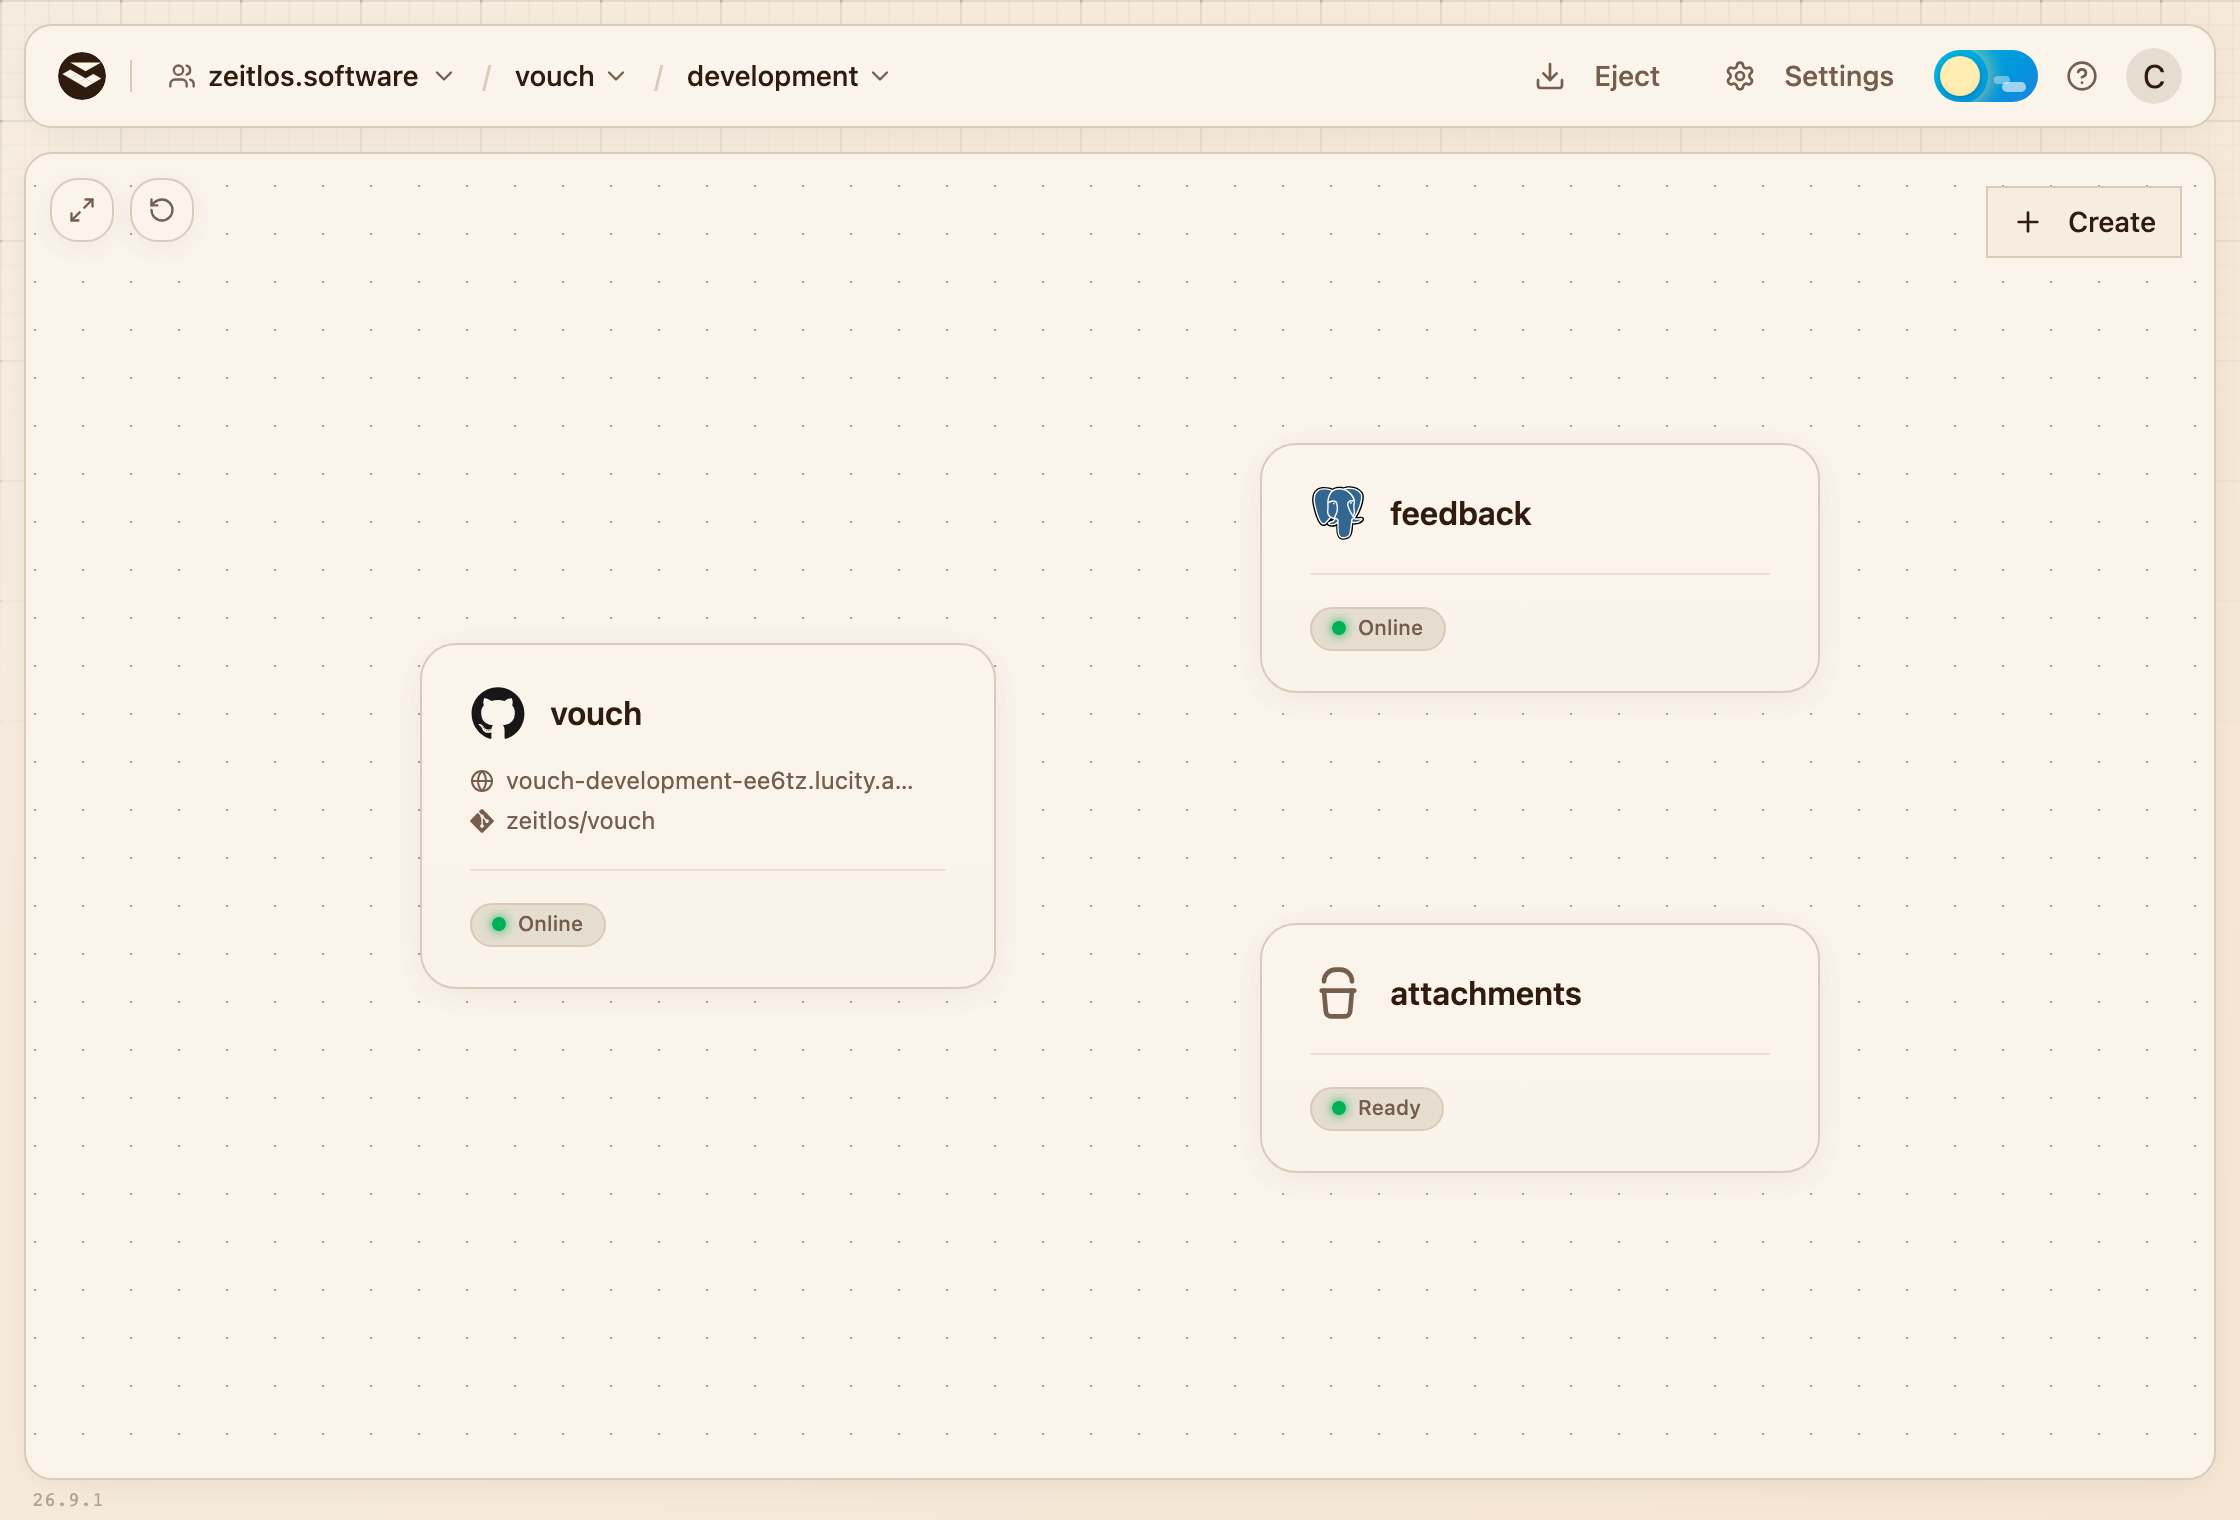
*One environment on the canvas. Create sits in the top right, the reset button in the top left.*
Clicking a node opens its panel: deployments and logs for a service, tables and backups for a database, files for a bucket. **Create** in the top right adds a new resource to the environment.
You can drag nodes around to lay the canvas out the way you think about the system. The arrangement is saved in your browser, so your teammates keep their own, and the reset button in the top left puts every node back where it started.
The canvas shows one environment at a time. Switching environment in the header swaps the whole canvas, so production shows its own separate copy of everything.
## Settings
**Settings** on a project covers what applies across it rather than to one resource. **General** holds the project name and identifier, **Environments** lists them and creates and deletes them (see [environments](https://lucity.cloud/docs/environments)), and **Variables** holds the [shared variables](https://lucity.cloud/docs/variables#shared-variables) for the environment you are looking at.
*The name and identifier are fixed, and deleting the project sits right below them.*
## Deleting a project
Deleting is under **Settings**, at the bottom of **General**. Projects delete from the inside out: a project can only be removed once all of its environments are empty, so every service, database, key-value store, bucket and volume has to go first. Until then the delete is refused and names what is still in the way.
Once the environments are empty, deleting the project removes them and the project along with it.
## Under the hood
A project is a naming and labeling convention rather than a resource of its own. Each of its environments is a Kubernetes namespace carrying the project in its name and in its `lucity.dev/*` labels, which is why the identifier is fixed at creation and why an [ejected](https://lucity.cloud/docs/eject) project is simply those namespaces and the Helm releases inside them.
## Next steps
- [Environments](https://lucity.cloud/docs/environments) for how a project is divided
- [Services](https://lucity.cloud/docs/services) for what runs inside one
# Environments
An environment is one copy of a project, with its own services, databases, key-value stores, buckets and volumes. Every project starts with `development`, and you add environments such as `staging` or `production` as you need them.
Environments are separate from each other. Each has its own configuration and its own domains, and nothing you change in one reaches another.
## Switching environments
The environment switcher sits in the header, next to the project name. It lists every environment in the project along with its [tier](https://lucity.cloud/#tiers), and the canvas shows whichever one you pick.
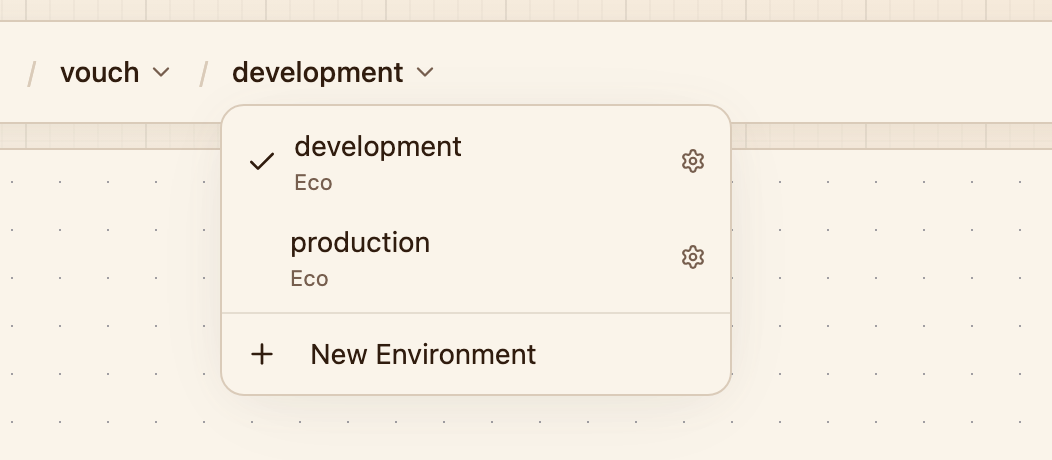
*Every environment in the project. The gear next to one opens its settings.*
## Creating an environment
Choose **New Environment** in the switcher, then give it a name and a [tier](https://lucity.cloud/#tiers). Names are 2 to 16 lowercase letters, digits and hyphens. They appear in URLs and platform domains, so they can't be changed later.
A new environment starts empty. Add its services and resources the same way you did in development. Each service tracks its own branch, so production can build from `main` while development follows whatever you are working on.
Services in `development` deploy on every push by default. In any other environment, auto-deploy starts switched off, so those services only change when you deploy them from the dashboard, the [CLI](https://lucity.cloud/docs/cli) or CI. You can turn it on for a service under **Settings** → **Source**.
## What stays separate
**The private network.** Services reach each other and the environment's databases and key-value stores over a private network that ends at the environment. A service in development can't reach anything in production that way. It would have to go through a public domain, like any other client on the internet.
**Configuration.** [Variables](https://lucity.cloud/docs/variables) belong to a service and shared variables to an environment, so every environment is configured on its own. A dynamic variable can only point at a resource in its own environment.
**Domains.** Every service gets its own platform domain in each environment, and [custom domains](https://lucity.cloud/docs/domains) are added per service, so production gets its own.
What environments share is access. Everyone in the workspace can see and change every environment, and there are no per-environment permissions.
## Tiers
Every environment has a tier, which decides how its services and databases get CPU and memory.
| Tier | What it does | Suited for |
| -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------ |
| **Eco** | Services share capacity and can burst beyond what is reserved for them. You pay for what they actually use, and performance can vary under load. | Development, staging and side projects |
| **Production** | The full CPU and memory of every service is reserved for it. | Production workloads with predictable load |
New environments start on Eco. To change the tier, open the project's **Settings** → **Environments**, expand the environment, pick a tier and click **Save tier**. A service or database picks up the new tier the next time it is created or its resources change. See [billing](https://lucity.cloud/docs/billing) for what each tier costs.
*Each environment's tier, under the project settings.*
## Deleting an environment
Open the project's **Settings** → **Environments** and click the trash icon next to the environment. It has to be empty first, so remove its services, databases, key-value stores, buckets and volumes beforehand.
A project always keeps at least one environment, so the last one can't be deleted on its own. To remove that too, [delete the project](https://lucity.cloud/docs/projects#deleting-a-project).
## Resource quotas
Every environment has a budget that covers everything inside it: services, databases, key-value stores and volumes together.
| Resource | Budget per environment |
| -------- | ---------------------- |
| CPU | 32 vCPU |
| Memory | 64 GB |
| Storage | 4 TB |
That is room for a lot of application, and most projects never come close. When an environment does run out, new instances stop being placed and the deployment that tried to start them fails with a quota error.
The budget is not self-service. To have it raised, email with the workspace, the project and the environment, and roughly what you need it to be.
## Next steps
- [Projects](https://lucity.cloud/docs/projects) for what holds the environments
- [Variables](https://lucity.cloud/docs/variables) for configuring each environment
- [Deployments](https://lucity.cloud/docs/deployments) for getting code into an environment
# Eject
Ejecting downloads a project as a standard Helm chart with one values file per environment. Install it with `helm` on a Kubernetes cluster of your own and the same services, databases, key-value stores and volumes come up there, configured the way they run on Lucity, without any Lucity component involved.
It is a copy of the configuration, not a migration. Your data and the images Lucity built for you do not come along, and moving them is manual work, as the [limitations](https://lucity.cloud/#limitations) below spell out.
Ejecting changes nothing on Lucity. The project keeps running, so you can eject to keep a copy, to try out your own cluster first, or to move for good.
## Downloading a project
Open the project, click **Eject** in the header, then **Download .zip**. The archive covers every environment in the project that has something in it.
*Eject sits in the header of every project, next to Settings.*
::warning
The archive holds your variables in plain text, secrets included, along with the passwords of your key-value stores. Keep it where you would keep a password, and out of public repositories.
::
## What's inside
```text
shop-ejected/
├── README.md
├── build.sh
├── chart/
└── values/
├── development.yaml
└── production.yaml
```
`chart/` is the Helm chart every Lucity environment is deployed with. Each file in `values/` describes one environment as it runs right now, from its services with their images, variables, replicas, resources and domains to its databases, key-value stores and volumes. `build.sh` rebuilds the images of services built from source, and the README has the install command and links back to this page.
## Limitations
The archive covers configuration only. The rest is manual work:
- **Data is not included.** Databases, key-value stores and volumes come up empty on your cluster, and bucket files stay in their buckets. You copy all of it yourself, as described under [move your data](https://lucity.cloud/#move-your-data).
- **Volume contents have no export.** Lucity has no way to download a volume, so its files have to come out through your own service, for example by copying them into a bucket.
- **Images built from source have to be rebuilt.** They sit in the platform's registry, which nothing outside Lucity can reach. The archive's build script rebuilds them, on a machine of yours with Docker.
- **Moving means downtime.** There is no live migration. Writes have to stop while the data is copied, and custom domains wait a minute or two for new certificates after the DNS switch.
- **Credentials change.** Databases get new passwords on your cluster, and bucket credentials are not in the archive. Services that read them through variables pick up the new ones, but anything holding a copied connection string needs updating.
- **It is a snapshot.** The chart and values stay as they were when you downloaded them. Changes you make on Lucity afterwards need a fresh eject.
## Installing on your own cluster
The steps below install `production` of a project called `shop`. Repeat them for every environment you want to run, each in its own namespace.
::steps{level="3"}
### Prerequisites
What to install up front depends on what the project uses.
| If the project has | The cluster needs |
| -------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Services | Kubernetes 1.33 or newer, on nodes that support user namespaces (Linux 6.3+, containerd 2.0+ or CRI-O) |
| Databases, key-value stores or volumes | A default StorageClass |
| PostgreSQL databases | The [CloudNativePG](https://cloudnative-pg.io) operator |
| Domains | A [Gateway API](https://gateway-api.sigs.k8s.io) implementation and a Gateway reachable from the internet |
| Custom domains | ListenerSet support on that Gateway, and [cert-manager](https://cert-manager.io) 1.20+ with an HTTP-01 ClusterIssuer |
| Autoscaling | [metrics-server](https://github.com/kubernetes-sigs/metrics-server) |
| A database with internet access | [Traefik](https://traefik.io) with an entrypoint named `postgres` that receives the client's real address (PROXY protocol behind a load balancer), or delete `publicAccess` from the database's values |
Every service runs in its own user namespace, so root inside a container is an unprivileged user on the node. That is where the node requirements come from.
Each custom domain brings its own listener and certificate. Your Gateway has to accept listeners from the environment's namespace, which is its `allowedListeners` setting, and cert-manager needs its [Gateway API support](https://cert-manager.io/docs/usage/gateway/) switched on to answer the HTTP-01 challenge. If you would rather terminate TLS on your own Gateway listeners, delete a domain's `listenerSet` block and its route attaches to the Gateway directly.
### Rebuild your images
Services created from an image, such as Ghost from Docker Hub, keep pulling it from the same public registry and need no changes.
Services built from a repository point at the platform's own registry, which only Lucity's cluster can reach. `build.sh` builds them again and pushes them to a registry of yours. Log in to that registry with `docker login` first, then run:
```bash
./build.sh production registry.example.com/shop
```
For every service in the environment that is built from a repository, the script clones the repository at the commit in the service's image `tag` and builds it with [Railpack](https://railpack.com), in the version Lucity uses and with the service's variables. It pushes the result as `registry.example.com/shop/:` and points the service's `image` in `values/production.yaml` at it. Add service names after the registry to build only those.
The script needs Docker, git and [yq](https://github.com/mikefarah/yq), plus your own git credentials for private repositories. Images are built for `linux/amd64` as on Lucity, which is emulated and slower on an Apple Silicon Mac. For an arm64 cluster, set `BUILD_PLATFORM=linux/arm64`.
If you would rather build another way, set the service's `image.repository` and `image.tag` to your image and delete its `image.digest`.
### Update the values
A few values name things that only exist on Lucity. Change them before installing:
- **`gateway`** is the Gateway your routes attach to. Set its `name` and `namespace` to yours.
- **Platform domains**, the hostnames Lucity generated for your services, keep pointing at Lucity. Remove them from the service's `domains`, or replace them with hostnames of your own. Variables that contain one, such as a frontend's API URL, need the new hostname as well.
- **`issuerRef`** under each custom domain names the ClusterIssuer for its certificate. Use the name of yours.
- **`imagePullSecrets`** names Lucity's registry credentials. Put the name of your own pull secret there, or remove it if your images are public.
### Install the chart
A service connected to a bucket reads the bucket's variables from a secret named `lucity-bucket-`, which is not part of the chart. Create it in the environment's namespace before installing, either with the bucket's current credentials from its **Connect** tab to keep using the bucket where it is, or with those of the storage you are moving to:
```bash
kubectl create namespace shop-production
kubectl create secret generic lucity-bucket-uploads -n shop-production \
--from-literal=bucket= \
--from-literal=endpoint= \
--from-literal=region= \
--from-literal=accessKeyId= \
--from-literal=secretAccessKey=
```
The pull secret for a private registry goes into the same namespace. Then install the environment:
```bash
helm upgrade --install lucity-app ./chart \
-f values/production.yaml \
-n shop-production --create-namespace
```
The release has to be called `lucity-app`. Every resource name derives from it, and the values refer to some of them by name, such as the secrets your variables are read from and the private hostnames services use to reach each other.
From here on the values file is your configuration. Edit it and run the same command to roll out a change.
### Move your data
Databases, key-value stores and volumes come up empty on the new cluster. Copy their contents once nothing writes to the old ones anymore, or whatever is written in between stays behind.
**PostgreSQL.** Switch on [internet access](https://lucity.cloud/docs/postgres#public-access) for the database and dump it with the connection string from its **Connect** tab. Then restore the dump on the new database's first instance, whose pod is named `lucity-app-pg--1`:
```bash
pg_dump --format=custom "" > main.dump
kubectl exec -i -n shop-production lucity-app-pg-main-1 -- \
pg_restore --dbname=app < main.dump
```
**Buckets.** If the files are moving too, copy them with any S3 tool. The bucket's **Connect** tab has a ready-made rclone configuration.
**Volumes.** With no download to fall back on, copy the files out from inside the service, for example into a bucket, and back in on the other side.
**Key-value stores.** Caches and sessions can start over. Anything you need to keep has to be copied from inside a service.
### Switch over
Once everything runs, point your custom domains' DNS at your Gateway. Their certificates can only be issued once the records point at your cluster, so HTTPS takes a minute or two to come up on the new side.
When nothing on Lucity is needed anymore, [delete the project](https://lucity.cloud/docs/projects#deleting-a-project). Its buckets go with it, so move any bucket you are still using first.
::
## What you take over
The archive is the deployment, not the platform around it. On your own cluster these are yours to run:
- **Builds and deploys.** A push no longer deploys anything. Build and run `helm upgrade` from your CI instead.
- **Database backups.** Backups and point-in-time recovery are not part of the export. Configure [backups in CloudNativePG](https://cloudnative-pg.io/docs/1.30/backup) to get them back.
- **Separation between environments.** Lucity keeps each environment on its own network and within a resource budget, and both live outside the chart. Add network policies and quotas of your own if environments share a cluster.
- **Logs, metrics and the dashboard.** Bring the observability tools you already like.
## Next steps
- [Self-hosting](https://lucity.cloud/docs/self-hosting) for running the whole platform on your own infrastructure instead
- [PostgreSQL](https://lucity.cloud/docs/postgres#public-access) for reaching a database from outside Lucity
- [Builds](https://lucity.cloud/docs/builds) for how Lucity turns a repository into an image
# API
Everything the dashboard and the [CLI](https://lucity.cloud/docs/cli) do goes through one GraphQL API at `https://lucity.cloud/graphql`, which you can call yourself. The [playground](https://lucity.cloud/#playground) documents every query, mutation and type.
## Authentication
Every request carries an access token as a bearer token. The [CLI](https://lucity.cloud/docs/cli) prints one for your session and the active workspace:
```bash [Request]
curl https://lucity.cloud/graphql \
-H "Authorization: Bearer $(lucity token)" \
-H "Content-Type: application/json" \
-d '{"query": "{ project(id: \"zeitlos-software/vouch\") { name environments { name } } }"}'
```
```json [Response]
{
"data": {
"project": {
"name": "vouch",
"environments": [
{
"name": "development"
},
{
"name": "production"
}
]
}
}
}
```
For automation, use a workspace [API token](https://lucity.cloud/docs/workspaces#api-tokens). The API doesn't accept the `lucity_…` value itself, so let the CLI exchange it. With the token in `LUCITY_API_TOKEN`, `lucity token` prints an access token that carries the API token's role:
```bash [Request]
export LUCITY_API_TOKEN=lucity_…
curl https://lucity.cloud/graphql \
-H "Authorization: Bearer $(lucity token)" \
-H "Content-Type: application/json" \
-d '{"query": "{ projects { id } }"}'
```
Access tokens are short-lived, so fetch a new one for every run instead of storing it. A token also decides the workspace, and every request runs against the workspace its token belongs to.
## Playground
[lucity.cloud/playground](https://lucity.cloud/playground) is an interactive editor for the API, with autocomplete as you type. The book icon in its sidebar opens the documentation, which describes every query, mutation and type, so it doubles as the API reference.
To run queries against your workspace, add your token in the **Headers** tab as `{"Authorization": "Bearer …"}`.
## Ids
Resources are addressed by ids that start with the workspace, and each kind of id has its own scalar type:
| Scalar | Format | Example |
| --------------- | ---------------------------------------- | -------------------------------------------- |
| `ProjectID` | `workspace/project` | `zeitlos-software/vouch` |
| `EnvironmentID` | `workspace/project/environment` | `zeitlos-software/vouch/production` |
| `ServiceID` | `workspace/project/environment/service` | `zeitlos-software/vouch/production/vouch` |
| `DatabaseID` | `workspace/project/environment/database` | `zeitlos-software/vouch/production/feedback` |
Key-value stores, buckets and volumes follow the same pattern as databases. Unlike the CLI, the API always takes the full id.
## Roles
Every token carries a role, and it can only call the operations that role allows:
| Role | Who has it |
| ------------ | ------------------------------------------------------------------------------- |
| **Admin** | Workspace admins, and API tokens created with the admin role |
| **Member** | Workspace members, and API tokens created with the member role |
| **Deployer** | Keyless [GitHub Actions](https://lucity.cloud/docs/cli#github-actions) sessions |
[Members and roles](https://lucity.cloud/docs/workspaces#members-and-roles) describes what each role can do.
## Errors
A failed operation still answers with HTTP 200. The reason is in the `errors` list, next to whatever data could be returned:
```json [Response]
{
"errors": [
{
"message": "project with id \"zeitlos-software/nope\" not found",
"path": [
"project"
],
"locations": [
{
"line": 1,
"column": 3
}
]
}
],
"data": null
}
```
## Live logs
Logs stream as GraphQL subscriptions over a WebSocket at `wss://lucity.cloud/graphql`, using the `graphql-transport-ws` protocol. Put the token in the `connection_init` payload:
```json
{ "type": "connection_init", "payload": { "Authorization": "Bearer " } }
```
Any client that speaks the protocol works, such as [graphql-ws](https://github.com/enisdenjo/graphql-ws) for JavaScript.
# CLI
The `lucity` command line tool deploys services, checks on rollouts, and manages variables and databases, from your terminal or a CI pipeline. It also runs the MCP server that gives AI agents access to your projects, which [Claude plugin & MCP](https://lucity.cloud/docs/claude-plugin) covers.
## Install
::tabs
:::tabs-item{label="macOS"}
Install it with [Homebrew](https://brew.sh):
```bash
brew install --cask zeitlos/tap/lucity
```
:::
:::tabs-item{label="Linux"}
Download the latest release and put the binary on your `PATH`:
```bash
VERSION=$(curl -fsSL https://api.github.com/repos/zeitlos/lucity/releases/latest | sed -n 's/.*"tag_name": *"v\([^"]*\)".*/\1/p')
curl -fsSL "https://github.com/zeitlos/lucity/releases/download/v$VERSION/lucity_${VERSION}_linux_amd64.tar.gz" | tar xz
sudo install lucity /usr/local/bin/lucity
```
On an ARM machine, use `arm64` in place of `amd64`.
:::
::
On Windows, use the Linux build inside WSL. To check that it works:
```bash
lucity version
```
```text
lucity 26.9.1
```
## Update
On macOS:
```bash
brew upgrade --cask lucity
```
On Linux, run the [install](https://lucity.cloud/#install) commands again, which always fetch the latest release.
## Sign in
```bash
lucity login
```
Your browser opens, and you sign in with GitHub just like in the dashboard. Signing in also picks an active workspace. `lucity account` lists the workspaces you belong to, and `lucity workspace ` switches to another one.
## Ids
::note
The examples on this page use the Vouch app from the
[quickstart](https://lucity.cloud/docs/quickstart)
, which is a project called
`vouch`
with a
`vouch`
service and a
`feedback`
database in its development environment.
::
Commands address environments, services and databases by an id that starts with the workspace:
| Resource | Id | Example |
| ----------- | ---------------------------------------- | --------------------------------------------- |
| Environment | `workspace/project/environment` | `zeitlos-software/vouch/development` |
| Service | `workspace/project/environment/service` | `zeitlos-software/vouch/development/vouch` |
| Database | `workspace/project/environment/database` | `zeitlos-software/vouch/development/feedback` |
The project part is the project's identifier, not its display name. You can leave out the workspace, and the CLI fills in the active one, so with `zeitlos-software` active, `vouch/development/vouch` is the same service:
```bash
lucity status vouch/development/vouch
```
```text
Service zeitlos-software/vouch/development/vouch: HEALTHY
Deployment zeitlos-software/vouch/development/vouch/56bc5cdfc5: ACTIVE
Replicas: 1/1 ready
Source: 7b32d9e6
Rollout: READY
```
## Deploy from CI
A pipeline deploys with the same `lucity deploy` command you use in a terminal. With `--wait`, the job waits until the release is live and fails when the deploy does, so the steps after it only run once the new version is up.
### GitHub Actions
GitHub Actions can deploy without any secret. Turn on **CI Deploys** for the service under **Settings** → **Source**, and give the job the `id-token: write` permission:
```yaml
name: Deploy
on:
push:
branches: [main]
jobs:
deploy:
runs-on: ubuntu-latest
permissions:
id-token: write
steps:
- name: Install the Lucity CLI
env:
GH_TOKEN: ${{ github.token }}
run: |
gh release download --repo zeitlos/lucity \
--pattern 'lucity_*_linux_amd64.tar.gz' --output - | tar xz
sudo install lucity /usr/local/bin/lucity
- name: Deploy
run: lucity deploy vouch/development/vouch --ref "$GITHUB_SHA" --wait
```
The job can then deploy the services that build from its repository and have CI Deploys turned on, and read and set their variables. For anything else, such as database commands, use an [API token](https://lucity.cloud/#other-ci-systems).
::note
Any workflow in the repository can deploy these services, from any branch. Treat write access to the repository as deploy access.
::
### Other CI systems
Use a workspace API token. An admin creates one under **Workspace settings** → **API tokens**, with the role **Member** or **Admin** (see [workspaces](https://lucity.cloud/docs/workspaces#api-tokens)). The token is only shown once, so store it in your CI system's secrets as `LUCITY_API_TOKEN`, and the CLI picks it up from there:
```bash
lucity deploy vouch/development/vouch --ref "$CI_COMMIT_SHA" --wait
```
The token also determines the workspace, so there's nothing else to configure.
## Reference
Every command, flag and environment variable of the CLI.
```text
lucity [arguments]
```
| Command | Description |
| ------------------------------------------------------------ | ---------------------------------------------------------------------- |
| [`login [--api ]`](https://lucity.cloud/#login) | Sign in through your browser |
| [`logout`](https://lucity.cloud/#logout) | Discard the stored session |
| [`account`](https://lucity.cloud/#account) | Show who you are signed in as, and your workspaces |
| [`workspace []`](https://lucity.cloud/#workspace) | Show or switch the active workspace |
| [`deploy `](https://lucity.cloud/#deploy) | Build and roll out a service |
| [`status `](https://lucity.cloud/#status) | Show the latest rollout status of a service |
| [`vars `](https://lucity.cloud/#vars) | Manage service variables (list, available, set) |
| [`db `](https://lucity.cloud/#db) | Manage databases (create, list, credentials, expose, unexpose, delete) |
| [`token [--account]`](https://lucity.cloud/#token) | Print a bearer token for scripting |
| [`mcp`](https://lucity.cloud/#mcp) | Serve the Lucity MCP server on stdio |
| [`version`](https://lucity.cloud/#version) | Print the CLI version |
Run `lucity help ` for the details of a command.
| Variable | Description |
| ------------------- | ---------------------------------------------------------------------------------------- |
| `LUCITY_API_URL` | Platform URL, in place of the one you signed in to |
| `LUCITY_WORKSPACE` | Workspace to use, in place of the active one |
| `LUCITY_API_TOKEN` | Workspace API token, used in place of the stored session |
| `LUCITY_CONFIG_DIR` | Directory holding the session (default: `$XDG_CONFIG_HOME/lucity` or `~/.config/lucity`) |
### `login`
Sign in through your browser.
```text
lucity login [--api ]
```
| Flag | Description |
| ------------- | --------------------------------------------------------------------------------------------------------------------------- |
| `--api ` | Platform to sign in to. Defaults to `LUCITY_API_URL`, then the platform you last signed in to, then . |
Opens your browser to sign in with GitHub and stores the session in the config directory. Only a refresh token is written to disk, and access tokens are fetched as commands need them.
The browser hands the session back to a listener on 127.0.0.1, on port 8765, 8766 or 8767, so sign in on the machine your browser runs on. To sign in on a remote machine, forward the port with `ssh -L 8765:127.0.0.1:8765 `, or use an API token instead.
```bash [Examples]
lucity login
lucity login --api https://paas.example.com
```
### `logout`
Discard the stored session.
```text
lucity logout
```
Deletes the refresh token from the config directory. The platform URL and the active workspace stay, ready for the next `lucity login`.
### `account`
Show who you are signed in as.
```text
lucity account
```
Prints your name and email, the platform, and each workspace you belong to with your role in it, marking the active one with `*`. With `LUCITY_API_TOKEN` set, it describes the token instead.
### `workspace`
Show or switch the active workspace.
```text
lucity workspace
lucity workspace
```
| Argument | Description |
| ------------- | ---------------------------------------------------------------------- |
| `` | Workspace to switch to. `lucity account` lists the ones you belong to. |
Ids that leave out the workspace, such as `shop/production/web`, resolve against the active workspace. `LUCITY_WORKSPACE` overrides it without changing the stored one.
### `deploy`
Build and roll out a service.
```text
lucity deploy [flags]
```
| Argument | Description |
| ----------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| `` | Full service id (workspace/project/environment/service), or the project/environment/service form relative to the active workspace. |
| Flag | Description |
| ------------------ | ----------------------------------------------------------------------- |
| `--ref [` | Branch, tag, or commit to build (default: the service's branch) |
| `--wait` | Block until the release is live or failed, and exit non-zero on failure |
| `--timeout ` | Give up waiting after this long (default 20m, only with `--wait`) |
| `--interval ` | Poll interval while waiting (default 4s) |
| `--json` | Emit the final release as JSON on stdout |
Progress goes to stderr. Without `--wait` the command returns as soon as the release is queued, and prints the release id on stdout.
```bash [Examples]
lucity deploy site/production/web --ref "$GITHUB_SHA" --wait
lucity deploy acme/site/production/web --ref v1.4.2 --wait --timeout 30m
```
**Authentication**
In GitHub Actions, deploys are keyless, so there is no secret to store. Grant the job `permissions: id-token: write` and turn on CI Deploys in the service's settings, and the CLI trades the job's OIDC token for a short-lived session that can only deploy services built from that repository. The session knows its workspace, so `LUCITY_WORKSPACE` is optional.
For other CI systems, set `LUCITY_API_TOKEN` to a workspace API token, created in the Lucity dashboard. The workspace comes from the token.
### `status`
Show the latest rollout status of a service.
```text
lucity status [--json]
```
| Argument | Description |
| ----------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| `` | Full service id (workspace/project/environment/service), or the project/environment/service form relative to the active workspace. |
| Flag | Description |
| -------- | ------------------------------------------------------------ |
| `--json` | Emit the service and its active deployment as JSON on stdout |
Exit status is non-zero when the active rollout is FAILED or DEGRADED, so CI can gate on it.
```bash [Examples]
lucity status site/production/web
lucity status acme/site/production/web --json
```
### `vars`
Manage service variables.
```text
lucity vars list [--json]
lucity vars available [--json]
lucity vars set KEY=VALUE... [--ref KEY=]... [--json]
```
| Command | Description |
| ----------- | ------------------------------------------------------------------------------------------------------------------------------- |
| `list` | Show the variables set on a service |
| `available` | Show the variables a service in the environment can link to, from its databases, key-value stores, buckets and shared variables |
| `set` | Add or change variables on a service |
| Argument | Description |
| ----------- | ------------------------------------------------------------------------ |
| `` | Service id (workspace/project/environment/service) or its relative form. |
| `` | Environment id (workspace/project/environment) or its relative form. |
| Flag | Description |
| ------------------------ | -------------------------------------------------------------------------- |
| `--ref KEY=` | Bind KEY to an available variable (list them with `lucity vars available`) |
| `--json` | Emit the result as JSON on stdout |
`lucity vars set` merges your changes into the existing variables, so variables you do not name are kept. The service then rolls out again on its current image, without a new build.
Works with a signed-in session or a workspace API token. A keyless GitHub Actions session can list and set variables too, but only for services with CI Deploys turned on that build from its own repository.
### `db`
Manage databases.
```text
lucity db create [--size ] [--cpu ] [--memory ] [--json]
lucity db list [--json]
lucity db credentials [--json]
lucity db expose [--json]
lucity db unexpose [--json]
lucity db delete [--yes] [--json]
```
| Command | Description |
| ------------- | ---------------------------------------------------------------------------------------- |
| `create` | Create a PostgreSQL database in an environment |
| `list` | List the databases in an environment |
| `credentials` | Print the connection details, password included |
| `expose` | Give the database a public hostname, reachable over TLS from this machine's address only |
| `unexpose` | Remove the public hostname and its allowed addresses again |
| `delete` | Delete the database and all of its data |
| Argument | Description |
| -------- | ---------------------------------------------------------------------- |
| `` | Environment id (workspace/project/environment) or its relative form. |
| `` | Database name (2-16 chars). |
| `` | Database id (workspace/project/environment/name) or its relative form. |
| Flag | Description |
| ---------------- | ---------------------------------------------------------- |
| `--size ` | Storage size for a new database (e.g. 32Gi) |
| `--cpu ` | CPU limit for a new database, e.g. 500m (with `--memory`) |
| `--memory ` | Memory limit for a new database, e.g. 512Mi (with `--cpu`) |
| `--yes` | Skip the confirmation prompt on delete |
| `--json` | Emit the result as JSON on stdout |
Needs a signed-in session or a workspace API token. A keyless GitHub Actions session cannot manage databases.
### `token`
Print a bearer token for scripting.
```text
lucity token [--account]
```
| Flag | Description |
| ----------- | ------------------------------------------------------------------------------------------------------------------------------- |
| `--account` | Print the account token instead. API calls that read from GitHub on your behalf send it in the `X-Lucity-Account-Token` header. |
Prints a short-lived access token for the active workspace, to call the API with directly.
```bash [Examples]
curl https://lucity.cloud/graphql \
-H "Authorization: Bearer $(lucity token)" \
-H "Content-Type: application/json" \
-d '{"query": "{ projects { id } }"}'
```
### `mcp`
Serve the Lucity MCP server on stdio.
```text
lucity mcp
```
Speaks the Model Context Protocol on stdin and stdout, so an AI agent can create projects, deploy, provision databases and read logs with your session. MCP clients start the server themselves, so configure `lucity mcp` as its command rather than running it by hand.
### `version`
Print the CLI version.
```text
lucity version
lucity --version
```
## Next steps
- [Deployments](https://lucity.cloud/docs/deployments) for what happens between a commit and a running service
- [Variables](https://lucity.cloud/docs/variables) for service, shared and dynamic variables
- [Claude plugin & MCP](https://lucity.cloud/docs/claude-plugin) for letting an agent deploy for you
- [API](https://lucity.cloud/docs/api) for everything the CLI doesn't cover
# Claude Plugin & MCP
The Lucity plugin for [Claude Code](https://code.claude.com/docs/en/overview) lets you deploy a project by asking for it, then keep working on it in the same conversation: reading logs, changing variables, rolling back. It contains a **deploy skill** that walks Claude through taking a local project to a running deployment, and the **Lucity MCP server** that gives Claude the tools to do it, from creating projects to reading logs. The server is part of the [CLI](https://lucity.cloud/docs/cli) and runs on your machine.
## Install
The plugin runs its MCP server through the Lucity CLI, so [install the CLI](https://lucity.cloud/docs/cli#install) and sign in with `lucity login` first. Then add the Lucity repository as a plugin marketplace and install the plugin from it:
::tabs
:::tabs-item{label="Terminal"}
```bash
claude plugin marketplace add zeitlos/lucity
claude plugin install lucity@lucity
```
:::
:::tabs-item{label="Claude Code"}
```text
/plugin marketplace add zeitlos/lucity
/plugin install lucity@lucity
```
`/plugin install` opens the plugin's details first, so choose **Install for you (user scope)** there and confirm.
:::
::
Either way, the plugin is installed for your user, so it is available in every project, and in the desktop app and VS Code on the same machine as well. Claude Code starts the MCP server when a session begins, so run `/reload-plugins` in a session that was already open, or start a new one.
To check that it works, ask Claude which Lucity workspace you are in. If it has no Lucity tools, Claude Code most likely couldn't find the `lucity` command when the session started, so check that `lucity version` works in a new terminal and start a new session. If Claude says you are not signed in or your session has expired, run `lucity login` in a terminal and ask it to try again.
## Update
The MCP server is part of the CLI, so it updates when you [update the CLI](https://lucity.cloud/docs/cli#update). Claude Code starts the server once per session, so the new version takes over in your next session.
The plugin itself doesn't update on its own, because Claude Code leaves automatic updates off for third-party marketplaces. Update it by hand:
```bash
claude plugin marketplace update lucity
claude plugin update lucity@lucity
```
To have it update automatically instead, open `/plugin` in a terminal session, go to **Marketplaces**, select `lucity` and choose **Enable auto-update**. Either way, the new version loads in your next session, or straight away with `/reload-plugins`.
## The deploy skill
Open Claude Code in your project and ask it to deploy, in your own words ("deploy this to Lucity", "put this online") or with `/lucity:deploy`. The skill then takes Claude through the whole deployment:
- It works out what the code consists of: a single app, a monorepo, a frontend and an API, or a web process and a worker.
- It creates the project and its services, provisions the PostgreSQL databases, key-value stores and buckets the code uses, and connects them with [dynamic variables](https://lucity.cloud/docs/variables#dynamic-variables).
- It deploys, and when a build or rollout fails, it reads the logs, fixes the configuration and tries again, up to three times.
- It finishes with the URL and a summary of everything it set up, and why.
It asks you before it creates paid resources, and for anything it can't find out on its own, such as API keys for other services, data to import, or which repositories belong together. It doesn't edit your code to get a deploy through. When a fix needs a code change, for example because the app ignores the `PORT` variable, it proposes the change and leaves it to you.
After the first deploy, keep going in the same conversation. Ask why a service keeps crashing, to give it more memory, to add a domain, or to roll back to the previous deployment.
## What Claude can see
Claude can't read your secrets. The MCP server never returns the values of variables, or the credentials of databases, key-value stores and buckets. Claude can still check whether a variable holds the value it expects, and have the server generate secrets for your app that it never sees.
Keys for other services have to come from you, so add them in the dashboard, in the service's **Variables** tab, instead of pasting them into the chat.
The server also masks runtime logs as well as it can before Claude sees them. Every variable value and credential it knows about is replaced with `[redacted:]`. Secrets that aren't stored in Lucity and values shorter than 8 characters get through, and build logs aren't masked.
This only covers what the MCP server returns. If Claude reads a `.env` file or runs a command that prints secrets, such as `lucity vars list`, it sees them like anything else it reads.
## Codex, Cursor and other agents
The MCP server isn't tied to Claude Code. Any agent that can start a local MCP server can use it, with `lucity mcp` as the command. You get the same tools and the same protection of secrets, just without the deploy skill.
::tabs
:::tabs-item{label="Codex"}
```bash
codex mcp add lucity -- lucity mcp
```
The Codex CLI, IDE extension and desktop app share this setting.
:::
:::tabs-item{label="Cursor"}
Add the server to `~/.cursor/mcp.json`:
```json
{
"mcpServers": {
"lucity": {
"command": "lucity",
"args": ["mcp"]
}
}
}
```
:::
:::tabs-item{label="VS Code"}
For GitHub Copilot in VS Code:
```bash
code --add-mcp '{"name":"lucity","command":"lucity","args":["mcp"]}'
```
:::
:::tabs-item{label="Gemini CLI"}
```bash
gemini mcp add -s user lucity lucity mcp
```
Without `-s user`, the server is only added to the current project.
:::
:::tabs-item{label="Claude Desktop"}
For chats in the Claude desktop app, open **Settings** → **Developer** → **Edit Config** and add the server. The app may not find commands on your shell's `PATH`, so use the full path that `which lucity` prints:
```json
{
"mcpServers": {
"lucity": {
"command": "/opt/homebrew/bin/lucity",
"args": ["mcp"]
}
}
}
```
Then quit and reopen the app. Its **Code** tab is Claude Code, which uses the plugin instead.
:::
::
Other agents, like Zed or opencode, take the same command in their own settings. If one can't find `lucity`, give it the full path that `which lucity` prints.
## Next steps
- [CLI](https://lucity.cloud/docs/cli) for the commands the MCP server comes with
- [Variables](https://lucity.cloud/docs/variables) for the dynamic variables that connect your resources
- [Deployments](https://lucity.cloud/docs/deployments) for what happens after Claude deploys
# Metrics
Lucity keeps track of how much CPU and memory each [service](https://lucity.cloud/docs/services) uses, what each [database](https://lucity.cloud/docs/postgres) is doing, and how full each [volume](https://lucity.cloud/docs/volumes) is.
## Service metrics
Open a service on the canvas and switch to the **Metrics** tab. It charts CPU and memory over the last hour, 6 hours, 24 hours, 7 days or 30 days.
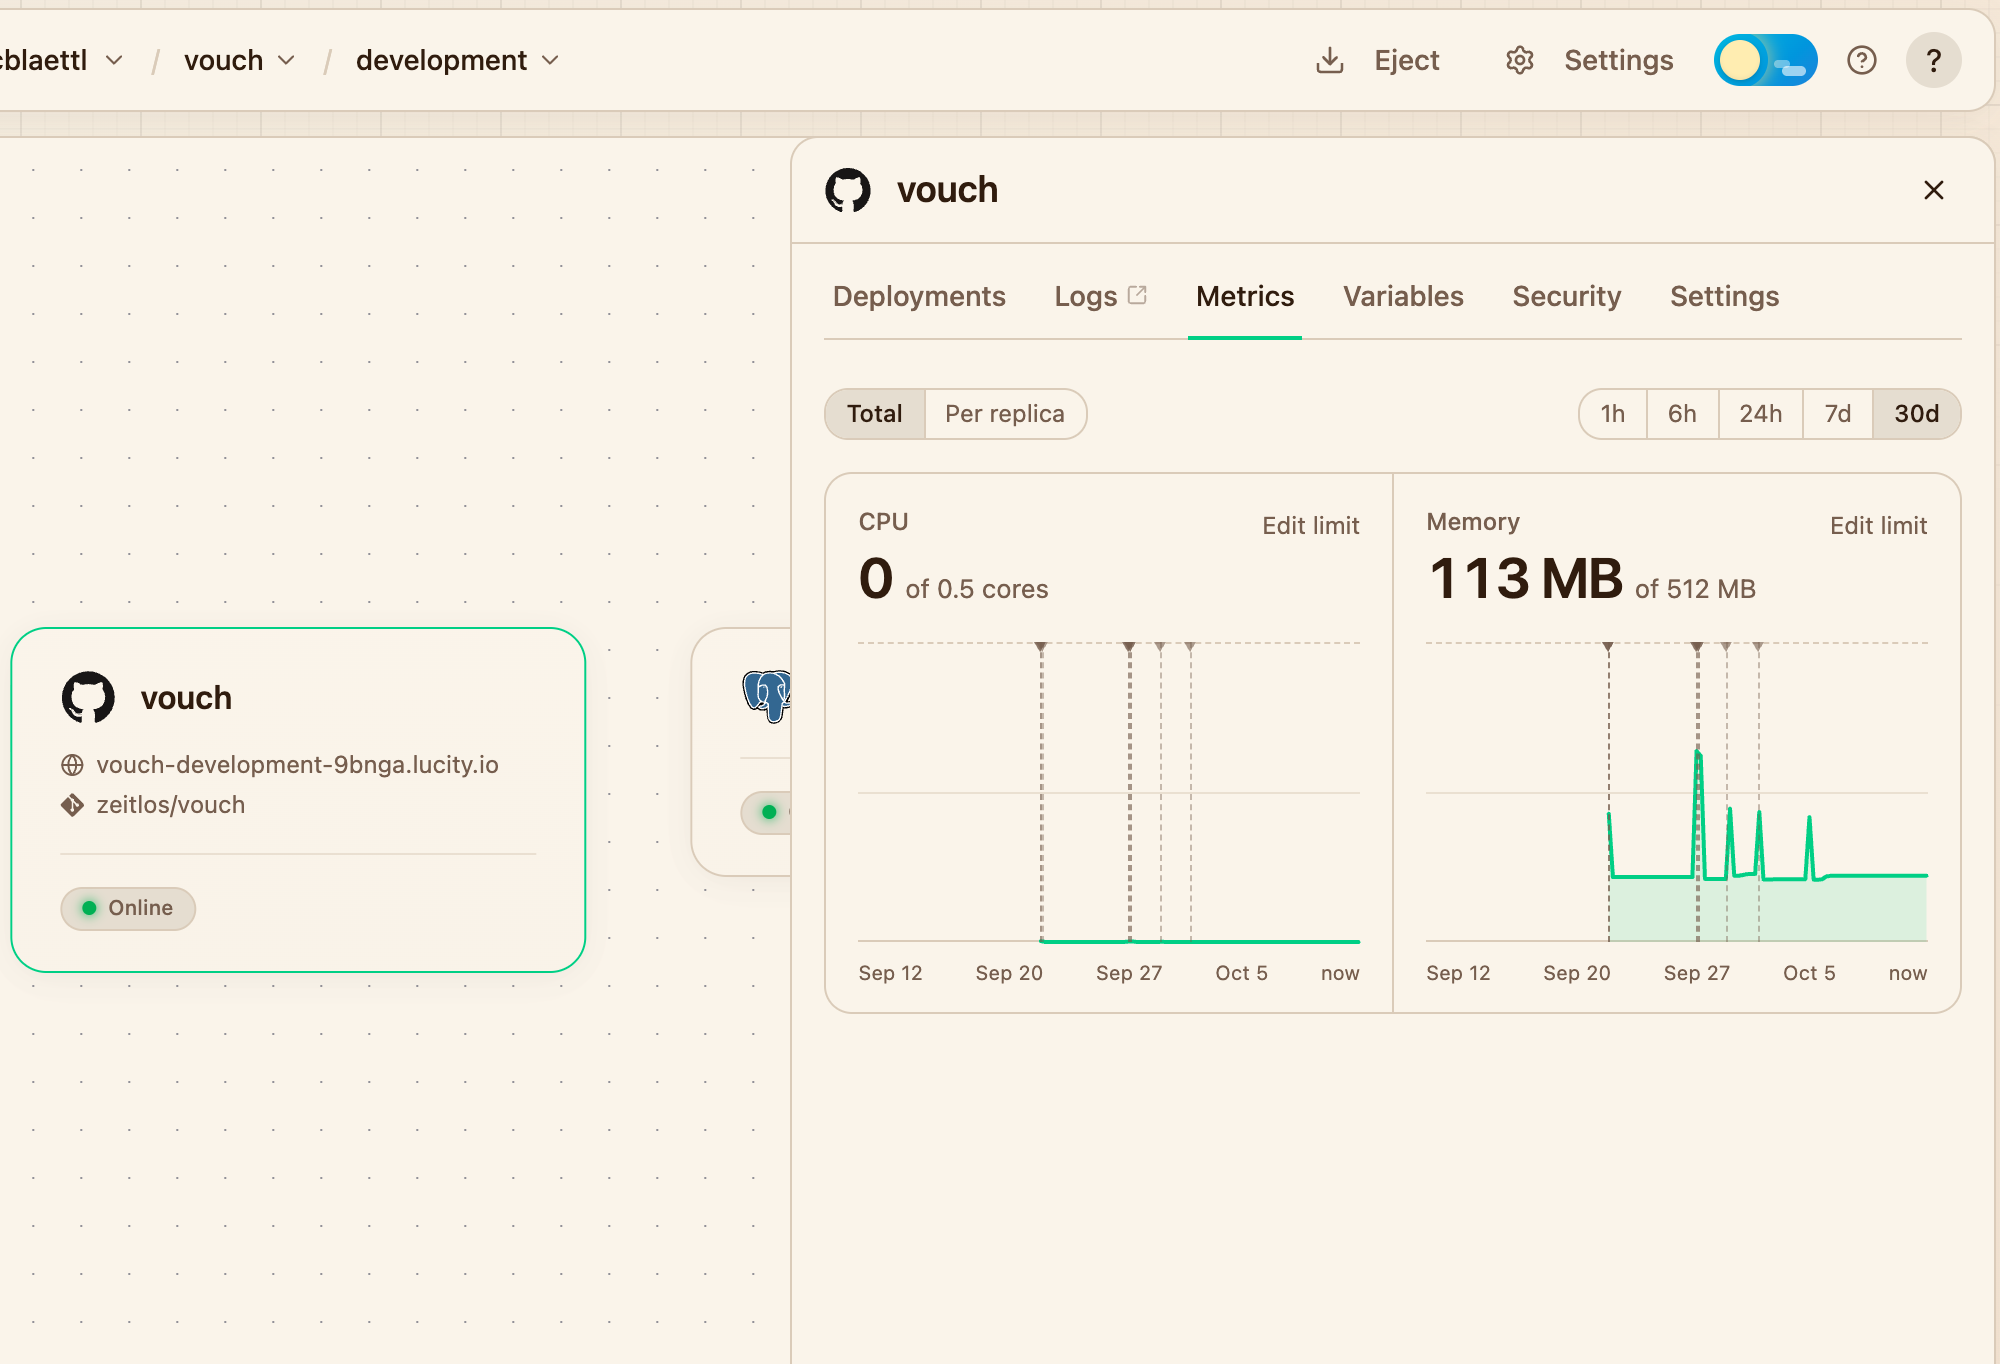
*CPU and memory over 30 days. The dashed vertical lines mark deployments.*
The large number above each chart is the current usage, next to the most the service can use, which is its CPU or memory limit times the number of replicas. The dashed line along the top of the chart marks that limit, and **Edit limit** opens the service settings to change it. [CPU and memory](https://lucity.cloud/docs/services#cpu-and-memory) explains what happens when a service reaches it.
**Total** adds up all replicas of the service, while **Per replica** gives each replica its own line. Every deployment is marked with a dashed vertical line, so you can tell whether a change moved the numbers. Hovering over a chart moves a cursor across both charts, and the numbers switch to their values at that moment.
CPU is measured in cores, and anything below one core is shown in thousandths, so 250m is a quarter of a core. Metrics show up a minute or two after a service starts, and the charts refresh every 30 seconds.
## Database metrics
Open a database and switch to the **Metrics** tab. CPU and memory sit on top, charted against the limits of the database, with a grid below them for storage, connections, transactions and rows read and written per second, the cache hit ratio, deadlocks, and how far the replica trails the primary.
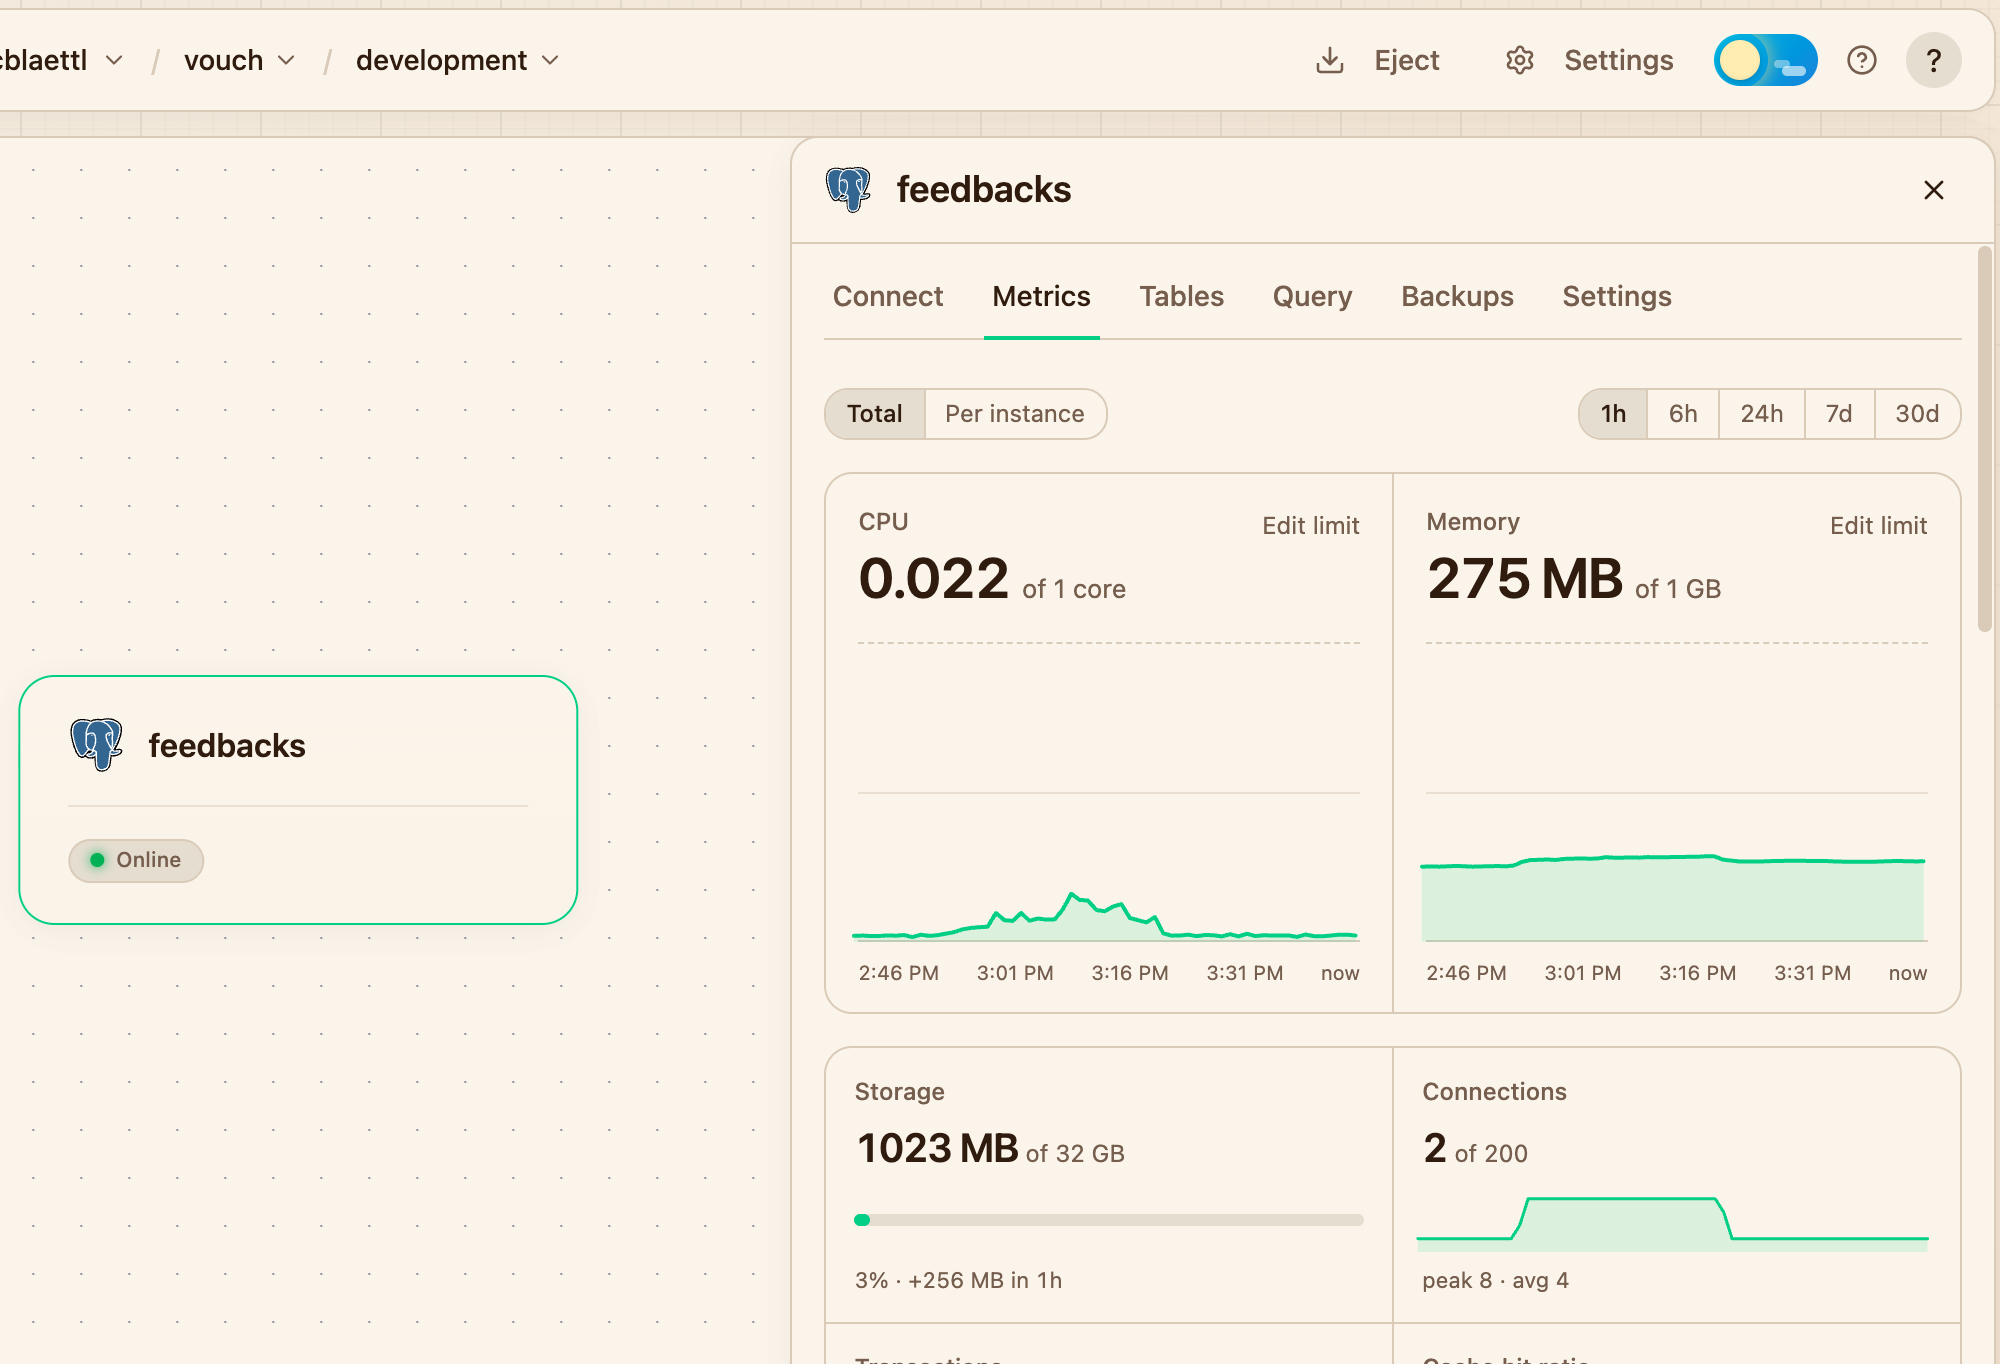
*CPU and memory against their limits, and what PostgreSQL is doing below them.*
Every number is the current value, and the line under it puts it in context, such as the peak over the selected range or when the last deadlock happened. Hovering over any chart moves a cursor across all of them, and every number switches to its value at that moment.
**Total** adds up both instances, while **Per instance** gives each one its own line, labeled with whether it is the primary or the replica right now. A cache hit ratio close to 100% means almost every read is answered from memory, so a ratio that keeps dropping usually means the database needs more memory.
Below the charts, **Top queries** lists the statements that took the most time in total, with their share of that time, how often they ran, how long they took on average and how many rows they returned. Values in a statement are replaced by placeholders such as `$1`, so every call of the same query counts together. Open a row to read the whole statement and copy it. The list counts from the time shown next to its title and starts over when the primary changes.
## Volume usage
Open a volume and switch to the **Usage** tab to see how much of the disk is in use, as a percentage of its size and charted over the same time ranges.
On the canvas, a mounted volume is attached under its service and fills from left to right as the disk fills up. Usage is only recorded while the volume is mounted.
## Next steps
- [Services](https://lucity.cloud/docs/services#cpu-and-memory) for changing CPU, memory and replicas
- [Volumes](https://lucity.cloud/docs/volumes#size) for growing a volume that is filling up
- [Logs](https://lucity.cloud/docs/logs) for what a service prints while it runs
# Logs
There are two kinds of logs. Runtime logs are what a [service](https://lucity.cloud/docs/services) prints while it runs, and deployment logs are the output of each step of a [deployment](https://lucity.cloud/docs/deployments).
## Runtime logs
Open a service on the canvas and click **Logs** next to the **Deployments** tab. The logs open in a panel of their own and stream live.
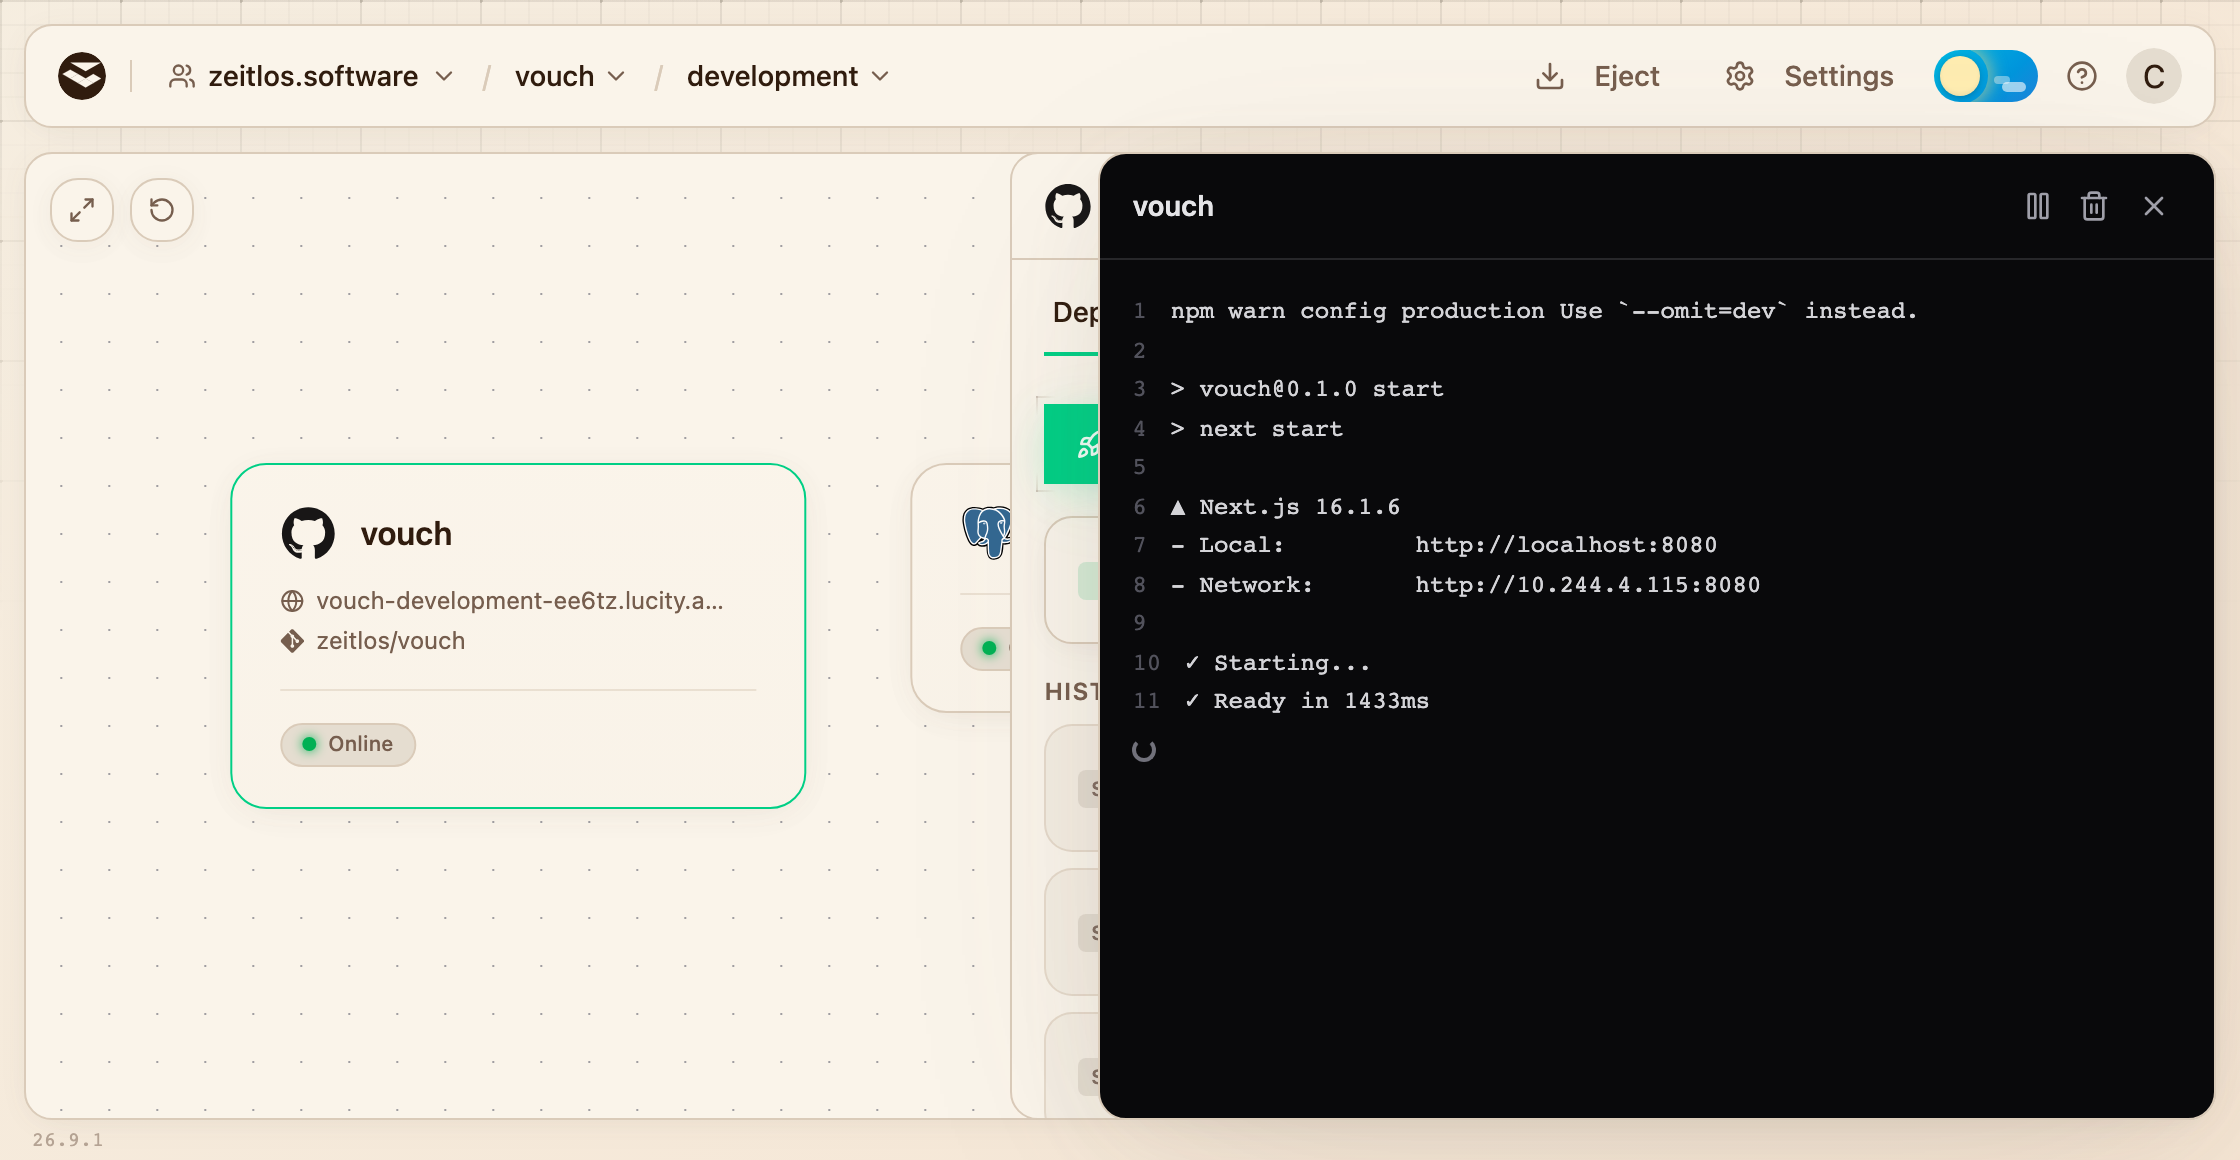
*A service's output as it starts up. Pause and clear sit in the top right.*
The panel starts with the last 1000 lines of each running replica and then follows along as new lines come in. When a service runs more than one replica, each line starts with a short ID of the replica that printed it.
The panel sticks with the replicas that were running when you opened it, so reopen it after a deployment to follow the new ones. If a service keeps crashing, the logs show what the last attempt printed before it exited.
## Deployment logs
Open the service's **Deployments** tab, expand a deployment and click **Logs** next to **Build**, **Secrets** or **Deploy**. The logs stream while the step runs and stay available for a week. After that, the deployment stays in the list but only shows its rollout.
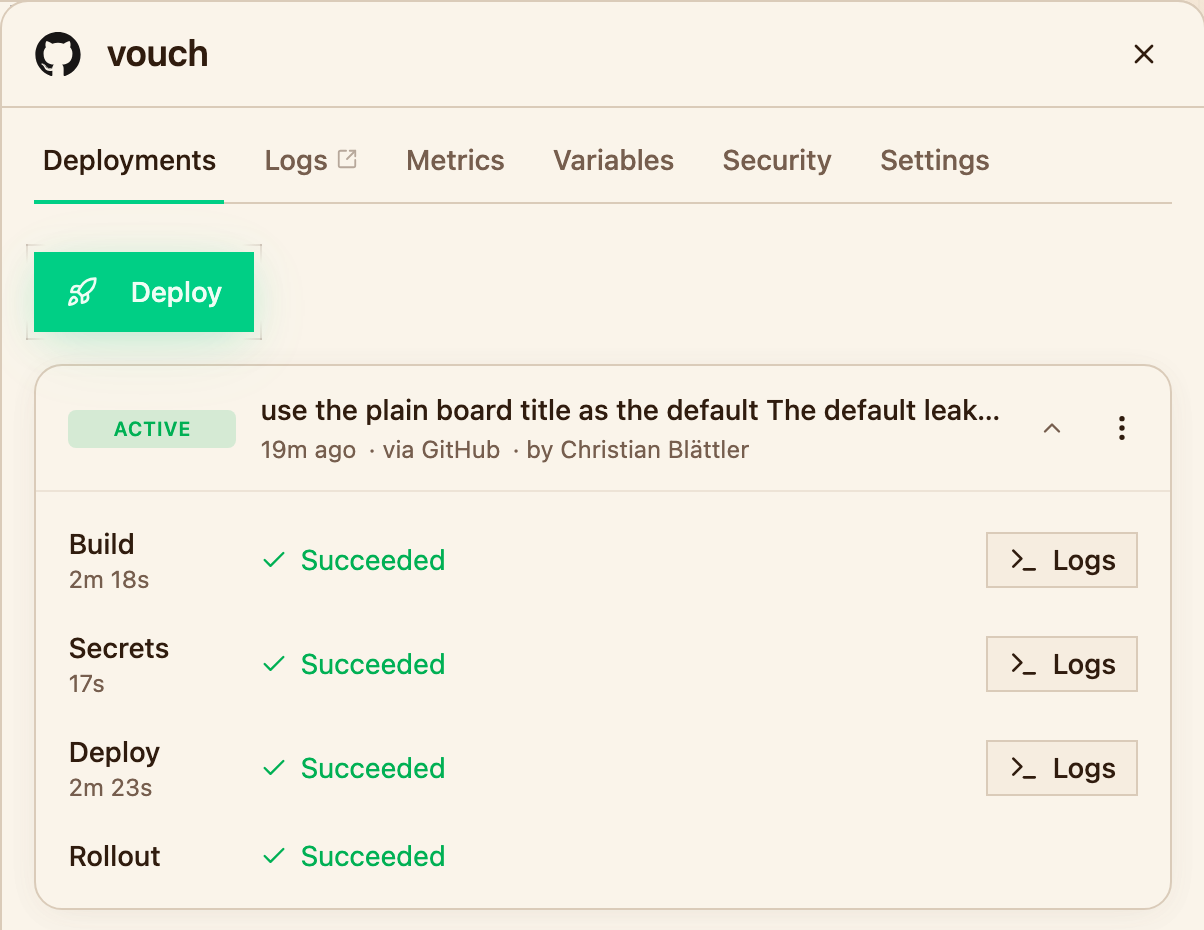
*Build, Secrets and Deploy each keep their own logs.*
Rollout has no logs of its own. If a new version never becomes healthy, its [runtime logs](https://lucity.cloud/#runtime-logs) usually say why.
## Next steps
- [Deployments](https://lucity.cloud/docs/deployments#deployment-steps) for what each step does
- [Builds](https://lucity.cloud/docs/builds#troubleshooting) for making sense of a failed build
- [Metrics](https://lucity.cloud/docs/metrics) for CPU and memory over time
# Billing
Every [workspace](https://lucity.cloud/docs/workspaces) has its own plan and its own invoice. The plan's monthly fee comes back to you as credit for the resources your projects use, so you only pay extra for usage beyond it. The plans and the rates for resources are on the [pricing page](https://lucity.cloud/pricing).
## What you pay for
Resource usage is the CPU, memory and disk taken up by your services, databases, key-value stores and volumes.
How CPU and memory are counted depends on the environment's [tier](https://lucity.cloud/docs/environments#tiers). In an **Eco** environment you pay for what your services actually use, so a service that sits idle costs very little. In a **Production** environment you pay for the CPU and memory reserved for each service, whether it uses them or not. Disk is billed at its full size, however much of it is filled.
Usage is paid from the plan's credit first, and anything beyond it is added to the next invoice. Credit left over at the end of a billing period doesn't carry over.
## Tracking usage
Open **Workspace settings** from the avatar menu in the top right and choose **Billing**. It shows the plan, when the current billing period ends, and what the workspace has used so far in this period.
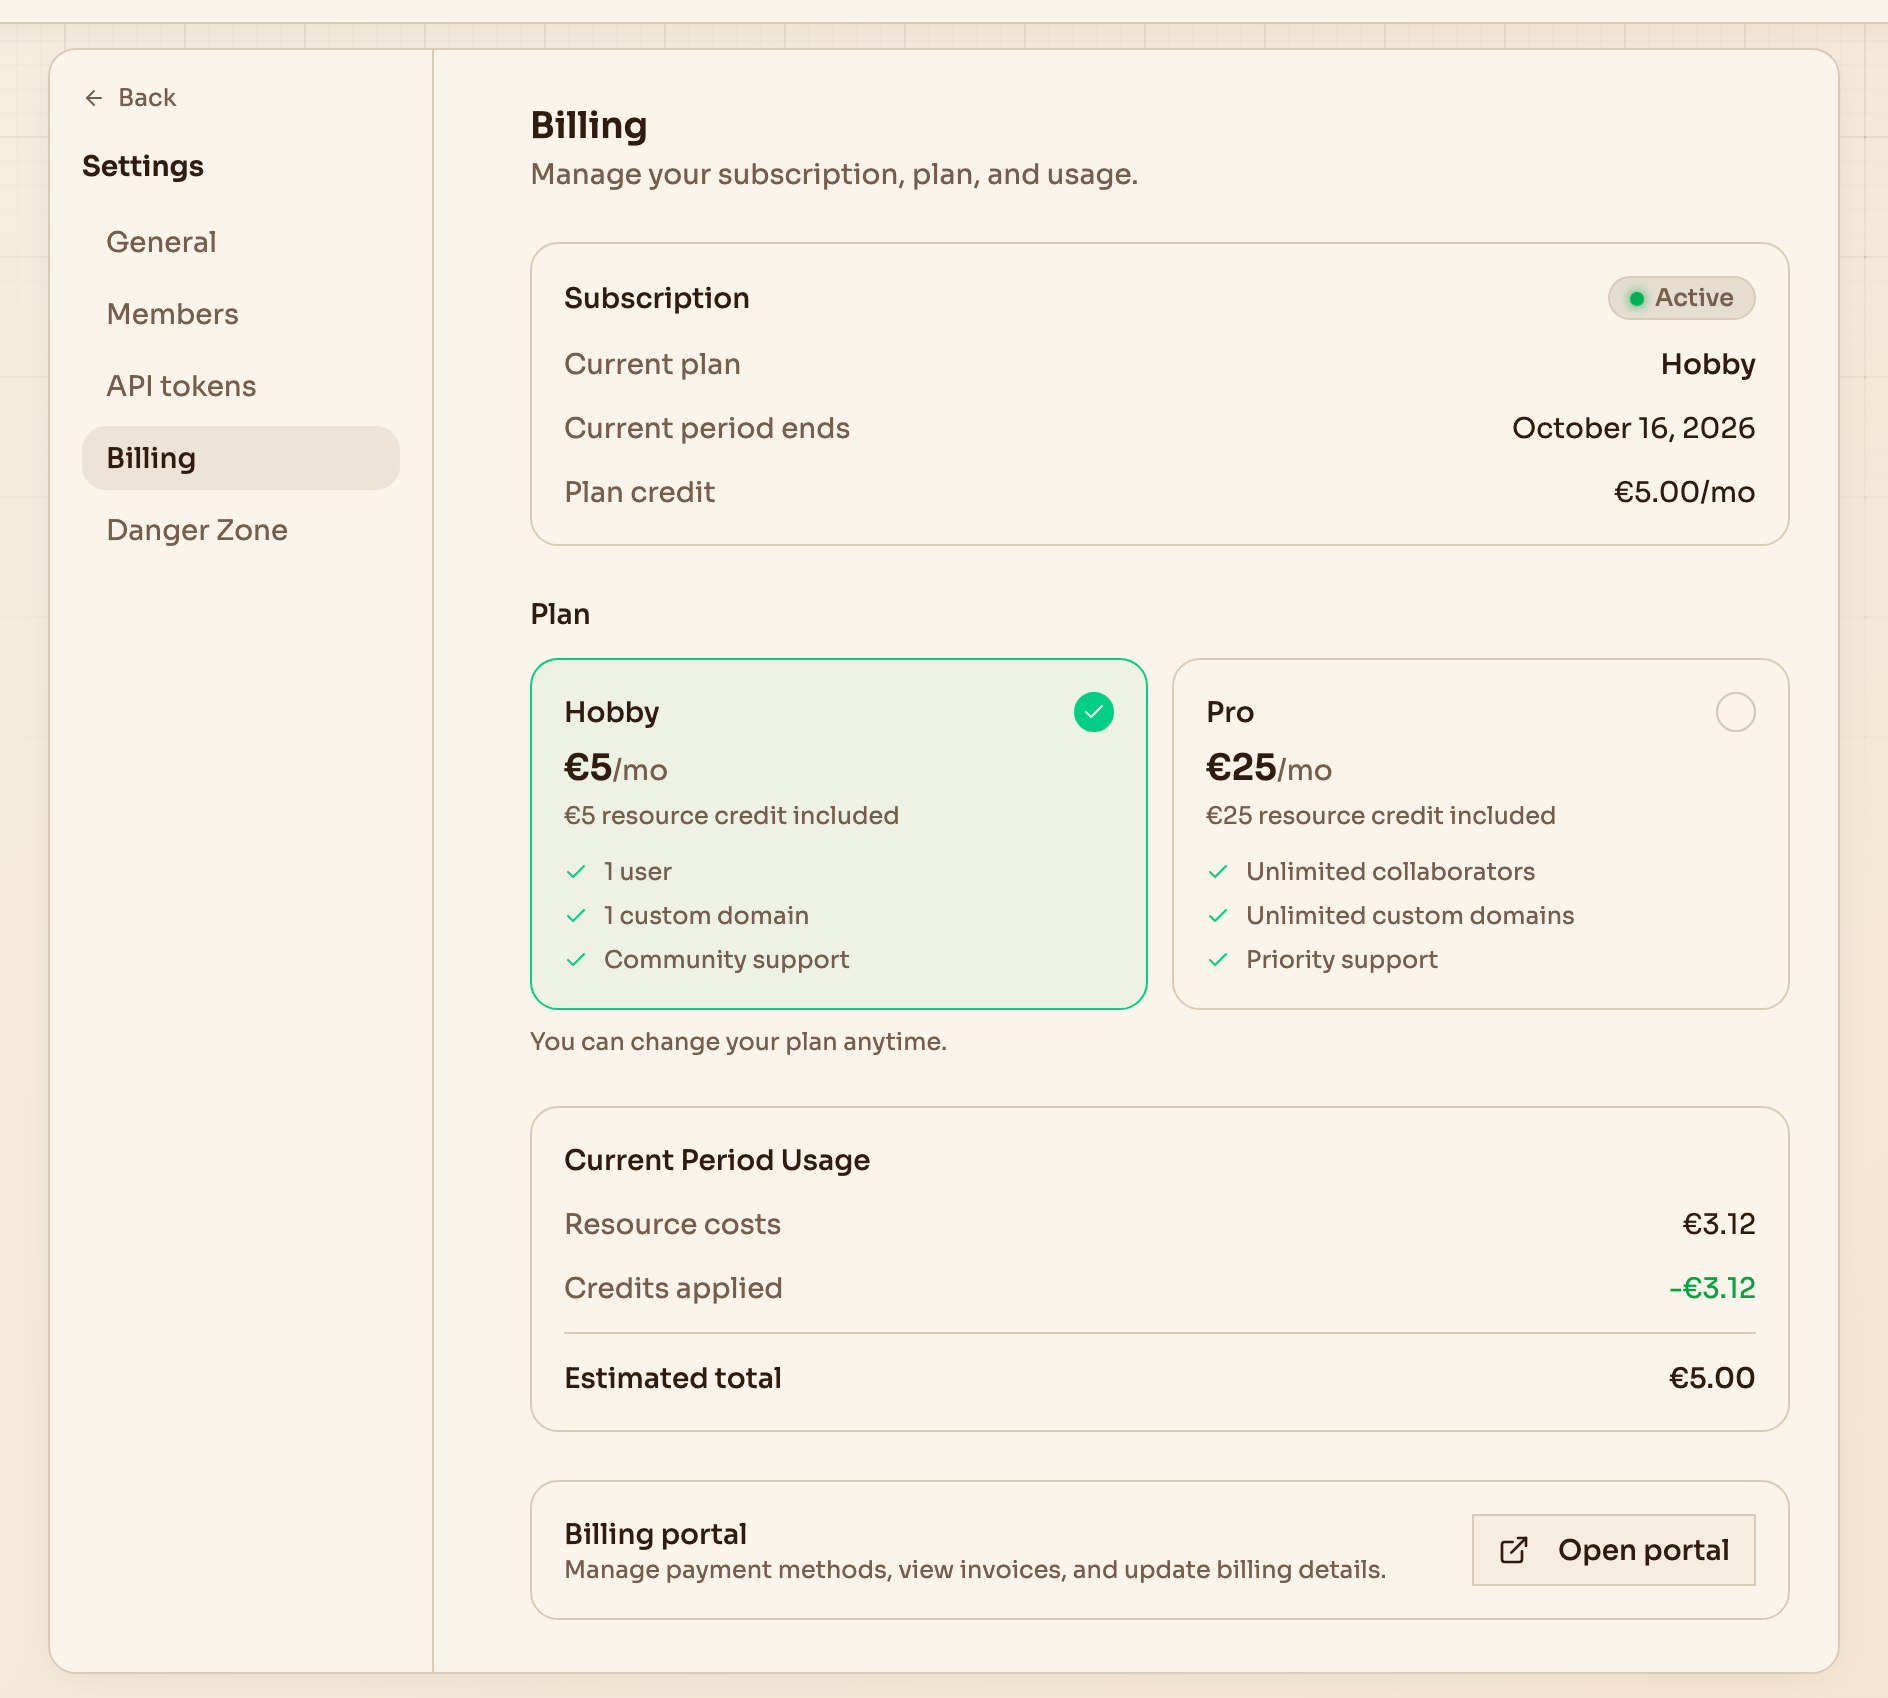
*The estimated total is the plan fee plus whatever usage the credit doesn't cover.*
## The free trial
When you sign up, your [personal workspace](https://lucity.cloud/docs/workspaces#personal-workspaces) gets a free trial of 14 days or €5 of usage, whichever runs out first. No credit card is needed. A badge in the dashboard header counts down both.
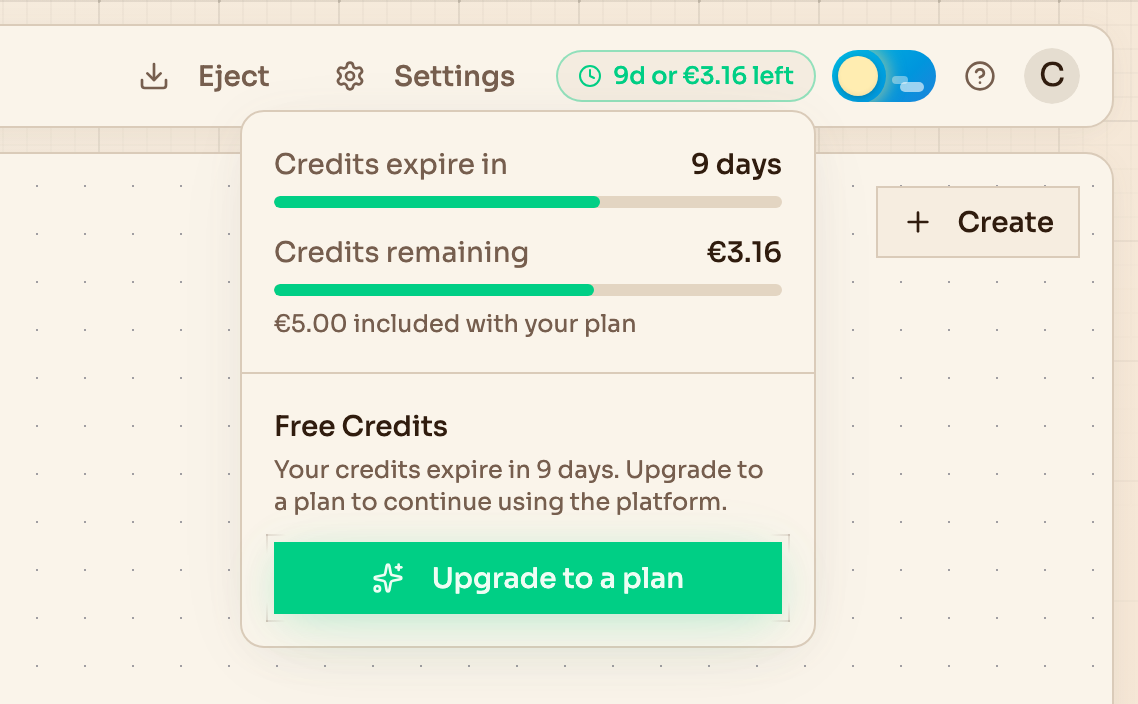
*What's left of the trial, one click away.*
To keep the workspace running, choose a plan under **Billing** and add a payment method. If the trial runs out first, the workspace is [suspended](https://lucity.cloud/#suspension) until you do.
Only your personal workspace gets a trial. Creating any other workspace asks you to choose its plan and pay for it straight away.
## Changing plans
Switch between Hobby and Pro under **Billing** at any time. The new plan applies immediately, and the fee is prorated for the rest of the billing period.
## Payment methods and invoices
**Open portal** under **Billing** takes you to the billing portal, where you change the payment method, download invoices and update your billing details.
Everyone in the workspace can see its plan and usage, but only [admins](https://lucity.cloud/docs/workspaces#members-and-roles) can change the plan or open the portal.
## Suspension
A workspace is suspended when its trial ends without a plan, or when a payment fails. While it is suspended:
- Services stop, and their domains stop serving traffic.
- Databases and key-value stores are paused.
- Nothing can be built, deployed or changed, but you can still look around the dashboard.
Your data stays put. Databases, volumes and buckets keep their contents, and everything comes back the way it was.
A banner across the top of the dashboard leads to the fix. After a trial, choose a plan. After a failed payment, update the payment method in the billing portal. As soon as the payment goes through, the workspace resumes on its own.
## Next steps
- [Workspaces](https://lucity.cloud/docs/workspaces) for members, roles and who can manage billing
- [Environments](https://lucity.cloud/docs/environments#tiers) for choosing a tier
# Self-hosting
Lucity is two Helm charts on a Kubernetes cluster. `lucity-infra` brings the pieces the platform leans on, and `lucity` brings the platform itself. Nothing phones home, nothing is licensed, and the cluster stays yours.
That said, this is not a one-command install. The platform runs other people's code on shared infrastructure, so it wants TLS, DNS, an identity provider, and a container registry before it will do anything useful. Budget an afternoon for the first one.
## Prerequisites
A cluster, first of all:
| Requirement | Why |
| --------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Kubernetes 1.28+ | Gateway API and CNPG both want a recent cluster |
| Three nodes or more | The control plane pods spread across nodes, and you want room for workloads |
| A CSI storage class with expansion | The registry, the databases, and user volumes all need persistent storage |
| A Gateway API controller | [Cilium](https://cilium.io) and [Envoy Gateway](https://gateway.envoyproxy.io) are both fine. On an IPv4-only cluster, pin the gateway Service to single-stack IPv4 |
| [cert-manager](https://cert-manager.io) 1.21+ | Issues the platform certificates and one per custom domain |
| A load balancer for the gateway | Whatever your provider offers, reachable from the internet |
And two domains, which must be different from each other:
| Domain | Holds |
| --------------- | -------------------------------------------------------------------------- |
| Platform domain | The dashboard, the API, the docs, and the identity provider on a subdomain |
| Workload domain | Every deployed service, on generated subdomains |
Workload subdomains are handed to arbitrary user code, so anything sharing that domain shares cookies and certificate scope with it. Our own split is `lucity.cloud` for the platform and `lucity.app` for workloads.
You will also need a **GitHub App**, which is how the platform reads source repositories, and an **object store** for buckets.
## What is required and what is not
The infra chart ships a lot of switches. Only some of them are load-bearing:
| Component | Status | Notes |
| ----------------------- | ----------- | ------------------------------------------------------------------------------------------ |
| Zot (OCI registry) | Required | Holds every image the platform builds |
| CloudNativePG | Required | Backs both the identity provider and user databases |
| Logto | Required | The identity provider. Users, workspaces, roles, and GitHub sign-in |
| VictoriaMetrics | Required | The conductor refuses to start without it, because metrics drive the dashboard and scaling |
| VictoriaLogs | Recommended | Build and runtime logs in the dashboard |
| OpenTelemetry collector | Recommended | Feeds both of the above |
| Traefik | Optional | Only for exposing databases over the internet by SNI |
| Barman Cloud plugin | Optional | Only if you want database backups to object storage |
| Grafana, Alertmanager | Optional | Operator convenience, nothing in the platform reads them |
| Rybbit | Optional | Web analytics for the marketing site |
| Billing (cashier) | Optional | Off unless you are charging people |
## Before the charts
Two things have to be true about the cluster before either chart will behave.
### Let containerd pull from the in-cluster registry
The platform pulls user images from Zot over plain HTTP on a fixed service IP, and containerd will not do that by default. The infra chart runs a DaemonSet that writes the per-registry `hosts.toml` to every node, but containerd only reads it if its config points there:
```toml
[plugins."io.containerd.grpc.v1.cri".registry]
config_path = "/etc/containerd/certs.d"
```
Containerd loads one config file rather than merging them, so add that block to a full copy of your nodes' existing config and restart containerd. On some distributions, Flatcar among them, the running config lives outside `/etc` and the service has to be pointed at the new file explicitly.
::note
This is per-node state, so it is lost when a node is replaced. If you build your own node images, bake it in.
::
### Give cert-manager DNS-01 access
Platform certificates include a wildcard for the workload domain, and a wildcard can only be validated over DNS-01. So cert-manager needs an API credential for your DNS provider that can write TXT records in both zones. Scope it to those zones and nothing else: it is the one credential here that can change public DNS.
How you create it depends on the provider, and [cert-manager documents a solver for each of the common ones](https://cert-manager.io/docs/configuration/acme/dns01/). Whichever you use, the shape is the same. Put the provider token in a Secret in the `cert-manager` namespace:
```bash
kubectl create secret generic dns-credentials \
-n cert-manager \
--from-literal=api-token=''
```
Then reference it from an issuer in your values file, rather than applying the issuer by hand, with one solver per zone selected by `dnsZones`:
```yaml
clusterIssuers:
- name: letsencrypt-dns01
acme:
server: https://acme-v02.api.letsencrypt.org/directory
email: you@example.com
solvers:
- selector:
dnsZones: [""]
dns01:
# provider-specific block, see the cert-manager docs
- selector:
dnsZones: [""]
dns01:
# same provider, the other zone
```
If the two domains live with different providers, give each solver its own provider block.
A second issuer, using HTTP-01, handles certificates for the custom domains your users attach to their own services. That one needs no credentials, because it validates over the gateway that is already serving the domain.
## The infra chart
Two files drive this chart. `infra-values.yaml` holds the shape of your installation:
```yaml
zot:
persistence: true
pvc:
create: true
storage: 20Gi
storageClassName:
service:
# Pin this inside your service CIDR. Nodes pull images by this address,
# so it has to be stable and it has to match registryPull.host later.
clusterIP: "10.96.100.100"
mountConfig: true
gateway:
className: cilium
listeners:
- name: platform-http
protocol: HTTP
port: 80
hostname:
- name: platform-https
protocol: HTTPS
port: 443
hostname:
tls:
mode: Terminate
certificateRefs:
- name: platform-tls
- name: workload-http
protocol: HTTP
port: 80
hostname: "*."
- name: workload-https
protocol: HTTPS
port: 443
hostname: "*."
tls:
mode: Terminate
certificateRefs:
- name: workload-tls
- name: id-http
protocol: HTTP
port: 80
hostname: id.
- name: id-https
protocol: HTTPS
port: 443
hostname: id.
tls:
mode: Terminate
certificateRefs:
- name: id-tls
certificates:
- name: platform-tls
secretName: platform-tls
issuerRef: { name: letsencrypt-dns01 }
dnsNames: [""]
- name: workload-tls
secretName: workload-tls
issuerRef: { name: letsencrypt-dns01 }
dnsNames: ["*."]
- name: id-tls
secretName: id-tls
issuerRef: { name: letsencrypt-dns01 }
dnsNames: ["id."]
clusterIssuers: # both issuers from the previous section
logto:
enabled: true
endpoint: https://id.
postgres:
storageClass:
victoria-metrics-single:
enabled: true
server:
persistentVolume:
storageClassName:
victoria-logs-single:
enabled: true
server:
persistentVolume:
storageClassName:
otelCollector:
daemonset: { enabled: true }
deployment: { enabled: true }
```
Every listener needs a matching certificate, and the certificate names here are what the listeners reference.
`infra-secrets.yaml` holds the credentials. The registry needs two users, one that pushes built images and one that nodes pull with:
```bash
htpasswd -bBn builder "$(openssl rand -hex 16)" > htpasswd
htpasswd -bBn reader "$(openssl rand -hex 16)" >> htpasswd
```
Keep both plaintext passwords, because the platform chart needs them again. Then:
```yaml
zot:
configFiles:
htpasswd: |
# both lines from the file above
logto:
secrets:
secretVaultKek: ""
```
Install `lucity-infra` in two passes the first time. The chart carries both the CloudNativePG operator and a PostgreSQL cluster that needs its CRDs, so a single-pass install cannot resolve them.
Pass one brings up the operator with the identity provider switched off:
```bash
helm upgrade --install lucity-infra oci://ghcr.io/zeitlos/lucity/charts/lucity-infra \
--version -n lucity-system --create-namespace \
-f infra-values.yaml -f infra-secrets.yaml --set logto.enabled=false
```
Wait for the operator and its webhook:
```bash
kubectl -n lucity-system wait --for=condition=Available deploy/lucity-infra-cloudnative-pg --timeout=180s
```
Then pass two, with nothing overridden:
```bash
helm upgrade --install lucity-infra oci://ghcr.io/zeitlos/lucity/charts/lucity-infra \
--version -n lucity-system \
-f infra-values.yaml -f infra-secrets.yaml
```
Upgrades after this are single-pass, because the CRDs are already in the cluster.
::note
Always pass
`--version`
explicitly, because
`latest`
resolves to the highest stable release and can move you backwards.
::
Give the identity provider a minute to pick up its database credentials, then check that everything is up:
```bash
kubectl -n lucity-system get pods
kubectl -n lucity-system get cluster
kubectl -n lucity-system get certificate
kubectl get gateway -A
```
The gateway should report an address and `PROGRAMMED: True`.
## DNS for the platform
The gateway now has an address, so the platform hostnames can point at it. Three records carry the whole installation:
| Record | Points at | Serves |
| ----------------------------------- | --------------- | ---------------------- |
| `A` on the platform domain | Gateway address | Dashboard, API, docs |
| `A` on `id.` of the platform domain | Gateway address | The identity provider |
| `A` on `*` of the workload domain | Gateway address | Every deployed service |
The wildcard is what makes a freshly generated service hostname work immediately, with no DNS wait and no per-service record.
Once a wildcard covers the workload domain, the only records left are those two platform hostnames, which never change, so external-dns buys you little here.
## Bootstrapping the identity provider
Logto starts empty and the platform expects a specific shape inside it. Nothing automates this yet, so it is console work.
The console is not exposed publicly, so reach it over a port-forward:
```bash
kubectl -n lucity-system port-forward svc/lucity-infra-logto 3002:3002
```
Open `http://localhost:3002` and create the first admin account. Then work through the sections below in order.
Workspaces are Logto organizations, and a workspace member's rights come from their organization role. Build this in the order below, because the permissions live on the API resource rather than on the organization.
### API resource
Create the API resource first. Its identifier is the audience you will give the conductor, for example `https://api.`, and it becomes the `OIDC_AUDIENCE` value.
Then give that resource three **permissions**: `admin`, `member`, and `deployer`.
::warning
These must be
**API resource permissions**
, not organization permissions, because the platform requests its scopes against the API resource.
::
### Organization roles
Now create the roles under **Organization template**. Each asks for a name, a description, and a role type. Assign the API resource permissions from the previous step, leaving organization permissions empty:
| Role | Type | Permissions |
| ------------------ | ------------------ | ----------- |
| `admin` | User | `admin` |
| `member` | User | `member` |
| `machine-admin` | Machine-to-machine | `admin` |
| `machine-member` | Machine-to-machine | `member` |
| `machine-deployer` | Machine-to-machine | `deployer` |
The two **User** roles cover people signing in. The three **machine-to-machine** roles cover workspace API keys and CI, so `machine-deployer` is what a GitHub Actions deploy runs as.
::warning
The names must be exactly
`admin`
and
`member`
, lowercase. Descriptions are yours to write.
::
### Applications
Three, because three different clients sign in:
| Application | Type | Redirect URI | Becomes |
| ------------------ | ------- | -------------------------------------------------------------------- | --------------------------------------------- |
| Dashboard | **SPA** | `https:///auth/callback` | `OIDC_CLIENT_ID` |
| CLI | Native | `http://127.0.0.1:8765/callback`, and the same for `8766` and `8767` | `OIDC_CLI_CLIENT_ID` |
| Machine to machine | M2M | none | `LOGTO_M2M_APP_ID` and `LOGTO_M2M_APP_SECRET` |
::warning
The dashboard application must be a
**SPA**
, because the platform authenticates with PKCE and sends no client secret. Logto cannot change an application's type after creation, so fix a mistake by deleting the application and making a new one.
::
The CLI logs in with PKCE against a loopback listener and takes the first free port, so register all three.
Give the M2M application the **Logto Management API** role. The conductor uses it to create organizations, assign roles, and read members, so without it workspace creation fails.
### GitHub connector
Users sign in to Logto, Logto runs the GitHub handshake, and the resulting token is kept in Logto's Secret Vault, so GitHub redirects back to Logto and not to the platform.
Add a GitHub social connector. Three fields on that page matter.
**Identity provider name** must be `github`, which is also the default.
**Client ID and Client Secret**, under Parameter configuration, take the values from your **GitHub App**, not from a separate OAuth App. Leave **Scope** empty: a GitHub App's access is decided by where it is installed, and it ignores OAuth scopes entirely.
**Store tokens for persistent API access** in General settings has to be turned on, because it is off by default and the platform reads the stored GitHub token from the Secret Vault.
The same page shows the **Redirect URI (Callback URI)** that GitHub must send users back to:
```text
https:///callback/
```
The connector ID is generated when the connector is created, so this cannot be known in advance. Copy it and add it to your GitHub App's callback URL list. A GitHub App accepts several, so adding it after the fact disturbs nothing.
::warning
Set
`logto.secrets.secretVaultKek`
before Logto first starts and never change it, because it encrypts every stored GitHub token.
::
Under **Sign-in and account** → **Sign-up and sign-in**, add GitHub under **Social sign-in** and leave the identifier lists empty, so "Continue with GitHub" is the only way in. Leave **Enable user registration** on unless you want an invite-only installation.
### Account API
On the **Account center** tab of that same page, switch the account API on. Every self-service field underneath it can stay **Off**.
## The GitHub App
The App is what lets the platform read source repositories and hear about pushes. Create it under the account or organization that owns the repositories you want to deploy, and give it these settings in full.
### URLs
Three of them, and they point in two different directions, which is the part people get wrong:
| Setting | Value |
| ------------ | -------------------------------------------------------------------------------- |
| Callback URL | `https:///callback/` |
| Setup URL | `https:///auth/github/setup`, with "Redirect on update" enabled |
| Webhook URL | `https:///webhooks/github` |
The callback goes to the **identity provider**, not to the platform, because the identity provider runs the GitHub sign-in handshake. The other two go to the platform. You get the connector id when you create the GitHub connector, so fill the callback in afterwards.
### Webhook
| Setting | Value |
| ---------------- | ------------------------------------------------------------------ |
| Webhook | Active |
| Content type | `application/json` |
| SSL verification | Enabled |
| Secret | The same value as `GITHUB_WEBHOOK_SECRET` in your platform secrets |
Subscribe to exactly one event: **Push**. That is what triggers an automatic deploy on a branch the platform is watching. Nothing else is read, so leave the rest unsubscribed.
### Permissions
The platform only ever reads your code, so every permission it needs is read-only:
| Permission | Level | Used for |
| ------------------------- | --------- | ---------------------------------------------------------- |
| Repository → Contents | Read-only | Cloning source at build time, reading commits and branches |
| Repository → Metadata | Read-only | Mandatory for any App, and how repositories are listed |
| Account → Email addresses | Read-only | The user's email at sign-in |
### Private key
At the bottom of the App's General page, click **Generate a private key**. GitHub downloads a `.pem` and shows it to you once, so keep it somewhere safe or generate a fresh one later. Its contents go into `githubPrivateKey` in the platform secrets, and the conductor reads it back from the path in `GITHUB_PRIVATE_KEY_PATH`.
Note the **App ID**, the **Client ID**, and a generated **client secret** from the same page while you are there. The client secret is also what the identity provider's GitHub connector needs.
Finally, install the App on the account or organization holding the repositories you want to deploy.
## The platform chart
With the identity provider configured, the platform chart has everything it needs. Its values file is where the identifiers you collected come together:
| Value | From |
| ------------------------------------------------------------------------------ | --------------------------------------------------------------------------- |
| `OIDC_ISSUER_URL` | `https:///oidc` |
| `OIDC_AUDIENCE` | The API resource identifier |
| `OIDC_CLIENT_ID` | The Dashboard application |
| `OIDC_CLI_CLIENT_ID` | The CLI application |
| `LOGTO_M2M_APP_ID` and `LOGTO_M2M_APP_SECRET` | The M2M application |
| `GITHUB_APP_ID`, `GITHUB_APP_SLUG`, `GITHUB_CLIENT_ID`, `GITHUB_CLIENT_SECRET` | The GitHub App |
| `WORKLOAD_DOMAIN`, `DATABASE_DOMAIN` | Your workload domain |
| `IP_ADDRESS` | The gateway address from the previous step |
| `routes.enabled` and `routes.hostname` | Your platform domain. These default to off and to our hostname, so set both |
Which comes together as `values.yaml`:
```yaml
registryPull:
host: "10.96.100.100:5000" # the Zot clusterIP you pinned
username: reader
routes:
enabled: true
hostname:
conductor:
registryHost: lucity-infra-zot.lucity-system.svc.cluster.local:5000
registryUsername: builder
buildkit:
enabled: true
storageSize: 20Gi
env:
OIDC_ISSUER_URL: https://id./oidc
OIDC_AUDIENCE: https://api.
OIDC_CLIENT_ID:
OIDC_CLI_CLIENT_ID:
OIDC_CALLBACK_URL: https:///auth/callback
DASHBOARD_URL: https:///app
GITHUB_APP_ID: ""
GITHUB_APP_SLUG:
GITHUB_CLIENT_ID:
GITHUB_PRIVATE_KEY_PATH: /secrets/github/github-app.pem
LOGTO_ENDPOINT: http://lucity-infra-logto.lucity-system.svc.cluster.local:3001
VICTORIA_METRICS_URL: http://lucity-infra-victoria-metrics-single-server.lucity-system.svc.cluster.local:8428
INTERNAL_JWT_PRIVATE_KEY_PATH: /secrets/internal-jwt/private.pem
INTERNAL_JWT_PUBLIC_KEY_PATH: /secrets/internal-jwt/public.pem
REGISTRY_URL: lucity-infra-zot.lucity-system.svc.cluster.local:5000
REGISTRY_PUSH_URL: lucity-infra-zot.lucity-system.svc.cluster.local:5000
REGISTRY_PULL_URL: 10.96.100.100:5000
REGISTRY_AUTH_SECRET: lucity-registry-auth
WORKLOAD_DOMAIN:
DATABASE_DOMAIN: db.
IP_ADDRESS: ""
OVH_PROJECT_ID: ""
OVH_ENDPOINT: ovh-eu
OVH_REGION: GRA
envSecret:
SESSION_SECRET: SESSION_SECRET
GITHUB_CLIENT_SECRET: GITHUB_CLIENT_SECRET
WEBHOOK_SECRET: GITHUB_WEBHOOK_SECRET
LOGTO_M2M_APP_ID: LOGTO_M2M_APP_ID
LOGTO_M2M_APP_SECRET: LOGTO_M2M_APP_SECRET
OVH_APPLICATION_KEY: OVH_APPLICATION_KEY
OVH_APPLICATION_SECRET: OVH_APPLICATION_SECRET
OVH_CONSUMER_KEY: OVH_CONSUMER_KEY
cashier:
enabled: false
```
`envSecret` maps an environment variable to a key in `secrets.yaml`, which holds everything sensitive:
```yaml
secrets:
SESSION_SECRET: ""
GITHUB_WEBHOOK_SECRET: ""
GITHUB_CLIENT_SECRET: ""
REGISTRY_PASSWORD: ""
LOGTO_M2M_APP_ID: ""
LOGTO_M2M_APP_SECRET: ""
OVH_APPLICATION_KEY: ""
OVH_APPLICATION_SECRET: ""
OVH_CONSUMER_KEY: ""
githubPrivateKey: |
-----BEGIN RSA PRIVATE KEY-----
...the .pem you downloaded from the GitHub App
-----END RSA PRIVATE KEY-----
registryPull:
password: ""
internalJWT:
privateKey: |
-----BEGIN EC PRIVATE KEY-----
publicKey: |
-----BEGIN PUBLIC KEY-----
```
The internal keypair signs the tokens the control plane issues to its own build and deploy jobs. Generate it with:
```bash
openssl ecparam -name prime256v1 -genkey -noout -out internal-jwt-private.pem
openssl ec -in internal-jwt-private.pem -pubout -out internal-jwt-public.pem
```
Object storage credentials are also required, and the conductor will not start without them. Today the only implemented backend is OVH, so you need `OVH_APPLICATION_KEY`, `OVH_APPLICATION_SECRET`, `OVH_CONSUMER_KEY` and `OVH_PROJECT_ID`. Scope them to the one project the platform should use, because it creates and deletes buckets and credentials there on its own.
Then install, the same way as the infra chart and with the same caution about versions:
```bash
helm upgrade --install lucity oci://ghcr.io/zeitlos/lucity/charts/lucity \
--version -n lucity-system \
-f values.yaml -f secrets.yaml
```
A healthy conductor says so plainly in its logs, and the line worth looking for is the one proving it reached the identity provider and found your roles:
```text
INFO logto org roles cached admin=... member=...
```
## Verifying the install
A few checks, fastest first:
```bash
kubectl -n lucity-system get pods
kubectl -n lucity-system get certificate
kubectl -n lucity-system get gateway lucity-gateway \
-o jsonpath='{range .status.listeners[*]}{.name}{": "}{range .conditions[*]}{.type}={.status} {end}{"\n"}{end}'
```
Every certificate `True`, and every listener `Programmed=True`. A listener stuck unprogrammed is nearly always waiting on its certificate.
Then the platform itself, which should answer on each path the route table sends somewhere different:
```bash
curl -o /dev/null -w '%{http_code}\n' https:///
curl -o /dev/null -w '%{http_code}\n' https:///app/
curl https:///auth/config
```
`/auth/config` is the most useful of the three, because it echoes back the issuer, audience, and CLI client ID the conductor actually loaded.
Finally, confirm nodes can pull from the registry by asking for an image that does not exist:
```bash
kubectl run pulltest --image=:5000/does-not-exist:test --restart=Never --command -- true
kubectl describe pod pulltest
```
An auth or not-found error is success, because containerd reached the registry and got an answer. Delete the pod afterwards.
Sign in at `https:///app/`, and the first account to authenticate gets its own workspace.
## Reference profiles
The repository carries the complete values files for the clusters we run, under `deployments/`. They are the fastest way to see how the pieces fit together, and the closest thing to a known-good starting point:
- `deployments/lucity-prod/` is the production profile, with billing, backups, analytics, alerting, and database exposure all switched on
- `deployments/lucity-dev/` is a smaller three-node profile with those switched off, which is roughly the minimum that still runs real workloads
- `deployments/minikube/` is the local development profile
Copy whichever is closest, then work through the values that name a domain, a storage class, or a credential.
# Data Processing Agreement
**Effective date:** July 24, 2026
**Last updated:** October 1, 2026
This Data Processing Agreement ("DPA") forms part of the [Terms of Use](https://lucity.cloud/legal/terms-of-use) between you ("Customer", "Controller") and the operator of Lucity ("Processor", "we", "us"):
zeitlos.software Inh. Christian Blättler
CHE‑439.475.468
Mattenhofstrasse 5, 3007 Bern, Switzerland
It governs the processing of personal data that we carry out on your behalf when you use lucity.cloud to build, deploy, and run your applications. It applies where you are subject to the EU General Data Protection Regulation (GDPR), the Swiss Federal Act on Data Protection (FADP/nDSG), or both.
Where you act as a processor for your own customers, references to "Controller" also cover your role as their processor, and we act as your sub-processor.
---
## 1. Roles and Scope
- You are the **controller** of the personal data your applications process (for example, data about your end users). We are the **processor**, acting only on your documented instructions.
- Your use of the platform, including the configuration of your workloads, environment variables, and services, constitutes your documented instructions. Additional instructions must be agreed in writing.
- We process personal data only to provide the service described in the Terms of Use and do not process it for our own purposes.
- We handle your **account and billing data** as a controller in our own right; that processing is described in the [Privacy Policy](https://lucity.cloud/legal/privacy-policy) and is outside the scope of this DPA.
## 2. Subject Matter of Processing
| Item | Description |
| ------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
| **Subject matter** | Hosting and running the Customer's applications and their data on the platform |
| **Duration** | For the term of the Customer's use of the service |
| **Nature and purpose** | Building, deploying, storing, backing up, and executing the Customer's workloads, databases, key-value stores, and object storage |
| **Types of personal data** | Determined by the Customer. Any personal data the Customer's applications store or process on the platform |
| **Categories of data subjects** | Determined by the Customer. Typically the Customer's own users and contacts |
We have no control over, and do not inspect, the categories of personal data or data subjects the Customer chooses to process through their workloads.
## 3. Our Obligations
We will:
- **Process only on instructions.** Process personal data solely on your documented instructions, including regarding international transfers, unless required otherwise by applicable law, in which case we will inform you unless the law prohibits it.
- **Unlawful instructions.** Inform you immediately if, in our opinion, an instruction infringes the GDPR, the FADP, or other applicable data protection law.
- **Confidentiality.** Ensure that personnel authorized to process the data are bound by confidentiality.
- **Security.** Implement appropriate technical and organizational measures as described in Annex 1.
- **Sub-processors.** Use sub-processors only under the conditions in Section 4.
- **Assist with data-subject rights.** Taking into account the nature of the processing, assist you by appropriate measures in responding to requests from data subjects exercising their rights.
- **Assist with compliance.** Assist you in ensuring compliance with your security, breach-notification, and data-protection-impact-assessment obligations, taking into account the information available to us.
- **Breach notification.** Notify you without undue delay after becoming aware of a personal data breach affecting your data, with the information reasonably available to us.
- **Deletion or return.** On termination, delete or return the personal data as described in Section 5.
- **Audits.** Make available the information necessary to demonstrate compliance with this DPA and allow for and contribute to audits, including inspections, conducted by you or an auditor you mandate, subject to reasonable notice, confidentiality, and no undue disruption to our operations.
## 4. Sub-processors
You provide general authorization for us to engage the sub-processors listed below to process personal data on your behalf. We impose data-protection obligations on each sub-processor that are no less protective than those in this DPA, and we remain responsible for their performance.
| Sub-processor | Purpose | Location |
| ------------- | --------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------- |
| **Hetzner** | Core infrastructure hosting (compute, workloads, databases) | Germany (EU) |
| **OVHcloud** | Object storage hosting and database backups | France (EU) |
| **Bunny** | Edge network in front of your applications (TLS termination and proxying of all HTTP and WebSocket traffic) and content delivery for public buckets | EU company; global edge network |
| **Anthropic** | Internal operations and incident investigation: AI-assisted analysis of platform metadata and logs. Anthropic does not train models on this data | United States, under Standard Contractual Clauses |
We will give you at least 30 days' notice, by email or platform notification, before adding or replacing a sub-processor. If you reasonably object on data-protection grounds, we will work with you in good faith to address the concern, and if we cannot, you may terminate the affected service.
## 5. Deletion and Return
On termination of the service, or on your request, we will delete the personal data we process on your behalf within 30 days, unless applicable law requires us to retain it. When you delete a project or account, the associated data is removed within 30 days. Because the platform is ejectable, you can export your configuration and data before termination.
## 6. International Transfers
Personal data processed on your behalf is hosted in the European Union (see the [Privacy Policy](https://lucity.cloud/legal/privacy-policy)). Where a sub-processor transfers personal data outside the EU or Switzerland, that transfer is covered by an appropriate safeguard, such as the EU Standard Contractual Clauses together with, for data subject to the FADP, the recognition of those clauses by the Swiss Federal Data Protection and Information Commissioner.
## 7. Swiss FADP
Where the FADP applies, references to the GDPR are read as references to the equivalent provisions of the FADP, "personal data" includes data relating to legal entities to the extent protected by the FADP, and the supervisory authority is the Federal Data Protection and Information Commissioner (FDPIC).
## 8. Liability and Precedence
The liability limitations in the Terms of Use apply to this DPA. If there is a conflict between this DPA and the Terms of Use regarding the processing of personal data, this DPA prevails.
## 9. Contact
For data-protection matters and to exercise controller rights under this DPA:
---
## Annex 1: Technical and Organizational Measures
We maintain measures appropriate to the risk, including:
- **Encryption in transit** using TLS for connections to the platform and WireGuard for traffic between cluster nodes.
- **Tenant isolation** through namespace-level separation of workspaces in Kubernetes, with network policies restricting cross-tenant access.
- **Access control** on a least-privilege, role-based basis, with authentication through our self-hosted identity provider.
- **Secrets handling** through Kubernetes secrets, kept separate from application code and logs.
- **Resilience** through backups of managed databases, stored with a different provider than primary hosting, and replication for databases that run more than one instance.
- **Monitoring and logging** of platform activity to detect and respond to security events.
- **Self-hosted core services** (identity, container registry, deployment tooling) within our own cluster, limiting exposure to external processors.
# Privacy Policy
**Effective date:** March 16, 2026
**Last updated:** October 1, 2026
This privacy policy explains how lucity.cloud ("Lucity", "we", "us") collects, uses, and protects your data.
**Operator:**
zeitlos.software Inh. Christian Blättler
CHE‑439.475.468
Mattenhofstrasse 5, 3007 Bern, Switzerland
**Contact:**
---
## 1. What We Collect
### Account Data
When you sign up, we collect:
- **Email address** and **display name** (via our authentication service)
- **GitHub account details** (username, user ID, email address, avatar) when you sign in with GitHub, and access to the repositories you connect for builds
- **Billing information** (name, billing address, payment method) processed by Stripe
### Usage Data
When you use the platform, we process:
- **Project and deployment metadata**: project names, environment configurations, build logs, deployment status
- **Resource consumption**: CPU, memory, disk, and egress usage for billing
### Analytics
We use [Rybbit](https://rybbit.com) (self-hosted) for website analytics. Rybbit is cookie-free, does not collect personal data, and does not track users across websites. No cookie consent banner is required.
### What We Do Not Collect
- We do not read or store your application source code beyond what is needed during the build process
- We do not use cookies for tracking
- We do not build advertising profiles
- We do not sell your data
## 2. How We Use Your Data
- **Provide the service**: run your workloads, manage deployments, process builds
- **Billing**: calculate resource usage, process payments, send invoices
- **Communication**: service notifications, security alerts, billing updates
- **Improve the platform**: aggregated, anonymized usage patterns
## 3. Data Processing and Storage
The platform core, your workloads, and their databases run on **Hetzner Cloud** in Nuremberg, Germany. Object storage buckets are hosted on **OVHcloud** in Gravelines, France, and database backups on OVHcloud in Paris, France. Both are in the **European Union**.
Our infrastructure services (authentication, container registry, deployment tooling, analytics) are **self-hosted** within our own cluster. The third parties listed below are the only external processors that handle data on our behalf.
### Third-Party Processors
| Provider | Purpose | Data Shared | Privacy Info |
| ------------- | ------------------------------------------------ | -------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------- |
| **Stripe** | Payment processing | Name, email, billing address, payment method | [stripe.com/privacy](https://stripe.com/privacy) |
| **Hetzner** | Core infrastructure hosting (EU) | Platform data, workloads, and databases | [hetzner.com/privacy-policy](https://www.hetzner.com/privacy-policy/) |
| **OVHcloud** | Object storage and database backups (EU) | Files you store in buckets; backups of your databases | [ovhcloud.com/en/personal-data-protection](https://www.ovhcloud.com/en/personal-data-protection/) |
| **Bunny** | Edge network for applications and public buckets | Requests to and responses from your applications and public buckets, including visitor request metadata (IP address, user agent) | [bunny.net/privacy](https://bunny.net/privacy) |
| **Anthropic** | Internal operations and incident investigation | Platform metadata and logs needed for an investigation, such as project names, resource usage, and service logs | [anthropic.com/legal/privacy](https://www.anthropic.com/legal/privacy) |
Stripe may process data outside the EU and maintains EU Standard Contractual Clauses for international transfers. Anthropic processes data in the United States under EU Standard Contractual Clauses and does not use it to train models. Bunny operates a global edge network, so requests to applications and public buckets may be processed at edge locations outside the EU, and publicly served bucket content may be cached there. We do not share data with any other third parties.
### Data Your Applications Process
For your **account and billing data**, we are the data controller, and this policy describes how we handle it. For personal data that **your applications** process about **your own end users**, you are the controller and we act only as your processor, running your workloads on your instructions. That relationship is governed by our [Data Processing Agreement](https://lucity.cloud/legal/data-processing-agreement). We do not access, use, or disclose that data except as needed to operate the platform.
## 4. Data Retention
- **Account data**: retained while your account is active. Deleted within 30 days of account deletion.
- **Build artifacts and logs**: retained while the associated project exists.
- **Billing records**: retained for 10 years as required by Swiss law (OR Art. 958f).
- **Analytics data**: aggregated and anonymous; no personal data retained.
## 5. Your Rights
Under the Swiss Federal Act on Data Protection (nDSG/FADP) and the EU General Data Protection Regulation (GDPR), you have the right to:
- **Access** your personal data
- **Correct** inaccurate data
- **Delete** your account and associated data
- **Export** your data (platform data is ejectable by design)
- **Object** to processing
- **Withdraw consent** where processing is based on consent
To exercise any of these rights, email .
## 6. Security
We protect your data with:
- TLS for connections to the platform and WireGuard encryption between cluster nodes
- Database backups stored with a different provider than primary hosting
- Role-based access control
- Isolated tenant workspaces (namespace-level separation in Kubernetes)
## 7. Children
Lucity is not directed at children under 16. We do not knowingly collect data from children under 16. If you believe a child has provided us with personal data, please contact us.
## 8. Changes
We may update this policy. Material changes will be communicated via email or platform notification. Continued use after changes constitutes acceptance.
## 9. Contact and Supervisory Authority
For privacy questions:
If you believe your data protection rights have been violated, you may lodge a complaint with:
- **Switzerland:** [Federal Data Protection and Information Commissioner (FDPIC)](https://www.edoeb.admin.ch/)
- **EU:** Your local data protection authority
# Terms of Use
**Effective date:** March 16, 2026
**Last updated:** July 24, 2026
These terms govern your use of lucity.cloud ("Lucity", "the platform", "the service"). By creating an account, you agree to these terms. If you use the service on behalf of an organization, you represent that you are authorized to bind that organization, and "you" refers to that organization.
**Operator:**
zeitlos.software Inh. Christian Blättler
CHE‑439.475.468
Mattenhofstrasse 5, 3007 Bern, Switzerland
**Contact:**
---
## 1. The Service
Lucity is a platform-as-a-service (PaaS) that deploys and runs your applications on Kubernetes. The platform manages builds, deployments, and infrastructure on your behalf.
Lucity is open source under the AGPL-3.0 license. You may self-host it on your own infrastructure free of charge under the terms of that license. These terms apply only to the hosted service at lucity.cloud, not to your own self-hosted deployments.
## 2. Accounts
- You must provide accurate information when creating an account.
- You are responsible for maintaining the security of your account credentials and for all activity under your account.
- You must be at least 16 years old to use the service.
- One person or legal entity per account. Workspaces provide multi-user collaboration.
## 3. Plans and Billing
### Subscription
Lucity offers paid subscription plans (currently Hobby at EUR 5/month and Pro at EUR 25/month). Each plan includes a monthly credit allowance applied toward resource usage.
### Resource Usage
Resource consumption (CPU, memory, disk, egress) is metered continuously. Usage beyond included credits is billed at the end of each billing cycle at the published rates.
### Payment
Payments are processed by Stripe. You authorize recurring charges to your payment method. All prices are in EUR and are exclusive of any applicable taxes (such as VAT/MWST). Where a tax applies to your purchase, it will be added at the applicable rate, and you are responsible for it. If your payment fails, we may suspend the service after reasonable notice until payment is made.
### Cancellation
You may cancel your subscription at any time. The service remains available until the end of the current billing period. We do not offer refunds for partial billing periods.
### Price Changes
We may adjust pricing with 30 days' notice. Continued use after the effective date constitutes acceptance. If you disagree, cancel before the change takes effect.
## 4. Acceptable Use
You agree not to use the platform, and not to allow anyone using your account or workloads to use the platform, to:
- Violate any applicable law or regulation
- Infringe on intellectual property rights or other rights of third parties
- Store, host, or distribute content that is unlawful, including child sexual abuse material
- Distribute malware, spam, or phishing content, or operate botnets, command-and-control infrastructure, or open mail relays
- Originate denial-of-service attacks, port scanning, or intrusion attempts against any system
- Operate anonymizing proxies or services intended to conceal the origin of abusive traffic
- Perform cryptocurrency mining
- Run workloads that consume excessive shared resources in a way that degrades service for others
- Attempt to access other users' data or workloads, or to circumvent tenant isolation
- Reverse-engineer, attack, or probe the platform's infrastructure
We reserve the right to suspend or terminate accounts that violate these terms.
### Reporting Abuse
To report content or activity on the platform that you believe violates these terms, contact ****. We review reports and, where appropriate, remove content or suspend the responsible account. We may act immediately in cases of severe abuse or legal risk.
## 5. Your Data and Content
- **You own your data.** We claim no intellectual property rights over your source code, configurations, or application data.
- **License to operate.** To provide the service, you grant us a limited, non-exclusive, worldwide license to host, copy, build, store, process, and transmit your content, solely as needed to operate the platform and run your workloads on your behalf. This license ends when the content is deleted from the platform.
- **Ejectability.** You can export your platform configuration (Helm charts and environment values) at any time via the eject feature. The exported output is fully self-contained with no Lucity dependencies.
- **Deletion.** When you delete a project or account, associated data (builds, configurations, deployments) is removed within 30 days.
## 6. Your Responsibilities
You are solely responsible for:
- The content, code, and workloads you deploy, and for ensuring you have all rights necessary to upload and run them.
- Compliance by your applications, and your end users, with all applicable laws, including data-protection law.
- The security and configuration of your own applications, including secrets you set as environment variables.
- Maintaining your own backups of any data you cannot afford to lose. The platform is not a backup service, and we do not guarantee against loss of your application data.
You warrant that your use of the service will comply with these terms and all applicable laws.
## 7. Platform Availability
- We aim for high availability but do not guarantee specific uptime percentages.
- The platform is provided "as is". Scheduled maintenance will be announced in advance when possible.
- Lucity is non-intrusive: platform downtime does not affect your running workloads. Your applications continue to run on Kubernetes independently.
## 8. Limitation of Liability
To the maximum extent permitted by Swiss law:
- Lucity is provided **"as is"** without warranties of any kind, whether express or implied.
- We are not liable for indirect, incidental, or consequential damages (including lost profits, data loss, or business interruption).
- Our total liability is limited to the amount you paid for the service in the 12 months preceding the claim.
- We are not responsible for outages, data loss, or issues caused by third-party services, your application code, or circumstances beyond our control.
Nothing in these terms excludes or limits liability that cannot be excluded or limited under Swiss law, including liability for unlawful intent or gross negligence under Art. 100 of the Swiss Code of Obligations.
## 9. Indemnification
You will defend, indemnify, and hold harmless zeitlos.software and its operator against any third-party claim, demand, loss, or damage (including reasonable legal costs) arising out of or related to:
- Your content, code, or workloads
- Your use of the service in breach of these terms or any applicable law
- Your violation of the rights of a third party
We will notify you of any such claim, and you may control its defense, provided that any settlement that imposes obligations on us requires our prior written consent.
## 10. Intellectual Property
- **Lucity** is open-source software licensed under AGPL-3.0. The source code is available at [github.com/zeitlos/lucity](https://github.com/zeitlos/lucity).
- The Lucity name, logo, and branding are trademarks of zeitlos.software.
- Your use of the platform does not grant you rights to our trademarks.
## 11. Suspension and Termination
- **By you:** Cancel your subscription at any time through the billing portal or by contacting us.
- **By us:** We may suspend or terminate your account for violation of these terms or for non-payment, with notice where reasonably possible. In cases of severe abuse or legal risk, we may act immediately.
- **Effect:** Upon termination, your workloads will be stopped and data deleted within 30 days. We recommend ejecting your configuration before cancellation.
## 12. Data Protection
Our handling of personal data is described in our [Privacy Policy](https://lucity.cloud/legal/privacy-policy). Where you use the platform to process personal data for which you are the controller (for example, data of your own end users), our [Data Processing Agreement](https://lucity.cloud/legal/data-processing-agreement) applies and forms part of these terms.
## 13. Changes to These Terms
We may update these terms. Material changes will be communicated via email or platform notification at least 14 days before taking effect. Continued use after the effective date constitutes acceptance.
## 14. Governing Law and Jurisdiction
These terms are governed by the laws of Switzerland, excluding its conflict-of-law rules and the UN Convention on Contracts for the International Sale of Goods (CISG). The exclusive place of jurisdiction for any dispute is Bern, Switzerland. If you are a consumer, mandatory consumer-protection law may entitle you to bring proceedings at your place of residence, and nothing here removes that right.
## 15. Miscellaneous
- **Force majeure.** We are not liable for any failure or delay caused by events beyond our reasonable control, including outages of third-party infrastructure, network failures, or acts of government.
- **Assignment.** You may not assign these terms without our consent. We may assign them to a successor of our business.
- **Severability.** If any provision is held unenforceable, the remaining provisions stay in effect.
- **Entire agreement.** These terms, together with the Privacy Policy and, where applicable, the Data Processing Agreement, are the entire agreement between you and us regarding the service.
## 16. Contact
Questions about these terms:
# Agencies
Every client engagement ends with the same two questions. Where does our data live, and what happens to all of this when you walk away? Most platforms make the first question awkward and the second one impossible, which is how "we'll migrate off later" becomes someone else's problem.
::feature-cards
---
items:
- icon: i-lucide-gauge
title: Ship at PaaS speed
text: Connect the client's repository and deploy. No Dockerfile, no pipeline to
build, no infrastructure ticket.
- icon: i-lucide-map-pin
title: Answer the hosting question
text: European infrastructure today, with Swiss residency planned. A straight
answer for the client's legal team.
- icon: i-lucide-package-open
title: Hand it over intact
text: Eject to standard Helm charts and values. The client runs it themselves,
without you in the loop.
---
::
## The handover problem
You need PaaS speed while you build. Your client, especially in banking, insurance or the public sector, needs data residency and the ability to operate the thing after your contract ends.
Traditional platforms give you the first and quietly deny the second. Deployment config, environment variables, promotion workflow, database setup: all proprietary, all stuck where they are. When the engagement ends you hand over a source repository and a prayer, and the client's new team starts from a blank page.
Raw Kubernetes is the other extreme. Your team should not need to become infrastructure engineers to ship a marketing site with a database behind it. You have deadlines and a fixed budget, not a platform engineering department.
::flow-diagram
---
nodes:
- label: Client repository
sub: Their code, untouched by the platform
icon: i-simple-icons-github
- label: Lucity
sub: Builds, deploys, manages environments
icon: i-lucide-boxes
tone: primary
- label: Client's own cluster
sub: Helm release, database, bucket
icon: i-lucide-server
caption: The same artefacts run the app during the engagement and after it.
---
::
## What the engagement looks like
::step-flow
---
steps:
- title: Connect the repository
text: Lucity detects the framework and builds from source. First deploy takes
minutes, not a sprint.
- title: Review with the client
text: Give each environment its own URL. Stakeholders click a link instead of
asking you to "put it on the test server".
- title: Promote, don't rebuild
text: The image that passed staging is the image that goes to production. Same
digest, no surprise rebuild on launch day.
- title: Hand over and leave
text: Eject produces the chart, the values, and a setup guide. The client points
their own tooling at it and carries on.
---
::
## What the client actually receives
Eject is not an export button that produces a CSV and a shrug. It writes out the deployment as plain infrastructure-as-code:
::feature-cards
---
columns: 2
items:
- icon: i-lucide-file-code
title: The chart and its values
text: The same Helm chart that was running the application, with the values
computed for each environment.
- icon: i-lucide-layers
title: Every environment
text: Development, staging and production, each with its own configuration, kept
separate exactly as they ran.
- icon: i-lucide-database
title: Databases and storage
text: PostgreSQL clusters and buckets described as standard operator resources,
not platform-specific magic.
- icon: i-lucide-book-open
title: A setup guide
text: Prerequisites, the commands to apply it, and where to change things
afterwards.
---
::
There is no Lucity dependency in the output. That is the part worth saying out loud in a pitch: the client is not buying a dependency on your agency or on us.
## Why this wins work
Ejectability is a commercial argument, not just a technical one. It turns the awkward end-of-contract conversation into a selling point: the client keeps the infrastructure, their in-house team can take over on a Monday, and nothing has to be rebuilt to make that happen.
Agencies that hand over cleanly get called back. That is the whole pitch.
# Startups & Small Teams
You are five to thirty people and you ship every day. You picked a PaaS because it got out of the way, and it did. The nagging part is what happens later: the day you need a network policy the dashboard does not expose, or an enterprise customer asks where the data physically sits.
::feature-cards
---
items:
- icon: i-lucide-zap
title: Deploy on day one
text: Connect a repository, get a URL. Nobody on the team has to learn
Kubernetes to ship a feature.
- icon: i-lucide-unlock
title: Nothing is hidden
text: Underneath it is Helm, PostgreSQL and Gateway API. When you need to look,
there is something to look at.
- icon: i-lucide-wallet
title: Predictable bill
text: Pay for compute and storage, not per seat. Self-host the whole platform if
the maths works out better.
---
::
## The graduation tax
Migrating off a closed platform is rarely a migration. It is a rebuild. The deployment knowledge lives in a dashboard, the environment config lives in a proprietary format, the promotion workflow lives in someone's head, and none of it comes with you.
That is usually a quarter of engineering time that produces exactly zero customer value, paid at the worst possible moment: right when the thing that forced the move is already urgent.
::flow-diagram
---
nodes:
- label: Managed PaaS
sub: Fast start, proprietary config
icon: i-lucide-rocket
tone: muted
- label: The wall
sub: Networking, residency, cost, control
icon: i-lucide-octagon-alert
tone: muted
- label: Rebuild on Kubernetes
sub: A quarter of work, no new features
icon: i-lucide-hammer
tone: muted
caption: The usual path, and the one that skips the rebuild.
---
::
::flow-diagram
---
nodes:
- label: Lucity
sub: Same click-to-deploy experience
icon: i-lucide-rocket
tone: primary
- label: The same wall
sub: Now it is just configuration
icon: i-lucide-settings-2
- label: Your own cluster, if you want
sub: Eject, keep the charts, keep going
icon: i-lucide-server
tone: primary
---
::
## Grow into it, not out of it
You do not need to know Kubernetes on day one. That is the point of the dashboard. But when you do want to know, the answer is not "the platform handles that".
::step-flow
---
steps:
- title: Start in the dashboard
text: Services, databases, variables and domains, all click-driven. The team
ships features while you think about nothing.
- title: Read the values
text: Every service is a Helm release with values you can inspect. The
abstraction is thin enough to see through.
- title: Take over the parts you care about
text: Set your own resources, health checks, start commands and scaling as your
requirements sharpen.
- title: Eject when it makes sense
text: One command hands you the charts and the guide. Moving to your own cluster
stops being a project.
---
::
What your team learns along the way is Kubernetes and Helm, not the quirks of one vendor's control panel. Those skills follow them to the next company. That is a hiring argument as much as a technical one.
## The cost conversation
Lucity Cloud bills for what you actually run: compute, storage, and the databases you provision. There is no per-seat pricing, so adding a designer to the workspace does not change the invoice.
If your burn rate is the thing keeping you up, the other option is genuinely available: Lucity is open source under AGPL-3.0, so you can run the whole platform on your own cluster and pay your infrastructure provider directly. Same product, different bill. Most teams start on the hosted version and never move, which is fine, but the exit stays open either way.
# Platform Teams
Your developers want to push code and see it running. Your security team wants everything on the cluster you already audit. Somewhere between those two positions sits a wiki nobody has updated since the last reorg, and a Slack thread asking who can deploy to staging.
::feature-cards
---
items:
- icon: i-lucide-hand-metal
title: Self-service for developers
text: Projects, environments, variables, logs and rollbacks in a dashboard,
without a ticket or a pairing session.
- icon: i-lucide-shield-check
title: Your cluster, your rules
text: Runs on the Kubernetes you already operate, with the network policies,
quotas and admission rules you already enforce.
- icon: i-lucide-file-search
title: Auditable by design
text: AGPL-3.0, so your security team can read the code instead of taking a
vendor's word for it.
---
::
## The build-versus-buy trap
An internal developer platform is not a project, it is a staffing commitment. A portal gives you a catalog but no deployment path. A homegrown CLI works beautifully until the person who wrote it changes teams. Meanwhile the gap between what developers want and what the platform team can staff is where the shadow tooling grows.
::flow-diagram
---
nodes:
- label: Developers
sub: Push code, want a URL
icon: i-lucide-users
- label: Lucity
sub: The self-service layer you did not have to build
icon: i-lucide-layout-dashboard
tone: primary
- label: Your Kubernetes
sub: Standard Helm releases and operators
icon: i-lucide-server
caption: Same infrastructure, one fewer layer for your team to maintain.
---
::
## What it puts on your cluster
Nothing exotic. That is the design constraint, because anything exotic becomes your problem at 3am.
::feature-cards
---
columns: 2
items:
- icon: i-lucide-file-code
title: Helm releases
text: One release per project and environment. `helm get values` works, and so
does everything else your team already knows.
- icon: i-lucide-database
title: Operator-managed databases
text: PostgreSQL through a well-known operator rather than a bespoke controller
nobody else has heard of.
- icon: i-lucide-network
title: Gateway API routing
text: The Kubernetes-native successor to Ingress, with certificates issued by
the cert-manager you already run.
- icon: i-lucide-tags
title: Labels, not a database
text: Platform state lives in Kubernetes objects and labels. There is no central
database holding the truth hostage.
---
::
Because everything is standard, your existing tooling still applies. Policies, scanners, cost reporting and dashboards keep working on the workloads Lucity creates, because to them it is all just Kubernetes.
## The architecture review answer
The question that decides these evaluations is rarely "does it work". It is "what happens when we want out".
::step-flow
---
steps:
- title: Read the code
text: Open source under AGPL-3.0. No black boxes to reason about, no phone-home
to explain to your CISO.
- title: Run it where you want
text: Your cluster, your region, your compliance boundary. The hosted version
exists if you would rather not.
- title: Keep the workloads if you drop the platform
text: Eject writes out the charts and values. Applications keep running while
you decide what replaces the dashboard.
- title: Survive a platform outage
text: The control plane is not in the request path. If Lucity is down, the
workloads it deployed keep serving traffic.
---
::
That last one is worth dwelling on. A platform that has to be healthy for your production traffic to flow is a new tier-one dependency. This one is not: it deploys and manages, then gets out of the way.
# Lucity vs Railway: Open-Source Railway Alternative
Railway is excellent. Polished UI, fast deploys, great developer experience. If you want a managed PaaS and don't mind the lock-in, it's a solid choice. Here's where we think Lucity offers something different.
## Where Railway Excels
Let's be honest: Railway does a lot of things well.
- **Beautiful dashboard**: Railway's UI is genuinely one of the best in the PaaS space. Clean, responsive, well-designed. The canvas-style project view is clever and intuitive.
- **Fast iteration speed**: deploy in seconds, see logs immediately, iterate rapidly. The feedback loop is tight.
- **Mature ecosystem**: templates, marketplace, integrations. Railway has had time to build a rich ecosystem around the core product.
- **Excellent documentation**: well-written, comprehensive, kept up to date. Their docs team does good work.
- **Strong community**: active Discord, helpful community members, responsive support.
We respect what Railway has built. Genuinely.
## Where Lucity Differs
### Ejectability
This is the big one. When you leave Railway, you leave with your source code and your memories. Your deployment configs, environment variables, service relationships, database configurations, promotion workflows. All proprietary, all staying behind.
Lucity stores everything as standard Helm values in a Git repository. Run `lucity eject` and you get the complete infrastructure configuration: Helm charts, ArgoCD applications, environment configs, and a setup guide. Point your own ArgoCD at the repo and keep running. No migration project, no rewrite.
Your infrastructure config should be yours. Full stop.
### Open Source
Railway is proprietary. You can't self-host it, audit the code, or modify it to fit your needs. If Railway's priorities diverge from yours (say, they sunset a feature you depend on, or change pricing), your options are to accept it or migrate.
Lucity is AGPL-3.0. Read the code. Run it on your own cluster. Fork it if you want. Contribute back if you're feeling generous. The code is yours to inspect, and the platform is yours to operate.
### Transparent Infrastructure
Railway abstracts away everything. That's great until you need to debug a networking issue, understand why a deployment failed in a specific way, or configure something the dashboard doesn't expose.
Lucity uses standard Kubernetes under the hood. `kubectl` works for everything. Helm values are readable YAML. ArgoCD gives you a full audit trail of every deployment. When something goes wrong at 2 AM, you're not waiting for a support ticket. You're reading logs with tools you already know.
### Data Residency
Railway runs on US infrastructure. For many teams, that's fine. For teams with clients in regulated industries (banking, insurance, government, healthcare), it's a dealbreaker.
Lucity Cloud runs on European infrastructure (Hetzner, Germany), with Swiss data residency coming soon. No Cloud Act concerns. When compliance asks "where does our data live?", you have a clear answer.
### Service Discovery
Railway uses proprietary variable interpolation for service communication: `${{api.DATABASE_URL}}`, `${{ServiceName.PORT}}`. It works well within Railway. It works nowhere else.
Lucity uses Kubernetes DNS. Services communicate via standard `service-name.namespace.svc.cluster.local` addresses. This pattern survives ejection, works with any Kubernetes cluster, and is documented in a thousand tutorials. One approach is portable knowledge; the other is platform trivia.
## Who Should Choose Railway
- Teams that want the most polished managed experience available today
- Teams where lock-in isn't a concern because you're committed for the long term
- Solo developers and small projects that benefit from Railway's templates and quick setup
- Teams that don't anticipate needing data residency or infrastructure portability
## Who Should Choose Lucity
- Teams that want PaaS simplicity with a real exit plan
- Teams that need EU data residency for compliance (Swiss coming soon)
- Teams that want to understand their infrastructure, not just use it
- Teams that believe their deployment configs should be portable
- Teams that prefer open-source tools they can audit and self-host
# Lucity vs Render: Open-Source Render Alternative
Render keeps things simple. Connect a repo, set some env vars, deploy. It's honest about what it is: a straightforward hosting platform that doesn't try to be everything. Here's where the approaches diverge.
## Where Render Excels
Render does several things well, and they deserve credit:
- **Genuinely simple onboarding**: Render might have the lowest barrier to entry of any PaaS. The "new user to first deploy" flow is exceptionally smooth.
- **Competitive pricing**: Render's pricing is transparent and reasonable, especially for small projects. The free tier is functional (with caveats), and paid plans don't have surprise surcharges.
- **Blueprints**: infrastructure-as-code in YAML. Define your services, databases, and environment variables in a `render.yaml` file and deploy the whole stack. It's a good idea, well executed.
- **Static site hosting**: Render handles static sites cleanly. If you just need to host a built frontend, it's hard to beat.
- **Straightforward UI**: no clutter, no unnecessary features. Render knows what it is and doesn't pretend to be more.
## Where Lucity Differs
### Ejectability
Render's Blueprints are a proprietary YAML format. They work on Render and nowhere else. If you leave, you're rewriting your infrastructure configuration from scratch, translating `render.yaml` into whatever your next platform uses.
Lucity's configuration is standard Helm values in a Git repository. Run `lucity eject` and you get Helm charts, ArgoCD configs, and a setup guide. Standard tools, standard formats, zero translation needed.
The Blueprints idea is good. The execution would be better if it used an open format.
### Kubernetes Access
Render completely abstracts the runtime. You deploy a service, and somewhere, somehow, it runs. That's great for simplicity, until you need to tune resource limits, debug a networking issue, or understand why a health check is failing in a way the dashboard doesn't explain.
Lucity gives you the full Kubernetes experience behind a friendly UI. Start with the dashboard, but when you need to dig deeper, `kubectl` is right there. The infrastructure isn't hidden. It's just presented nicely.
### Open Source
Render is proprietary. You're trusting their team to keep the platform running, keep pricing fair, and keep features you depend on. That trust has been well-earned so far, but it's still trust.
Lucity is AGPL-3.0. Self-host it on your own cluster. Read the code. Modify it. You're not trusting a vendor. You're running software you can inspect.
### Data Residency
Render runs on AWS and GCP in US and EU regions. For many teams, EU hosting is sufficient. Lucity Cloud also runs on European infrastructure (Hetzner, Germany), with Swiss data residency coming soon. For teams in regulated Swiss industries (financial services, government, healthcare), this matters.
### GitOps
Render deploys on push. That's simple and effective for many workflows. But there's no Git-based audit trail of deployments, no promotion workflows between environments, no ArgoCD-style rollback to any previous state.
Lucity uses ArgoCD for GitOps. Every deployment is a Git commit. Promotions copy image tags between environment branches. Rollback is `git revert`. The entire deployment history is auditable, diff-able, and stored in a repository you own.
For teams that need to answer "who deployed what, when, and why," this matters.
## Who Should Choose Render
- Teams that want maximum simplicity and don't need Kubernetes features
- Static site hosting and simple application deployments
- Small projects where Render's pricing is hard to beat
- Teams that value a clean, focused product over feature breadth
## Who Should Choose Lucity
- Teams that want simplicity but also want to understand and own their infrastructure
- Teams that need GitOps with full audit trails and promotion workflows
- Teams that need EU data residency for compliance (Swiss coming soon)
- Teams that anticipate growing into Kubernetes and want a smooth path there
- Teams that prefer open-source tools they can self-host and audit
# Lucity vs Heroku: Open-Source Heroku Alternative
Heroku invented the modern PaaS. `git push heroku main` changed how we deploy software. But that was 2009. A lot has happened since then.
## Where Heroku Excels
Credit where it's due. Heroku earned its place in developer history:
- **Pioneered the PaaS model**: Heroku showed the world that developers shouldn't need to manage servers to deploy applications. Every PaaS since, including Lucity, owes something to that vision.
- **Massive add-on ecosystem**: databases, monitoring, logging, search, email. Heroku's marketplace has add-ons for nearly everything. Decades of ecosystem growth.
- **Enterprise features**: Salesforce integration, private spaces, Shield for compliance. If you're in the Salesforce ecosystem, Heroku has deep integrations nobody else offers.
- **Battle-tested at scale**: Heroku has run millions of applications. The platform has seen every edge case, every failure mode, every scaling challenge.
- **Familiar to millions**: so many developers learned deployment through Heroku. That institutional knowledge has enormous value.
## Where Lucity Differs
### Modern Architecture
Heroku runs on an aging infrastructure. Dynos, buildpacks, a proprietary runtime, all architecture decisions made in a different era of cloud computing. Heroku Postgres is solid but aging. The routing layer has known limitations. Scheduling and background workers require bolt-on add-ons.
Lucity is built on Kubernetes, ArgoCD, CloudNativePG, and Gateway API: the tools the cloud-native ecosystem has converged on over the past decade. These aren't trendy choices; they're industry standards with massive communities, extensive documentation, and long-term support.
The ecosystem moved on. Your platform should too.
### Pricing
Heroku's pricing has become increasingly enterprise-focused since the Salesforce acquisition. The free tier is gone. Basic dynos start at $7/month with limited features. Production-grade setups with proper databases, logging, and monitoring add up quickly. And those add-ons? Each one has its own pricing tier.
Lucity is open source. Self-host on your own cluster and pay only for the compute you actually use. No per-dyno pricing. No add-on surcharges. No "you need Professional dynos to get preboot" upsells.
If you'd rather not manage infrastructure, Lucity Cloud offers managed hosting with transparent pricing. But the self-hosted option is always there. A sentence Heroku literally cannot say.
### Ejectability
Heroku gives you buildpacks and a `Procfile`. If you leave, you take your source code and start rebuilding everything from scratch: deployment pipelines, environment configurations, database provisioning, service discovery, monitoring setup.
Lucity gives you standard Helm charts and ArgoCD configurations. `lucity eject` produces a self-contained repository with everything you need to run independently. No Lucity dependencies, no proprietary formats, no migration project.
Leaving Heroku is a quarter-long project. Leaving Lucity is a command.
### Open Source
Heroku is proprietary, owned by Salesforce. You can't see the code, can't self-host, can't modify it. When Salesforce decides to change pricing, sunset features, or shift strategic direction (and they have, repeatedly), your options are to accept it or migrate.
Lucity is AGPL-3.0. The code is public, auditable, and forkable. Run it yourself, contribute improvements, or just read the source when something behaves unexpectedly. Open source means you're a participant, not just a customer.
### GitOps
Heroku deploys from Git pushes, which was revolutionary in 2009. But it's not GitOps. There's no declarative desired state, no ArgoCD-style reconciliation, no promotion workflows, no Git-based audit trail of what was deployed and when.
Lucity uses ArgoCD for real GitOps. The entire deployment state is in Git. Promote between environments by copying image tags. Roll back by reverting a commit. Audit who changed what by reading `git log`. It's deployment management that works with tools your team already knows.
## Who Should Choose Heroku
- Enterprises already deep in the Salesforce ecosystem
- Teams that need Heroku's mature add-on marketplace for specific integrations
- Developers who value familiarity and don't want to learn new tools
- Projects where Heroku Shield's compliance features (HIPAA, PCI) are specifically needed
## Who Should Choose Lucity
- Teams that want a modern PaaS without the Salesforce tax
- Teams that care about open source, self-hosting, or data residency
- Teams that want ejectability: the ability to leave without a migration project
- Developers who want to learn Kubernetes organically, not as a crisis response
- Cost-conscious teams that want to self-host and pay only for compute
# Lucity vs Vercel: Full-Stack Vercel Alternative
Vercel and Lucity solve different problems. Vercel is the best place to deploy Next.js. Lucity is a full-stack PaaS for applications that need more than a frontend. Honestly, they're not really competitors. They're complementary.
But since you're probably comparing options, here's an honest breakdown.
## Where Vercel Excels
Vercel is very good at what it does:
- **Next.js integration is unmatched**: they literally made Next.js. The integration between the framework and the hosting platform is seamless in a way nobody else can replicate. Server components, edge middleware, ISR, it all just works.
- **Edge functions**: deploy JavaScript/TypeScript to the edge, close to your users. For latency-sensitive frontend applications, this is genuinely powerful.
- **Preview deployments**: every pull request gets a unique URL. The implementation is polished, fast, and well-integrated with GitHub.
- **CDN-first architecture**: static assets and cached pages served from a global CDN by default. For content-heavy sites, this delivers real performance benefits.
- **Image optimization**: automatic image resizing, format conversion, and lazy loading. A small feature that saves hours of manual work.
- **Incredible frontend DX**: from `vercel dev` to the deployment dashboard, the developer experience for frontend projects is best-in-class. Full stop.
## Where Lucity Differs
### Full-Stack
Vercel is frontend-first. That's a strength. Focus enables excellence. But the moment you need something beyond the frontend, you're reaching for partners:
- Need a database? Vercel partners with Neon (Postgres) or PlanetScale (MySQL).
- Need a worker process? Use serverless functions, with cold starts and execution time limits.
- Need Redis? Partner with Upstash.
- Need a cron job? Vercel has cron, but it triggers serverless functions with the same constraints.
- Need a long-running background process? You're out of luck.
Lucity runs your entire stack on one platform: web services, API servers, background workers, cron jobs, PostgreSQL (via CloudNativePG), and Redis. No partner integrations, no function limits, no cold starts. Your Go API, your Python worker, and your database all live in the same cluster, communicating over fast internal networking.
If your application is "Next.js frontend + third-party API," Vercel is perfect. If your application is "frontend + backend + database + workers + cron jobs," Lucity handles all of it.
### Kubernetes Native
Vercel runs on proprietary infrastructure optimized for edge computing and serverless workloads. That's the right architecture for what Vercel does.
But if you need containers, custom networking, persistent processes, or anything that doesn't fit the serverless model, Vercel isn't designed for that, and it would be unfair to expect it to be.
Lucity runs on Kubernetes. Your services are containers with configurable resources, persistent connections, and no cold starts. For full-stack applications with backend services, this is the right foundation.
### Ejectability
Vercel's deployment model is tightly coupled to their platform. The build pipeline, the edge network, the serverless runtime: all Vercel-specific. If you leave, you're not taking the deployment configuration with you.
Lucity stores everything as standard Helm values in a Git repository. `lucity eject` produces Helm charts and ArgoCD configurations that work on any Kubernetes cluster. Your infrastructure config is portable by design.
### Open Source
Vercel has contributed enormously to open source (Next.js, Turbopack, SWC). That's genuine and valuable. But Vercel the hosting platform is proprietary. You can't self-host it, audit it, or run it on your own infrastructure.
Lucity is fully open source under AGPL-3.0. The platform itself, not just the tools around it. Self-host, audit, modify. It's yours to run.
### Self-Hostable
You can't self-host Vercel. For teams that need to run on specific infrastructure (compliance requirements, data residency, cost control, or just preference), this is a hard constraint.
Lucity is designed to be self-hosted. Install on your own Kubernetes cluster and run it wherever you need: on-premises, any cloud provider, any region.
## When to Use Both
Here's a pattern that actually makes sense: Vercel for your frontend, Lucity for your backend.
If your frontend team loves Vercel's DX (and they probably do), let them keep it. Deploy your Next.js app on Vercel. Deploy your API servers, workers, databases, and cron jobs on Lucity. Each platform does what it's best at.
This isn't a compromise. It's a sensible architecture. Frontend and backend have different requirements. Using different tools for each is pragmatic, not messy.
## Who Should Choose Vercel
- Frontend-heavy teams building with Next.js, Nuxt, SvelteKit, or similar frameworks
- Jamstack projects where the backend is a third-party API or headless CMS
- Teams that prioritize edge computing and global CDN performance
- Projects where serverless functions cover all backend needs
## Who Should Choose Lucity
- Full-stack teams that need databases, workers, and cron jobs alongside their web services
- Teams that want one platform for the entire application stack
- Teams that need data residency or want to self-host
- Teams that need ejectability: portable infrastructure configuration
- Backend-heavy applications with long-running processes, persistent connections, or custom networking
# Lucity vs Fly.io: Open-Source Fly.io Alternative
Fly.io runs your apps on bare-metal servers in datacenters around the world using Firecracker microVMs. It's genuinely impressive infrastructure: they built their own hypervisor stack, their own networking, their own hardware fleet. If your primary concern is running an app 40ms from every user on Earth, Fly.io takes that seriously.
But there's a question worth asking: at what cost to portability?
## Where Fly.io Excels
Credit where it's due. Fly.io has built some remarkable technology:
- **Global edge deployment**: 18 regions across 6 continents with anycast networking. Your app runs physically close to your users. For latency-sensitive applications, this is a real, measurable advantage.
- **Machines API**: Full programmatic control over VMs with subsecond boot times. Create, start, stop, and destroy VMs via REST API. This is the kind of primitive that lets you build custom orchestration: preview environments, code execution platforms, on-demand workers.
- **Own hardware**: Fly.io runs on bare metal, not cloud-on-cloud. No AWS/GCP/Azure markup. They control the full stack from hypervisor to network.
- **Multi-region by default**: Deploy the same app to Amsterdam, Tokyo, and São Paulo with a config change. The private WireGuard network between regions is well-designed.
- **Docker-native**: Bring any Docker image. No proprietary build system required (though they offer one).
## Where Lucity Differs
### Ejectability
Fly.io's `fly.toml` is a proprietary config format. The Machines API is proprietary. The networking model is proprietary. Your application is a Docker image (portable), but everything around it (deployment, routing, scaling, service discovery) is Fly-specific.
If you leave Fly.io, you take your Dockerfile and start over. There's no `fly eject` that gives you a Kubernetes deployment, a Helm chart, or an ArgoCD config. You're rebuilding your entire operational stack from scratch.
Lucity's configuration is standard Helm values in a Git repository. Run `lucity eject` and you get Helm charts, ArgoCD Application manifests, and a setup guide. Standard tools, standard formats, runs anywhere Kubernetes runs.
### GitOps
Fly.io deployment is imperative: `fly deploy`. There's no declarative state, no Git-based deployment history, no promotion workflows. You can wire up CI/CD yourself, but the platform doesn't give you a structured path from development to staging to production.
Lucity uses ArgoCD for GitOps. Every deployment is a Git commit. Promoting from staging to production copies an image tag, not a rebuild. Rolling back is `git revert`. The entire deployment history is auditable, diff-able, and stored in a repository you own.
### Pricing Transparency
Fly.io's pricing has layers. Compute is pay-per-second (straightforward), but then there's storage billed even when VMs are stopped, $2/month per IPv4 address per app, bandwidth that varies from $0.02/GB to $0.12/GB depending on region, and SSL certificates that cost money after the first ten. The free tier was removed in 2024. New users get a 2-hour or 7-day trial, whichever comes first.
Lucity Cloud has predictable pricing. Self-hosted Lucity is free; your only cost is infrastructure.
### Open Source
Fly.io is proprietary, top to bottom. The hypervisor, the orchestrator, the networking, the API. All closed source. You're trusting a company that has already made and reversed major bets (GPUs, regions, Postgres partnerships) to maintain the platform you depend on.
Lucity is AGPL-3.0. The entire platform is open source. Self-host it, read the code, contribute to it. Your deployment stack isn't controlled by a single company's strategic decisions.
### Database Story
Fly.io's Postgres journey has been bumpy. The original offering was "not managed" (their words): a Postgres instance running in a Fly Machine with no automated backups, failover, or upgrades. They launched Managed Postgres (MPG) in 2025 as a course correction, starting at $38/month. The Supabase partnership for managed Postgres was deprecated in April 2025.
Lucity uses CloudNativePG: production-grade PostgreSQL on Kubernetes with automated backups, failover, and point-in-time recovery. It ejects cleanly as a CNPG Cluster manifest.
### Kubernetes, Not Custom Infrastructure
Fly.io built impressive custom infrastructure. But custom infrastructure means custom operations, custom debugging, custom scaling behavior. When something goes wrong, you're in Fly.io-specific territory: their forums, their status page, their support team.
Lucity runs on standard Kubernetes. When something goes wrong, you have the entire Kubernetes ecosystem of tooling, documentation, and community knowledge. `kubectl`, Lens, k9s, Grafana. They all work. Skills transfer. Knowledge compounds.
## Who Should Choose Fly.io
- Applications where global latency matters more than operational portability (real-time games, edge computing, CDN-like workloads)
- Developers building custom orchestration on top of the Machines API
- Solo developers who want quick multi-region deployment without managing Kubernetes
- Teams comfortable with vendor lock-in in exchange for edge-native infrastructure
## Who Should Choose Lucity
- Teams that want to deploy globally but need to own their infrastructure config
- Teams that need GitOps with audit trails, environment promotion, and structured workflows
- Teams that want open-source infrastructure they can self-host, inspect, and modify
- Teams that need EU data residency for compliance (Swiss coming soon)
- Teams that anticipate growing and want standard Kubernetes skills to transfer
- Teams that learned from previous platform lock-in and want an exit plan from day one
# Lucity vs Coolify: Open-Source PaaS Comparison
This is the comparison we get asked about most. Both Lucity and Coolify are open-source. Both let you self-host. Both aim to replace Heroku, Railway, and Render with something you own. So what's the difference?
Architecture. Everything else follows from that.
Coolify runs Docker Compose on servers you connect via SSH. Lucity runs Kubernetes with GitOps. Same goal, fundamentally different paths to get there. Neither is universally better. They're designed for different scales and different philosophies.
## Where Coolify Excels
Coolify has earned its 38,000+ GitHub stars. Here's why:
- **Dramatically simpler setup**: One curl command installs Coolify on any server. No Kubernetes cluster, no Helm, no ArgoCD. SSH access and Docker are all you need. The time from "I have a server" to "my app is running" is measured in minutes.
- **Lower barrier to entry**: If you know Docker, you know enough to use Coolify. No Kubernetes knowledge required. The web UI is clean and approachable.
- **280+ one-click services**: Pre-configured templates for PostgreSQL, Redis, WordPress, Plausible, n8n, Gitea, and hundreds more. Click, configure, deploy.
- **Incredibly affordable**: Self-hosted is free, forever. All features included. The cloud plan is $5/month. Your real cost is just the server; a $5/month VPS can run Coolify plus a few small apps.
- **Active community**: Frequent releases, responsive maintainer, growing ecosystem. Coolify has momentum and a community that cares.
## Where Lucity Differs
### The Ceiling Problem
Coolify's simplicity comes from Docker Compose. And Docker Compose is great, until it isn't.
Need horizontal scaling? Docker Compose doesn't do that. Need rolling deployments with zero-downtime guarantees? Docker Compose does stop-old-start-new. Need to schedule workloads across multiple nodes based on resource availability? Docker Compose doesn't have a scheduler. Docker Swarm support is experimental.
This isn't a criticism of Coolify. It's a fundamental constraint of the architecture. Coolify is optimized for simplicity at small scale, and it delivers exactly that.
Lucity uses Kubernetes. Horizontal auto-scaling, rolling deployments, health-check-based routing, resource scheduling across nodes. These are built-in primitives, not wishlist features. The tradeoff is complexity: you need a Kubernetes cluster, and Kubernetes has a learning curve.
But here's the thing: Lucity's dashboard abstracts Kubernetes the same way Coolify abstracts Docker. You interact with projects, services, and environments, not pods, deployments, and ingresses. The Kubernetes power is there when you need it, hidden when you don't.
### Ejectability
Coolify deploys your apps as Docker containers, which are portable. But Coolify itself has no eject command. If you outgrow Coolify or decide to leave, you're taking your Dockerfiles and rebuilding your deployment setup: reverse proxy config, environment variables, database connections, SSL, the works.
Lucity ejects to standard Kubernetes. Run `lucity eject` and you get a complete infrastructure-as-code setup: Helm charts, ArgoCD Application manifests, environment configs, and a README explaining how to run it all without Lucity. The platform is designed to be left.
### GitOps and Environment Promotion
Coolify deploys on push. Each environment builds independently from source. There's no concept of promoting a tested image from staging to production; each environment runs its own build.
Lucity uses ArgoCD for GitOps. Every deployment is a Git commit in a repository you own. Promotion copies an image tag from one environment to another. The exact image that passed staging tests runs in production. No rebuild, no "it works on my machine," no drift between environments.
For a solo developer deploying a side project, this distinction doesn't matter. For a team shipping a SaaS product with paying customers, it matters a lot.
### Stateless Architecture
Coolify stores its state in a database (SQLite or PostgreSQL). If that database is lost and you don't have a backup, you're reconfiguring everything from scratch. The Coolify instance is a single point of failure for deployments. If it goes down, you can't deploy (though running apps continue working).
Lucity has no central database. All state is derived from Kubernetes, Git, and the OCI registry. If the Lucity platform goes down entirely, your applications keep running, your GitOps repo still has your full deployment history, and you can recover or eject at any time. There's nothing to back up because there's no state that isn't already in a system designed for durability.
### Security Posture
In January 2026, Coolify disclosed 11 critical CVEs, including command injection, authentication bypass, and root-level code execution vulnerabilities. 52,000+ exposed instances were at risk. Seven of the CVEs were found by an AI pentesting tool.
For a platform that manages servers via SSH with root access, this is worth serious consideration. The Coolify team patched the issues, but the attack surface of a system that SSHs into servers and executes Docker commands is inherently large.
Lucity interacts with Kubernetes via the API server, uses OIDC for authentication, and stores secrets in Kubernetes Secrets (or external secret managers). The attack surface is Kubernetes-standard, which benefits from the security scrutiny of the entire CNCF ecosystem.
## The Honest Tradeoff
Coolify is simpler to set up and operate at small scale. That's not a minor advantage; it's the whole point. If you're running 1-5 services on 1-3 servers, Coolify gets you there faster with less infrastructure knowledge.
Lucity is more capable at larger scale and gives you a clean exit. If you're running a production SaaS with multiple environments, need GitOps workflows, or anticipate growing beyond what Docker Compose can handle, Lucity is built for that trajectory.
The question isn't "which is better." It's "where are you going?"
## Who Should Choose Coolify
- Solo developers and small teams self-hosting side projects or internal tools
- Teams deploying 1-10 services on a few servers who don't need Kubernetes
- Developers who want a Heroku-like experience on their own hardware, today
- Teams where simplicity and low cost matter more than scalability and portability
- Anyone who finds Kubernetes overkill for their current needs (and they might be right)
## Who Should Choose Lucity
- Teams building a SaaS product that will need to scale horizontally
- Teams that need GitOps with audit trails, environment promotion, and rollback
- Teams that want to own their infrastructure config and have a clean eject path
- Teams that need EU data residency for compliance (Swiss coming soon)
- Teams that anticipate outgrowing Docker Compose and want to avoid a painful migration later
- Teams that want open-source PaaS with production-grade Kubernetes under the hood
# PaaS Comparison: Lucity vs Railway, Render, Heroku, Fly.io, Coolify
The PaaS market has great options. Here's an honest look at how Lucity compares. We'll tell you where others excel and where we think we do better.
## Feature Comparison
| Feature | Lucity | Railway | Render | Heroku | Vercel | Fly.io | Coolify |
| --------------------- | ----------------------- | ----------- | ----------- | --------------- | ----------------- | -------------------------- | ----------- |
| **Open source** | AGPL-3.0 | No | No | No | No | No | Apache 2.0 |
| **Self-hostable** | Yes | No | No | No | No | No | Yes |
| **Ejectability** | Full | No | No | No | No | No | No |
| **Kubernetes native** | Yes | Hidden | Hidden | No | No | No (Firecracker) | No (Docker) |
| **EU hosting** | Yes (Swiss coming soon) | No | No | EU (Salesforce) | No | Yes (Amsterdam, Frankfurt) | BYOS |
| **GitOps (ArgoCD)** | Yes | Proprietary | Proprietary | Proprietary | Proprietary | No | No |
| **PR previews** | Yes | Yes | Yes | Add-on | Yes | Manual | Yes |
| **PostgreSQL** | CNPG | Yes | Yes | Yes | Neon (partner) | Managed ($38+/mo) | Yes |
| **Redis** | Yes | Yes | Yes | Yes | Upstash (partner) | Yes | Yes |
| **Cron jobs** | Yes | Yes | Yes | Add-on | Yes | Via Machines API | Yes |
| **Custom domains** | Yes | Yes | Yes | Yes | Yes | Yes | Yes |
| **CLI** | Coming soon | Yes | No | Yes | Yes | Yes | No |
## How to Read This
Every platform has strengths. Railway's polish is genuinely impressive. Render's simplicity is refreshing. Heroku pioneered the entire category. Vercel is unmatched for frontend deployment. Fly.io's global edge infrastructure is technically remarkable. Coolify proves open-source PaaS has a market.
Choose based on what matters to you:
- If **ejectability** matters (you want to own your infrastructure config and leave without a rewrite), that's where Lucity stands alone.
- If **open source** matters (you want to self-host, audit the code, or contribute), Lucity and Coolify are the only options in this list. Lucity runs on Kubernetes with GitOps; Coolify runs on Docker Compose.
- If **data residency** matters (you need EU hosting for compliance, with Swiss data residency coming soon), Lucity Cloud runs on European infrastructure.
- If **maximum polish** matters and lock-in isn't a concern, Railway and Vercel are excellent choices.
## Detailed Comparisons
We've written honest, detailed comparisons with each platform. We genuinely try to acknowledge where competitors do things better, because pretending otherwise would be insulting your intelligence.
- [Lucity vs Railway](https://lucity.cloud/comparisons/vs-railway): Railway's polish meets Lucity's freedom
- [Lucity vs Render](https://lucity.cloud/comparisons/vs-render): Render's simplicity vs Lucity's transparency
- [Lucity vs Heroku](https://lucity.cloud/comparisons/vs-heroku): The original PaaS meets its open-source successor
- [Lucity vs Vercel](https://lucity.cloud/comparisons/vs-vercel): Frontend-first vs full-stack
- [Lucity vs Fly.io](https://lucity.cloud/comparisons/vs-fly-io): Edge infrastructure vs ejectable Kubernetes
- [Lucity vs Coolify](https://lucity.cloud/comparisons/vs-coolify): Two open-source PaaS platforms, two architectures
# The European open-source alternative to Vercel, Heroku, and Railway
Ever since I deployed my first web app to Vercel (back when it was [still called ZEIT](https://vercel.com/blog/zeit-is-now-vercel)) as a teenager, I was hooked on the developer experience. Simple and intuitive, yet scalable enough for real projects.
At the time I was used to configuring Windows servers by hand, so it felt genuinely magical that infrastructure could be this effortless.
That fascination with infrastructure automation stuck with me. I have spent almost ten years as a software engineer on infrastructure automation projects, much of it on teams running containers at scale with Kubernetes. I saw first hand how a few well-chosen integrations can turn a plain cluster into a platform that is far greater than the sum of its parts.
So I always assumed Kubernetes would be the obvious foundation for a platform like this. That is why it surprised me to learn that Heroku, Vercel, and Railway were all built on proprietary container orchestration ([Heroku appears to have moved to Kubernetes in recent years](https://www.heroku.com/blog/next-generation-heroku-platform/)).
For a long time that was just an interesting technical detail. Then the recent geopolitical instability made something clear: these platforms fall under US jurisdiction, and with it the US CLOUD Act, which is more than a theoretical risk for a European business.
So I finally started building the platform I had been sketching in the back of my mind for years, with one goal:
> Replicate the developer experience of Vercel, Heroku, and Railway, on an open platform that never locks you in.
The result is Lucity. You can [try it for free](https://lucity.cloud/app/login). A few of the highlights:
- Git push to deploy
- Automated builds for your favorite languages and frameworks: Node.js, Next.js, Python, Go, PHP, Ruby, Rust, Java, Elixir, Bun, Deno, .NET, and static sites
- One-click PostgreSQL (replicated), S3-compatible object storage, and Redis-compatible key-value stores
- Tokenless deployments from GitHub Actions
- AI-native deployments powered by an MCP server and a Claude Code plugin
- Dynamic variables, so you reference credentials instead of hardcoding them
- Usage-based billing: pay only for what you use
- Vulnerability and leaked-credential scans on every commit
- Separate environments for development, staging, and production
- Logs, metrics, and observability built in
- Custom domains, private networking, and much more
And naturally, that headline feature is what makes "no lock-in" more than a slogan. When you want out, `lucity eject` hands you the full configuration as standard Helm charts, ready to run on any Kubernetes cluster with Lucity out of the picture. It works because Lucity keeps no database of its own: it derives all of its state from Kubernetes and the systems around it. Your infrastructure stays yours.
Lucity is under active development. Reach out at or open an issue at [github.com/zeitlos/lucity](https://github.com/zeitlos/lucity) for feature requests and bug reports.
It is also listed as a European alternative on:
- [European Tech Map](https://europeantechmap.eu/company/lucity)
- [euroalternative.eu](https://euroalternative.eu/lucity)
- [European Purpose](https://europeanpurpose.com/tool/lucity)
# The Software Deployment Trilemma
*An overview of all categories in respect to the trilemma.*
While building Lucity, I evaluated today's software deployment solutions and realized how the following trilemma applies to all of them: Scalable, Simple, Sovereign — pick two.
Ideally we want a solution that excels in all three aspects, but the trilemma dictates that a compromise in one aspect is inevitable. This is akin to [Zooko's triangle](https://en.wikipedia.org/wiki/Zooko%27s_triangle) or the [CAP theorem](https://en.wikipedia.org/wiki/CAP_theorem).
In this article, I will categorize existing software deployment solutions into three groups: PaaS, self-hosting tools, and Kubernetes. Each group will be evaluated according to the aspects of the trilemma.
At the end I'll come back to Lucity and show where it sits within this triangle. The ejectable architecture of Lucity means you can move around the triangle instead of being pinned to a fixed position.
Before we dive into the categories, here are my definitions of the three dimensions we're examining.
**Scalability** does not only apply to compute resources such as memory and CPU cores, but also geographical distribution and organization size. A truly scalable solution can support a large team working on a globally distributed deployment.
**Simplicity** measures the gradient of the learning curve as well as the extent of ongoing maintenance efforts for operating a production deployment. This includes initial setup, maintenance work, and security updates.
**Sovereignty** measures independence from third parties. This is not to be confused with self-hosting. Self-hostable software can also put you in a position where you are at the mercy of a third-party (think about the Broadcom VMware license debacle from recent years).
## 1. The Antichrist of Sovereignty: Platform as a Service
Platform as a Service (PaaS) solutions like Vercel, Heroku and Railway are the gold standard in terms of simplicity, allowing you to deploy a web service within minutes.
Over the years these platforms also established a solid quiver of scalability features: horizontal and vertical scaling, multiple geographical regions and CDN integrations ([but some don't seem to be able to manage their CDN properly](https://news.ycombinator.com/item?id=47581721)).
To no one's surprise, PaaS solutions fall short in terms of sovereignty. If you want to migrate off a PaaS you have to start from scratch. Like totally from scratch. This does not only mean writing Dockerfiles and building your CI/CD pipelines. It also means evaluating dozens of tools for managing deployments, observability, logs, containers, build pipelines, vulnerability scanning, and connectivity.
But that's just where the real work starts. Once you have defined your new stack, you'll need to train your teams on the technical concepts that were previously abstracted away by the PaaS. This includes things like VM lifecycles, OCI containers, networking, and VPN tunnels.
Today's PaaS hide the underlying infrastructure layer from developers. This means curious team members will hit a wall when trying to learn how their deployments work under the hood. PaaS solutions like Vercel, Railway or Heroku are essentially gatekeeping your team from acquiring that knowledge.
These aspects help to demonstrate that the inherent vendor lock-in of PaaS solutions is a very real liability for your business. Depending on your use case, this liability might be acceptable. I believe PaaS solutions are great for short-lived endeavours, such as education projects and experiments.
Platforms like Heroku have established a new paradigm of software deployment that still offers unmatched simplicity. Lucity's user experience aims to replicate that as closely as possible. Lucity also integrates [Railpack](https://railpack.com/getting-started), an open-source project by Railway that builds containerized applications directly from source code.
Lastly, I believe critical software should give you the choice between a managed cloud offering and hosting it yourself. If recent geopolitical developments taught us anything, it's that you should not put business-critical software at the mercy of a third-party without an exit hatch.
*PaaS solutions represent the gold-standard in terms of simplicity but fall short on sovereignty.*
## 2. "We have PaaS at home": Self-Hosting Tools
Remember the good ol' days where you just used ftp to copy some html and php to your apache web server?
```bash
ftp yourserver.com
put index.html
put contact.php
```
Over the years this workflow grew up, but the shape stayed the same. You own a server, manually install your software on it, and hope nothing breaks. For containerized apps this has evolved into SSHing in, pulling your code, building an image, and running it.
```bash
ssh user@yourserver.com
git pull
docker build -t myapp .
docker run -d --restart=always -p 80:80 myapp
```
Self-hosting tools like Coolify, Cap Rover or Dokku are the conceptual successor: they automate this workflow behind a UI.
Where these tools will start showing their limits is once you want to invite your team and collaborate on projects. Generally these tools are built to be operated by one person and they lack proper team management, SSO and audit features required by a team. Coolify's docs acknowledge that by stating that their teams feature "[isn't fully polished for production use](https://coolify.io/docs/get-started/concepts#teams)".
Once you look beyond organizational scaling, you will also notice that these tools fall short when it comes to scaling deployments beyond one server. Some of them support Docker Swarm for multi-server deployments, but I would advise against using that for new projects, since it's [officially retired](https://docs.docker.com/retired/#swarmkit).
Another limit you might encounter with these tools is that most of them have an unclear mid- to long-term roadmap. Furthermore, development and maintenance is often dependent on one single developer or a small team with limited experience. Recently, security company Aikido found [several high-severity CVEs in Coolify](https://www.aikido.dev/blog/ai-pentesting-coolify-cves). After skimming the CVEs I was surprised by the simplicity of these vulnerabilities, especially for an open-source project that has been around for years and accumulated over 50k GitHub stars.
It's good to see self-hosting tools like Coolify, Cap Rover or Dokku making sovereign software deployments more accessible. Just be sure you're aware of the limitations of these tools. I think these tools are great for hobby projects and deploying personal websites, but they really start to show their limits once your team grows beyond just you.
*Self-hosting tools are a solid sovereign option if you can live with the limited scalability they offer.*
## 3. Embrace the YAML: Kubernetes
Kubernetes is probably one of the most misunderstood technologies in the modern software engineering era.
As Kelsey Hightower famously said:
*Tweet by Kelsey Hightower, an iconic developer in the cloud-native ecosystem.*
Kubernetes is a wildly customizable abstraction layer for running containers across many servers. If you've ever manually deployed software across multiple VMs, you probably know how quickly this can get messy. The config will drift and debugging becomes very difficult. Kubernetes solves this problem by providing you with a unified API for managing your containers, storage, and configuration.
At its core, Kubernetes is essentially an extensible state machine backed by a distributed key-value store. This extensibility becomes incredibly valuable if you want to build your own virtualization platform or integrate it into your very specific data center setup. As a developer of [flex.plane](https://flexplane.io/), I appreciate that extensibility.
But here's where the misconception comes in. It's the reason behind all those frustrated LinkedIn and Reddit posts. Kubernetes was never designed to be used directly by application developers.
Granting a full-stack developer access to a Kubernetes cluster and instructing them to deploy their app is like passing a painter raw cotton, wooden planks, animal hair, and mineral pigments and asking them to paint a portrait. Everything they need to do their job is technically there, but they expected a canvas, brushes and paint. Someone was supposed to assemble the tools before the artist sat down to work. The same applies to Kubernetes.
So yes, technically teams can deploy their apps directly to Kubernetes. But for 95% of teams Kubernetes is an abstraction layer that sits too low. Kubernetes was designed to orchestrate containers on a massive scale. This is the reason it's the tool of choice for companies like Google, Amazon and Microsoft. But that does not mean it's unusable for smaller deployments.
Thanks to its open-source nature and the adoption of said companies, a rich ecosystem formed around Kubernetes over the years. This ecosystem includes tools for managing security, observability and compliance. Proven workflows and standards have emerged, and the industry has found consensus on best practices around cloud-native software deployment.
Exactly this expertise is the reason Lucity builds atop Kubernetes. Lucity makes Kubernetes accessible by automating a proven software deployment workflow on pre-configured infrastructure. This allows you to enjoy the strengths of the Kubernetes ecosystem without worrying about its complexity. And you get the peace of mind that the exit door is there when you need it.
*Kubernetes prioritizes scalability and extensibility at the cost of simplicity.*
## How Lucity Bends the Trilemma
Just like Vercel, Railway or Heroku, Lucity is a PaaS and shares most characteristics with this group: It's simple to get started and offers automated build & deploy pipelines, observability, scaling and security scanning.
But this is where Lucity differs from the other solutions: It allows you to export the underlying Helm chart, GitOps repo, and configuration and deploy them on any Kubernetes cluster. This is useful if you ever need customization beyond what's possible within the platform or if you need to use Kubernetes-specific features.
Additionally, Lucity is open-source (AGPLv3 license) and allows users to self-host the platform with the full feature set. While all major PaaS are operated by US companies, Lucity is built by [zeitlos.software](https://zeitlos.software/)—a Swiss company—and hosted in the EU, governed by strict privacy laws.
This makes Lucity the only solution that can move around the trilemma triangle instead of being pinned to a fixed position.
If that sounds interesting to you, give it a try and [sign up for a free trial](https://lucity.cloud/app/login?utm_source=blog&utm_medium=post&utm_campaign=software-deployment-trilemma).
*Lucity is the only trilemma shape that can change. Start with an open-source PaaS and eject to a full Kubernetes setup if you outgrow it.*
---
Thanks for reading this post on the software deployment trilemma. I'm interested to hear your questions, comments or feedback. Feel free to reach me at .
PS: This blog post was written by a real human.
]